
How to Fill PDF Form Fields in Python

Fill PDF forms programmatically in Python using IronPDF: load an existing PDF, locate each field by name, assign values, and save the result in just a few lines.
Quickstart: Fill PDF Form Fields1. Install IronPDF: `pip install ironpdf`
2. Load your PDF: `form_document = PdfDocument.FromFile("form.pdf")`
3. Find form field: `field = form_document.Form.FindFormField("fieldname")`
4. Set field value: `field.Value = "Your Value"`
5. Save filled PDF: `form_document.SaveAs("filled_form.pdf")`Minimal Workflow (5 steps)
- Install the IronPDF Python library
- Load an existing PDF document that contains form fields
- Access a form field by name using the
FindFormFieldmethod of the Form attribute - Assign a new value to the field's Value attribute
- Export the modified document using
SaveAs
Collecting data through a web UI and then generating a filled PDF for archiving or downstream processing is a common document automation pattern. Rather than manually transcribing data into PDF forms, Python scripts can handle this instantly: reading field names, populating values, and producing finished documents ready for storage or distribution.
IronPDF makes this workflow direct: one API to create forms from HTML, one method to locate a field by name, one property to set its value. PDF forms in the wild contain more than text inputs. Checkboxes, radio buttons, and dropdown fields are all supported through the same FindFormField and Value approach. The rest of this guide walks through the key scenarios: generating a form from HTML markup, filling fields in an existing document, reading all field types, and running bulk fills from a data source.
How Do I Create and Fill a PDF Form Using HTML in Python?
IronPDF can convert HTML <input> elements directly into editable PDF fields, giving you a direct path from a web-style form definition to a fillable PDF document. You can design forms with familiar HTML and CSS, then immediately populate them without an intermediate manual step.
The example below renders an HTML form as a PDF, then fills the firstname and lastname fields before saving the result.
from ironpdf import *

# Define HTML content for a simple form
form_html = """
<html>
<body>
<h2>Editable PDF Form</h2>
<form>
First name: <br> <input type='text' name='firstname' value=''> <br>
Last name: <br> <input type='text' name='lastname' value=''>
</form>
</body>
</html>
"""

# Instantiate a PDF renderer
renderer = ChromePdfRenderer()

# Enable HTML form-to-PDF-field conversion
renderer.RenderingOptions.CreatePdfFormsFromHtml = True

# Render the HTML content to a PDF file
renderer.RenderHtmlAsPdf(form_html).SaveAs("BasicForm.pdf")

# Load the created PDF document
form_document = PdfDocument.FromFile("BasicForm.pdf")

# Access the "firstname" field and set its value
first_name_field = form_document.Form.FindFormField("firstname")
first_name_field.Value = "Minnie"
print("FirstNameField value: {}".format(first_name_field.Value))

# Access the "lastname" field and set its value
last_name_field = form_document.Form.FindFormField("lastname")
last_name_field.Value = "Mouse"
print("LastNameField value: {}".format(last_name_field.Value))

# Save the filled form
form_document.SaveAs("FilledForm.pdf")Setting CreatePdfFormsFromHtml to True on the RenderingOptions attribute tells the renderer to translate each <input> element in the HTML into a corresponding interactive PDF field. Without this flag, text inputs render as static visual elements and cannot be filled programmatically.
After rendering, PdfDocument.FromFile loads the saved file back into memory. The FindFormField method accepts the field's name attribute as a string and returns a FormField object. Assigning to Value writes the data into the field. The SaveAs call writes the modified document to disk.
name attributes short and URL-safe. Spaces and special characters in field names work but can complicate downstream FindFormField lookups.What Does the Empty Form Look Like Before Filling?
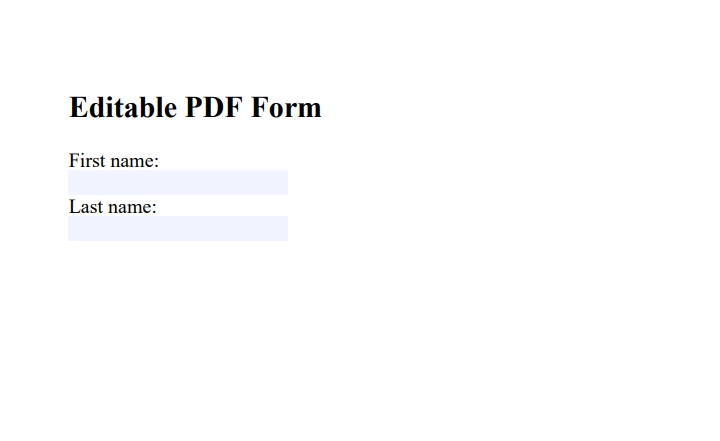
The rendered PDF preserves the visual layout of the HTML form. Each text input appears as a clickable, editable field. When the form is opened in a PDF reader, users can still type into fields manually, or the fields can be filled via the API as shown above.
What Does the Completed Form Look Like After Filling?
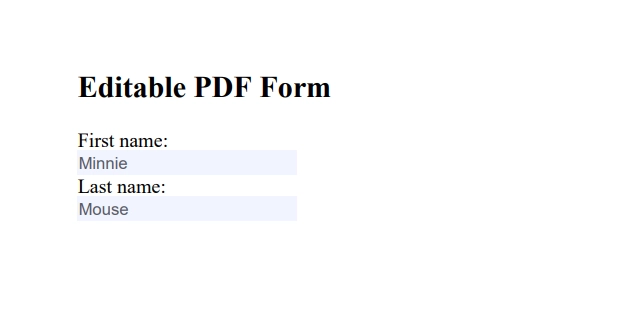
The filled document shows the values written to each field. The form structure and field interactivity are fully intact: the PDF can be saved as-is for archiving, or flattened to lock values in place for distribution.
How Do I Fill Fields in an Existing PDF Document?
Many real-world workflows involve PDF forms created in Adobe Acrobat, Word, or other tools. IronPDF can load any PDF containing AcroForm fields and populate them with the same FindFormField and Value API used when creating forms from HTML. AcroForm is the standard interactive form format defined in the PDF specification and is supported by all major PDF readers.
from ironpdf import *

# Load a pre-existing PDF with form fields
form_document = PdfDocument.FromFile("existing_form.pdf")

# Enumerate available field names (helpful when exploring an unfamiliar form)
for field in form_document.Form.Fields:
    print("Field name:", field.Name, "| Current value:", field.Value)

# Fill a specific field by name
applicant_name_field = form_document.Form.FindFormField("applicant_name")
applicant_name_field.Value = "Jane Smith"

# Fill a second field
date_field = form_document.Form.FindFormField("application_date")
date_field.Value = "2026-05-03"

# Save the filled document
form_document.SaveAs("submitted_application.pdf")Iterating form_document.Form.Fields before filling is useful when working with forms whose field names are not documented. The loop prints every field name and its current value, giving a complete map of what the form expects before any values are written.
How Do I Work with Checkboxes and Other Field Types?
Text fields are the most common form element, but real-world forms include checkboxes, radio buttons, and combo box dropdowns. IronPDF exposes all of these through the same Form.Fields collection. The Value property accepts the appropriate string for each type.
The table below shows the accepted values for the three most common non-text field types:
IronPDF PDF form field value conventions for non-text input types
| Field Type | HTML Input Type | Value to Set | Notes |
|---|---|---|---|
| Checkbox | type="checkbox" | "true" or "false" | Case-insensitive; use string, not boolean |
| Radio button | type="radio" | The value attribute of the option to select | Same name, different values per option |
| Dropdown (combo box) | <select> | The display text of the desired option | Must match an existing option exactly |
from ironpdf import *

# Load a form with multiple field types
form_document = PdfDocument.FromFile("application_form.pdf")

# Fill a text field
form_document.Form.FindFormField("full_name").Value = "Alex Rivera"

# Check a checkbox (use string "true")
form_document.Form.FindFormField("agree_terms").Value = "true"

# Select a radio button option by its value attribute
form_document.Form.FindFormField("employment_status").Value = "full_time"

# Select a dropdown option by display text
form_document.Form.FindFormField("country").Value = "United States"

form_document.SaveAs("completed_application.pdf")When iterating form_document.Form.Fields, each FormField object exposes a Name property and a Value property. For radio groups and dropdowns, printing the existing Value before writing will show you the current selection and confirm the expected format for that field.
FindFormField returns None, the field name does not exist in the document. Print all names via form_document.Form.Fields to verify spelling and confirm the field is present. Field names are case-sensitive.How Do I Fill Forms in Bulk from a Data Source?
Generating one filled PDF per record from a spreadsheet or database query is one of the most common reasons teams reach for programmatic form filling. IronPDF handles this by treating each fill operation as stateless: load the template, fill fields, save under a unique name, and repeat.
from ironpdf import *

# Sample data records (replace with database or CSV source)
applicants = [
    {"name": "Alice Johnson", "id": "A001", "date": "2026-05-03"},
    {"name": "Bob Williams", "id": "B002", "date": "2026-05-03"},
    {"name": "Carol Davis",  "id": "C003", "date": "2026-05-03"},
]

for applicant in applicants:
    # Load template from disk on each iteration to avoid cross-contamination
    form_document = PdfDocument.FromFile("application_template.pdf")

    # Fill each field from the data record
    form_document.Form.FindFormField("applicant_name").Value = applicant["name"]
    form_document.Form.FindFormField("applicant_id").Value   = applicant["id"]
    form_document.Form.FindFormField("submission_date").Value = applicant["date"]

    # Save each filled form with a unique filename
    output_path = f"output/application_{applicant['id']}.pdf"
    form_document.SaveAs(output_path)
print(f"Saved: {output_path}")Loading the template inside the loop, rather than once before it, prevents field values from accumulating across iterations. Each call to PdfDocument.FromFile produces a fresh copy of the template, so filling one record cannot affect the next.
PdfDocument.FromFile and using a copy mechanism if the API supports it. Benchmark both approaches against your volume requirements before deploying.IronPDF does not impose an artificial limit on how many documents a script can generate in a single run. Throughput is determined by available memory and the I/O speed of the output destination. For very large batches, writing to a local SSD and then transferring to network storage is faster than writing directly to a network share.
How Do I Flatten a Filled PDF Form?
Flattening converts interactive form fields into static page content, locking the current values in place. A flattened PDF is the right choice for archiving, printing, or sending to recipients who should not alter field values.
IronPDF provides a flatten form fields method that operates on any loaded PdfDocument. Call it after filling fields, then save the result.
from ironpdf import *

# Load and fill a form
form_document = PdfDocument.FromFile("application_template.pdf")
form_document.Form.FindFormField("full_name").Value = "Jordan Lee"
form_document.Form.FindFormField("application_date").Value = "2026-05-03"

# Flatten all form fields to lock values as static content
form_document.Form.Flatten()

# Save the flattened, non-editable PDF
form_document.SaveAs("archived_application.pdf")After Flatten(), the document no longer contains interactive field objects. Downstream systems that receive the file see ordinary text content rather than form widgets. This is important for PDF/A archival compliance and for preventing unintended edits in multi-step review pipelines.
How Do I Install IronPDF in Python?
IronPDF is available from PyPI. Install it with pip:
After installation, import the library at the top of each script with from ironpdf import *. A free trial license is available for evaluation. Production deployments require a commercial license key set via the License.LicenseKey property before any PDF operations run.
What Are the Next Steps for PDF Form Automation in Python?
This guide covered creating PDF forms from HTML, filling fields in existing documents, working with checkboxes and dropdown fields, generating batches of filled forms from data records, and flattening filled PDFs for archiving. Each technique uses the same core API: FindFormField to locate a field by name, Value to assign data, and SaveAs to write the result.
To explore related capabilities in IronPDF for Python:
- Create PDF forms from HTML templates: design full form layouts using HTML and CSS
- Edit and fill existing PDF forms: work with AcroForm fields in documents created outside IronPDF
- Flatten PDF form fields: lock field values in place for archiving or print-ready distribution
- Extract text and images from PDFs: read data back out of filled documents
- HTML to PDF conversion guide: in-depth coverage of the rendering pipeline IronPDF uses
- Explore the IronPDF Python source examples on GitHub: runnable code for all scenarios in this guide
Start a free trial to test form filling in your own Python project. When you're ready to deploy, view licensing options for individual developer and enterprise packages.
Frequently Asked Questions
What is the basic workflow to fill PDF forms using IronPDF in Python?
The basic workflow involves installing IronPDF, loading a PDF with form fields, accessing form fields by name using `FindFormField`, assigning values to those fields, and then saving the modified PDF using the `SaveAs` method.
How does IronPDF handle HTML input elements when creating PDF forms in Python?
IronPDF can convert HTML `` elements directly into interactive PDF fields. By setting `CreatePdfFormsFromHtml` to `True` in the `RenderingOptions`, it faithfully translates HTML forms into fillable PDF forms.
Is it possible to fill different types of form fields like checkboxes and drop-downs using IronPDF?
Yes, IronPDF supports filling various field types such as text inputs, checkboxes, radio buttons, and dropdowns using the `FindFormField` and `Value` methods to assign values accordingly.
Can IronPDF be used to fill forms in bulk from a data source using Python?
Yes, IronPDF allows you to load a PDF template, fill fields for each data record from a source like a spreadsheet or database, and save each filled form under a unique filename in a batch processing manner.
What does flattening a filled PDF form with IronPDF mean?
Flattening a filled PDF form converts the interactive form fields into static page content. This locks the current values in place, suitable for archiving or when the document needs to be non-editable.
How can I ensure the PDF fields are not editable before distribution?
By using the `Flatten` method in IronPDF after filling the form fields, you can ensure that the fields are converted into static text, making the document non-editable before distribution.
How do I enumerate all form fields in a PDF using IronPDF?
You can iterate through `form_document.Form.Fields` to list all available form fields and their current values in a PDF document, which helps in understanding the structure of a form.
What are the requirements to install IronPDF for Python?
IronPDF requires Python 3.6 or later and is available via PyPI. After installing with pip, import it in your script with `from ironpdf import *`. A free trial license is available for evaluation, with commercial options required for production use.
Does IronPDF support PDF forms with AcroForm fields?
Yes, IronPDF supports AcroForm fields, which are the standard interactive form format defined in the PDF specification. It can populate these fields using the same API as HTML-generated forms.
What is the recommended approach for filling forms with unclear field names?
When dealing with unclear field names, iterating through `form_document.Form.Fields` before filling them can provide a complete mapping of field names and their current values, aiding in filling the forms accurately.

Curtis Chau holds a Bachelor’s degree in Computer Science (Carleton University) and specializes in front-end development with expertise in Node.js, TypeScript, JavaScript, and React. Passionate about crafting intuitive and aesthetically pleasing user interfaces, Curtis enjoys working with modern frameworks and creating well-structured, visually appealing manuals.



