
Python PDF to Image Conversion

PDF-to-image conversion is a common requirement in Python applications. Developers use it to generate document thumbnails, web previews, and to feed PDF content into image processing pipelines. IronPDF for Python provides the RasterizeToImageFiles method, which converts any PDF document (or URL) into JPEG, PNG, or TIFF image files with configurable DPI and dimensions.
This guide shows how to convert PDF files to images in Python, how to control output quality, and how to size the resulting images to fit layout constraints.
Quickstart: Convert a PDF to Images- Install IronPDF:
pip install ironpdf - Load a PDF document:
pdf = PdfDocument.FromFile("document.pdf") - Convert every page to a PNG:
pdf.RasterizeToImageFiles("output/*.png", DPI=96)
#:path=/static-assets/pdf/content-code-examples/how-to/python-pdf-to-image/quickstart.py
from ironpdf import PdfDocument

pdf = PdfDocument.FromFile("document.pdf")
pdf.RasterizeToImageFiles("output/*.png", DPI=96)Minimal Workflow (5 steps)
- Install the IronPDF Python library
- Load a PDF with
PdfDocument.FromFileor render from a URL withChromePdfRenderer - Call
RasterizeToImageFileswith an output path pattern (e.g.,output/*.png) - Set
DPIto control image quality -- higher values produce sharper output - Use
ImageMaxWidthandImageMaxHeightto constrain output dimensions
Why Do Developers Convert PDFs to Images?
PDF-to-image conversion solves several practical problems in software development. The most common requirement is preview generation -- displaying a thumbnail of a PDF document in a web interface or mobile application without forcing users to download and open the full file.
Other frequent use cases include:
- Machine learning pipelines: OCR models, layout analysis tools, and computer vision systems accept image inputs, not PDFs
- Archival and compliance: Storing a visual snapshot alongside the original PDF ensures long-term readability even when PDF viewers change
- Report embedding: Including specific PDF pages as images inside other documents or email templates
- Automated testing: Comparing rendered page snapshots to detect visual regressions in PDF output
Python does not include native PDF-to-image functionality in its standard library. Tools like pdf2image require installing Poppler as an external binary, which adds deployment complexity. IronPDF handles rendering internally, so adding PDF-to-image conversion to any Python project requires only a single pip install.
How Do I Convert a PDF File to Images?
To convert a PDF to images, call RasterizeToImageFiles on a PdfDocument instance. The method writes one image file per page to the specified directory. The asterisk (*) in the output path is replaced by the page number starting from 1, so assets/images/*.png produces assets/images/1.png, assets/images/2.png, and so on.
Create the output directory before calling the method. IronPDF will not create it automatically if it does not exist.
#:path=/static-assets/pdf/content-code-examples/how-to/python-pdf-to-image/convert-pdf-to-images.py
from ironpdf import PdfDocument

# Load a PDF from disk
pdf = PdfDocument.FromFile("my-content.pdf")

# Write each page to a PNG file in the "assets/images" folder
# The folder must exist before calling this method
pdf.RasterizeToImageFiles("assets/images/*.png", DPI=96)The DPI parameter controls image resolution. A higher DPI produces a sharper image at the cost of larger file size and longer processing time. Standard values:
DPI Values and Typical Use Cases
| DPI | Typical Use |
|---|---|
| 72 | Screen resolution, fast processing |
| 96 | Standard web quality |
| 150 | Good print quality |
| 300 | High-quality print output |
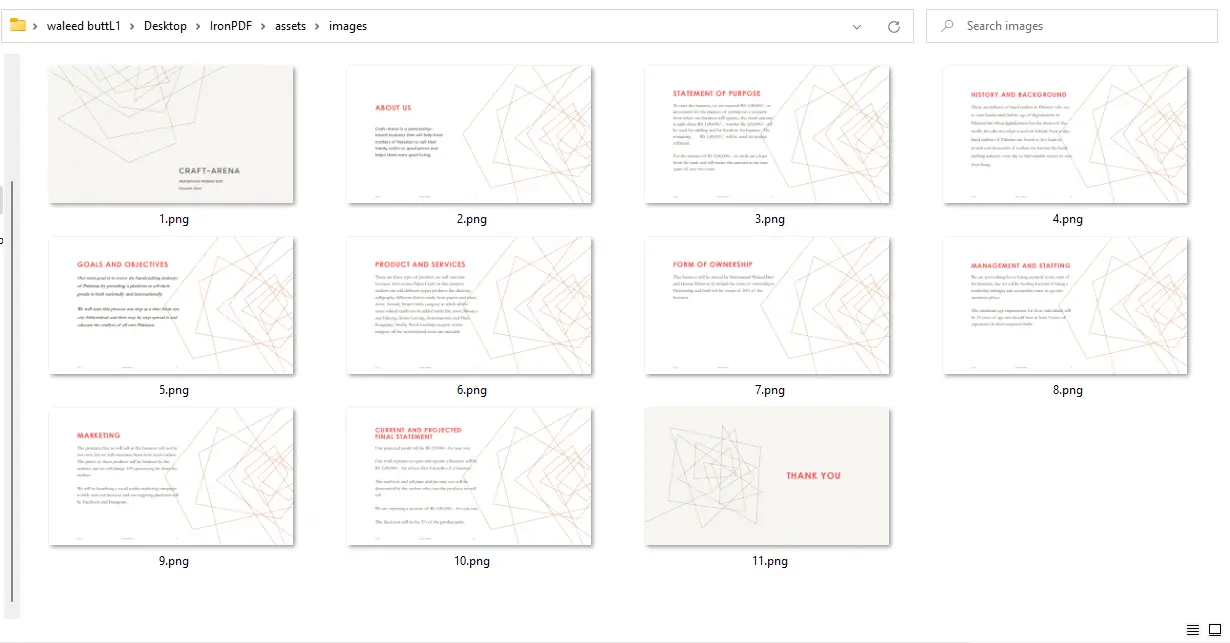
Output directory with one PNG file per PDF page
If output images appear blurry, increase the DPI value. Processing 300 DPI across a 50-page document takes noticeably longer than 96 DPI -- choose based on the actual quality requirements for the use case.
How Do I Convert a Specific Page Range to Images?
To convert only a subset of pages, pass the page indices as the second argument to RasterizeToImageFiles. Page indices are zero-based integers.
#:path=/static-assets/pdf/content-code-examples/how-to/python-pdf-to-image/convert-page-range.py
from ironpdf import PdfDocument

pdf = PdfDocument.FromFile("my-content.pdf")

# Convert only pages 1, 2, and 3 (zero-based indices: 0, 1, 2)
pdf.RasterizeToImageFiles("assets/images/*.png", [0, 1, 2], DPI=96)Selective page extraction is useful for documents where only the first few pages need to be previewed, avoiding unnecessary processing of the entire file. For workflows that extract images already embedded in a PDF, IronPDF provides separate extraction methods.
How Do I Convert a URL to Images?
IronPDF can render a web page to a PDF and then convert that PDF to images in a single workflow. Use ChromePdfRenderer to fetch and render the URL, then call RasterizeToImageFiles on the resulting PdfDocument. This approach creates visual archives of web pages or generates preview images for web-based content without requiring a separate screenshot tool.
#:path=/static-assets/pdf/content-code-examples/how-to/python-pdf-to-image/url-to-images.py
from ironpdf import ChromePdfRenderer

# Render a web page to PDF
renderer = ChromePdfRenderer()
pdf = renderer.RenderUrlAsPdf("https://www.example.com")

# Convert each rendered page to a PNG image
pdf.RasterizeToImageFiles("assets/images/*.png", DPI=96)The rendered images reflect how the page appears in a Chromium browser, including CSS styles and JavaScript-rendered content. For pages behind authentication or requiring interaction, consider using IronPDF's HTML to PDF tutorial to supply the pre-rendered markup directly. The resulting PDF can then be rasterized using the same approach shown above.
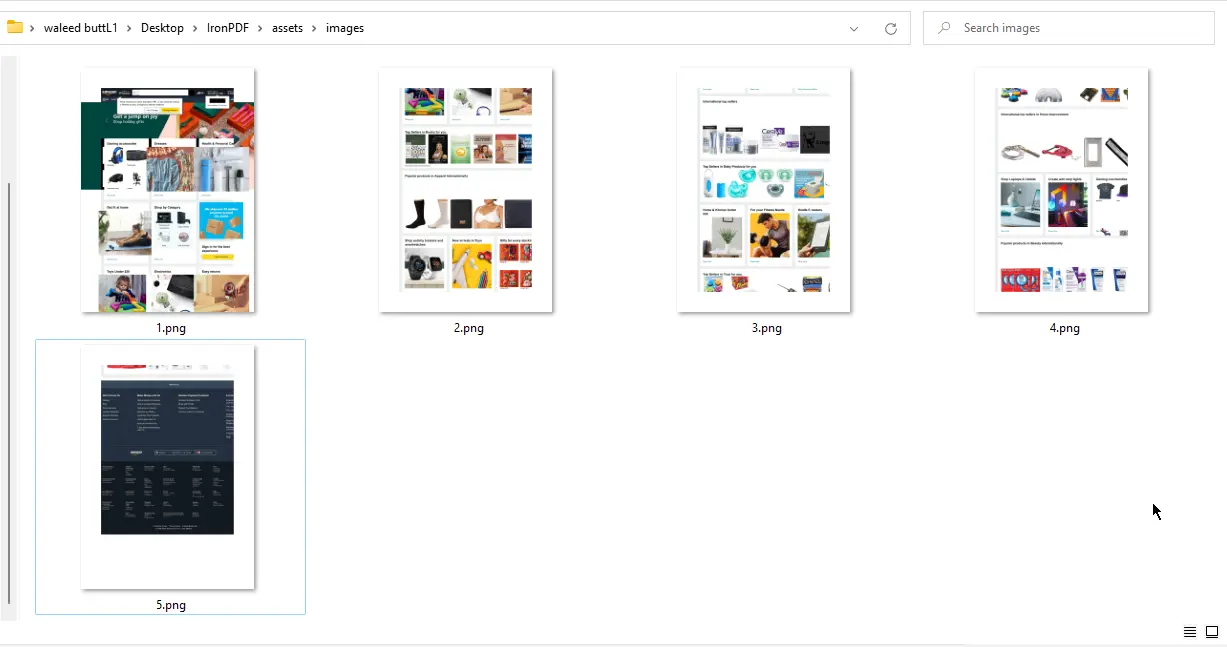
Images generated from a URL rendered through IronPDF
How Do I Control Output Image Dimensions?
By default, RasterizeToImageFiles generates images at the native page dimensions scaled by the DPI factor. To constrain the output size, set ImageMaxWidth and ImageMaxHeight, both measured in pixels.
IronPDF preserves the original aspect ratio based on the ImageMaxHeight value. The output will not be stretched or distorted even if the specified width and height have a different ratio than the source page.
#:path=/static-assets/pdf/content-code-examples/how-to/python-pdf-to-image/constrained-dimensions.py
from ironpdf import PdfDocument

pdf = PdfDocument.FromFile("my-content.pdf")

# Generate thumbnail images constrained to 500x500 pixels
pdf.RasterizeToImageFiles(
    "assets/images/*.png",
    ImageMaxWidth=500,
    ImageMaxHeight=500,
    DPI=200
)Setting ImageMaxWidth=500, ImageMaxHeight=500 at 200 DPI produces images suitable for thumbnail displays or card-based UI layouts. Adjust these values to match the dimensions required by the application design. To generate the PDF content being rasterized, IronPDF also supports creating PDFs from Python and merging multiple PDFs before conversion.
ImageMaxWidth. Design layouts to handle variable-width thumbnails.What Are the Next Steps for PDF to Image Conversion?
This guide covered three core workflows: converting a PDF file to images, converting a URL to images, and controlling image dimensions and quality. IronPDF supports JPEG, JPG, PNG, TIFF, and additional formats through the same RasterizeToImageFiles method. Change the file extension in the output path pattern to switch formats.
For further automation, consider these next steps:
- Batch processing: Loop over a directory of PDFs and convert each one in sequence, or use Python's
concurrent.futuresmodule for parallel processing - Selective extraction: Use the page index parameter to extract only the pages relevant to the use case
- Image pipeline integration: Feed the output files into PIL/Pillow or OpenCV for further processing such as cropping, annotation, or format normalization
- Compression before conversion: Use IronPDF's PDF compression to reduce file size before rasterizing large documents
- Form workflows: Fill PDF forms programmatically and then convert the completed form pages to images for review or archival
To continue building with IronPDF, explore the IronPDF for Python documentation and the rasterize PDF to images example.
Start a free 30-day trial of IronPDF for Python to use these features in production. When ready to deploy, view licensing options for the plan that fits the project scale.
Frequently Asked Questions
How can I convert a PDF to images using IronPDF in Python?
To convert a PDF to images in Python with IronPDF, use the 'RasterizeToImageFiles' method. You first load a PDF with 'PdfDocument.FromFile', then call the 'RasterizeToImageFiles' specifying the output format and resolution.
What image formats does IronPDF support for PDF conversion?
IronPDF supports converting PDF pages to JPEG, PNG, and TIFF formats by changing the file extension in the output path pattern in the 'RasterizeToImageFiles' method.
How do I adjust the image quality when converting PDFs to images with IronPDF?
Adjust the image quality using the 'DPI' parameter in the 'RasterizeToImageFiles' method. Higher DPI values result in sharper images but larger file sizes and longer processing times.
Can IronPDF be used to convert only specific pages of a PDF to images?
Yes, IronPDF allows selective page conversion by passing the page indices as a second argument to the 'RasterizeToImageFiles' method. This feature helps to process only the needed pages.
Is it possible to convert a URL to images with IronPDF?
Yes, IronPDF can render a web page as a PDF using 'ChromePdfRenderer' and then convert that PDF to images with 'RasterizeToImageFiles'. This allows generating visual archives of web content.
How do I control output image dimensions in IronPDF?
Use 'ImageMaxWidth' and 'ImageMaxHeight' parameters in 'RasterizeToImageFiles' to constrain image dimensions, maintaining the original aspect ratio based on 'ImageMaxHeight'.
Why is PDF-to-image conversion useful for developers?
PDF-to-image conversion is useful for creating document thumbnails, web previews, and integrating with image processing pipelines or machine learning models that require image input.
Does IronPDF automatically create output directories during conversion?
No, IronPDF does not create output directories automatically. You need to ensure that the directory exists before calling the 'RasterizeToImageFiles' method.
What are typical DPI values used with IronPDF for different use cases?
Common DPI values are 72 for fast processing and screen resolution, 96 for standard web quality, 150 for good print quality, and 300 for high-quality print output.
Can IronPDF handle converting embedded images within PDFs to separate image files?
Yes, IronPDF provides separate extraction methods to work with images already embedded in PDFs, which can be useful for specific workflows focusing on image content.

Curtis Chau holds a Bachelor’s degree in Computer Science (Carleton University) and specializes in front-end development with expertise in Node.js, TypeScript, JavaScript, and React. Passionate about crafting intuitive and aesthetically pleasing user interfaces, Curtis enjoys working with modern frameworks and creating well-structured, visually appealing manuals.



