


更新済み 2026年9月4日
月次口座明細書をPDF文書として生成する
IronPDF C# PDFライブラリを使用することで、開発者は外部サービスに依存することなく、.NETプロジェクト内でHTMLを信頼性の高いPDFファイルに変換することができます。
もっと読む

HTMLをPDFに変換することは、多くのソフトウェアアプリケーションにおいて一般的な要件であり、レポート、請求書の生成、またはウェブページをPDFとして保存することが含まれます。 この記事では、C#でのHTMLからPDFへの変換における3つの人気のあるオープンソースライブラリを探り、それらの強みと制限をレビューし、なぜIronPDFが多くのケースでより良い代替手段であるかを説明します。
PuppeteerSharpは、Puppeteer(ヘッドレスChromiumブラウザ) for .NETラッパーです。 Chromiumレンダリングエンジンを活用して、開発者がHTML文書をPDFに変換できます。
PuppeteerSharpは、レンダリングプロセスに対して正確な制御を提供します。 以下は例です:
using PuppeteerSharp;
using System.Threading.Tasks;

class Program
{
    static async Task Main(string[] args)
    {
        // Download Chromium to ensure compatibility with PuppeteerSharp
        await new BrowserFetcher().DownloadAsync(BrowserFetcher.DefaultChromiumRevision);

        // Launch a headless instance of Chromium browser
        using (var browser = await Puppeteer.LaunchAsync(new LaunchOptions { Headless = true }))
        {
            // Open a new browser page
            var page = await browser.NewPageAsync();

            // Set the HTML content for the page
            await page.SetContentAsync("<html><body><h1>Hello, PuppeteerSharp!</h1></body></html>");

            // Generate a PDF from the rendered HTML content
            await page.PdfAsync("output.pdf");
            Console.WriteLine("PDF Generated Successfully!");
        }
    }
}Imports PuppeteerSharp
Imports System.Threading.Tasks
Friend Class Program
Shared Async Function Main(ByVal args() As String) As Task
' Download Chromium to ensure compatibility with PuppeteerSharp
Await (New BrowserFetcher()).DownloadAsync(BrowserFetcher.DefaultChromiumRevision)
' Launch a headless instance of Chromium browser
Using browser = Await Puppeteer.LaunchAsync(New LaunchOptions With {.Headless = True})
' Open a new browser page
Dim page = Await browser.NewPageAsync()
' Set the HTML content for the page
Await page.SetContentAsync("<html><body><h1>Hello, PuppeteerSharp!</h1></body></html>")
' Generate a PDF from the rendered HTML content
Await page.PdfAsync("output.pdf")
Console.WriteLine("PDF Generated Successfully!")
End Using
End Function
End ClassImports PuppeteerSharp
Imports System.Threading.Tasks
Friend Class Program
Shared Async Function Main(ByVal args() As String) As Task
' Download Chromium to ensure compatibility with PuppeteerSharp
Await (New BrowserFetcher()).DownloadAsync(BrowserFetcher.DefaultChromiumRevision)
' Launch a headless instance of Chromium browser
Using browser = Await Puppeteer.LaunchAsync(New LaunchOptions With {.Headless = True})
' Open a new browser page
Dim page = Await browser.NewPageAsync()
' Set the HTML content for the page
Await page.SetContentAsync("<html><body><h1>Hello, PuppeteerSharp!</h1></body></html>")
' Generate a PDF from the rendered HTML content
Await page.PdfAsync("output.pdf")
Console.WriteLine("PDF Generated Successfully!")
End Using
End Function
End ClassChromiumをダウンロード: PuppeteerSharpは、互換性を確保するために必要なChromiumのバージョンを自動的にダウンロードします。
ブラウザを起動する: Puppeteer.LaunchAsync()を使用してChromiumのヘッドレスインスタンスを開始します。
HTMLコンテンツを設定する: page.SetContentAsync()を使用してブラウザページに目的のHTMLを読み込みます。
PDFを生成する: page.PdfAsync()メソッドを使用して、レンダリングされたコンテンツのPDFを生成します。
結果は、HTMLの構造とデザインを正確に再現した高品質のPDF (output.pdf) です。
PDFSharpは、C#でPDFファイルを作成および操作するための強力なオープンソースライブラリです。 HTMLレンダリングを直接サポートしてはいませんが、PDF文書をプログラムで生成および編集するためのツールを開発者に提供することに優れています。
PDF作成: PDFSharpを使用すると、開発者はページサイズを定義し、テキスト、形状、画像などを追加して新しいPDFファイルをゼロから生成できます。
既存のPDFの操作: 既存のPDF文書を変更(結合、分割、コンテンツ抽出など)できます。
描画機能: PDFSharpは、XGraphicsクラスを使用してPDFファイルにカスタムデザインを追加するための堅牢なグラフィック機能を提供します。
軽量: シンプルさとスピードを優先するプロジェクトに理想的な軽量ライブラリです。
using PdfSharp.Pdf;
using PdfSharp.Drawing;
using HtmlAgilityPack;

class Program
{
    static void Main(string[] args)
    {
        // Example HTML content
        string htmlContent = "<html><body><h1>Hello, PdfSharp!</h1><p>This is an example of HTML to PDF.</p></body></html>";

        // Parse HTML using HtmlAgilityPack (You need to add HtmlAgilityPack via NuGet)
        var htmlDoc = new HtmlDocument();
        htmlDoc.LoadHtml(htmlContent);

        // Create a new PDF document
        PdfDocument pdfDocument = new PdfDocument
        {
            Info = { Title = "HTML to PDF Example" }
        };

        // Add a new page to the document
        PdfPage page = pdfDocument.AddPage();

        XGraphics gfx = XGraphics.FromPdfPage(page);
        XFont titleFont = new XFont("Arial", 20, XFontStyle.Bold);
        XFont textFont = new XFont("Arial", 12, XFontStyle.Regular);

        // Draw the parsed HTML content
        int yPosition = 50; // Starting Y position
        foreach (var node in htmlDoc.DocumentNode.SelectNodes("//h1 | //p"))
        {
            if (node.Name == "h1")
            {
                gfx.DrawString(node.InnerText, titleFont, XBrushes.Black, new XRect(50, yPosition, page.Width - 100, page.Height - 100), XStringFormats.TopLeft);
                yPosition += 30; // Adjust spacing
            }
            else if (node.Name == "p")
            {
                gfx.DrawString(node.InnerText, textFont, XBrushes.Black, new XRect(50, yPosition, page.Width - 100, page.Height - 100), XStringFormats.TopLeft);
                yPosition += 20; // Adjust spacing
            }
        }

        // Save the PDF document
        string outputFilePath = "HtmlToPdf.pdf";
        pdfDocument.Save(outputFilePath);
        System.Console.WriteLine($"PDF file created: {outputFilePath}");
    }
}
using PdfSharp.Pdf;
using PdfSharp.Drawing;
using HtmlAgilityPack;
class Program
{
static void Main(string[] args)
{
// Example HTML content
string htmlContent = "<html><body><h1>Hello, PdfSharp!</h1><p>This is an example of HTML to PDF.</p></body></html>";
// Parse HTML using HtmlAgilityPack (You need to add HtmlAgilityPack via NuGet)
var htmlDoc = new HtmlDocument();
htmlDoc.LoadHtml(htmlContent);
// Create a new PDF document
PdfDocument pdfDocument = new PdfDocument
{
Info = { Title = "HTML to PDF Example" }
};
// Add a new page to the document
PdfPage page = pdfDocument.AddPage();
XGraphics gfx = XGraphics.FromPdfPage(page);
XFont titleFont = new XFont("Arial", 20, XFontStyle.Bold);
XFont textFont = new XFont("Arial", 12, XFontStyle.Regular);
// Draw the parsed HTML content
int yPosition = 50; // Starting Y position
foreach (var node in htmlDoc.DocumentNode.SelectNodes("//h1 | //p"))
{
if (node.Name == "h1")
{
gfx.DrawString(node.InnerText, titleFont, XBrushes.Black, new XRect(50, yPosition, page.Width - 100, page.Height - 100), XStringFormats.TopLeft);
yPosition += 30; // Adjust spacing
}
else if (node.Name == "p")
{
gfx.DrawString(node.InnerText, textFont, XBrushes.Black, new XRect(50, yPosition, page.Width - 100, page.Height - 100), XStringFormats.TopLeft);
yPosition += 20; // Adjust spacing
}
}
// Save the PDF document
string outputFilePath = "HtmlToPdf.pdf";
pdfDocument.Save(outputFilePath);
System.Console.WriteLine($"PDF file created: {outputFilePath}");
}
}Imports PdfSharp.Pdf
Imports PdfSharp.Drawing
Imports HtmlAgilityPack
Friend Class Program
Shared Sub Main(ByVal args() As String)
' Example HTML content
Dim htmlContent As String = "<html><body><h1>Hello, PdfSharp!</h1><p>This is an example of HTML to PDF.</p></body></html>"
' Parse HTML using HtmlAgilityPack (You need to add HtmlAgilityPack via NuGet)
Dim htmlDoc = New HtmlDocument()
htmlDoc.LoadHtml(htmlContent)
' Create a new PDF document
Dim pdfDocument As New PdfDocument With {
.Info = { Title = "HTML to PDF Example" }
}
' Add a new page to the document
Dim page As PdfPage = pdfDocument.AddPage()
Dim gfx As XGraphics = XGraphics.FromPdfPage(page)
Dim titleFont As New XFont("Arial", 20, XFontStyle.Bold)
Dim textFont As New XFont("Arial", 12, XFontStyle.Regular)
' Draw the parsed HTML content
Dim yPosition As Integer = 50 ' Starting Y position
For Each node In htmlDoc.DocumentNode.SelectNodes("//h1 | //p")
If node.Name = "h1" Then
gfx.DrawString(node.InnerText, titleFont, XBrushes.Black, New XRect(50, yPosition, page.Width - 100, page.Height - 100), XStringFormats.TopLeft)
yPosition += 30 ' Adjust spacing
ElseIf node.Name = "p" Then
gfx.DrawString(node.InnerText, textFont, XBrushes.Black, New XRect(50, yPosition, page.Width - 100, page.Height - 100), XStringFormats.TopLeft)
yPosition += 20 ' Adjust spacing
End If
Next node
' Save the PDF document
Dim outputFilePath As String = "HtmlToPdf.pdf"
pdfDocument.Save(outputFilePath)
System.Console.WriteLine($"PDF file created: {outputFilePath}")
End Sub
End ClassImports PdfSharp.Pdf
Imports PdfSharp.Drawing
Imports HtmlAgilityPack
Friend Class Program
Shared Sub Main(ByVal args() As String)
' Example HTML content
Dim htmlContent As String = "<html><body><h1>Hello, PdfSharp!</h1><p>This is an example of HTML to PDF.</p></body></html>"
' Parse HTML using HtmlAgilityPack (You need to add HtmlAgilityPack via NuGet)
Dim htmlDoc = New HtmlDocument()
htmlDoc.LoadHtml(htmlContent)
' Create a new PDF document
Dim pdfDocument As New PdfDocument With {
.Info = { Title = "HTML to PDF Example" }
}
' Add a new page to the document
Dim page As PdfPage = pdfDocument.AddPage()
Dim gfx As XGraphics = XGraphics.FromPdfPage(page)
Dim titleFont As New XFont("Arial", 20, XFontStyle.Bold)
Dim textFont As New XFont("Arial", 12, XFontStyle.Regular)
' Draw the parsed HTML content
Dim yPosition As Integer = 50 ' Starting Y position
For Each node In htmlDoc.DocumentNode.SelectNodes("//h1 | //p")
If node.Name = "h1" Then
gfx.DrawString(node.InnerText, titleFont, XBrushes.Black, New XRect(50, yPosition, page.Width - 100, page.Height - 100), XStringFormats.TopLeft)
yPosition += 30 ' Adjust spacing
ElseIf node.Name = "p" Then
gfx.DrawString(node.InnerText, textFont, XBrushes.Black, New XRect(50, yPosition, page.Width - 100, page.Height - 100), XStringFormats.TopLeft)
yPosition += 20 ' Adjust spacing
End If
Next node
' Save the PDF document
Dim outputFilePath As String = "HtmlToPdf.pdf"
pdfDocument.Save(outputFilePath)
System.Console.WriteLine($"PDF file created: {outputFilePath}")
End Sub
End ClassHTML解析: この例では、HtmlAgilityPack (HTMLの解析と操作のためのオープンソースライブラリ) が使用され、<p>タグからテキストコンテンツを抽出します。
コンテンツの描画: PDFSharpのXGraphicsクラスを使用して、解析されたHTMLコンテンツをPDFページにテキストとしてレンダリングします。
制限事項: このアプローチはシンプルなHTML構造には機能しますが、複雑なレイアウト、スタイル、またはJavaScriptを処理することはできません。
Pdfium.NETは、オープンソースプロジェクトPDFiumに基づいて設計された包括的なライブラリで、.NETアプリケーションのPDFファイルの閲覧、編集、操作を可能にします。 PDFの作成、編集、コンテンツの抽出を行うための強力なツールを開発者に提供し、幅広い用途に適しています。 基本的には、無料のHTMLからPDFへの変換ライブラリです。
PDFの作成と編集:
テキストおよび画像の抽出:
PDFビューアーコントロール:
互換性:
高度な機能:
using Pdfium.Net.SDK;
using System;

class Program
{
    static void Main(string[] args)
    {
        // Initialize Pdfium.NET SDK functionalities
        PdfCommon.Initialize();

        // Create a new PDF document
        PdfDocument pdfDocument = PdfDocument.CreateNew();

        // Add a page to the document (A4 size in points: 8.27 x 11.69 inches)
        var page = pdfDocument.Pages.InsertPageAt(pdfDocument.Pages.Count, 595, 842);

        // Sample HTML content to be parsed and rendered manually
        var htmlContent = "<h1>Hello, Pdfium.NET SDK!</h1><p>This is an example of HTML to PDF.</p>";

        // Example: Manually render text since Pdfium.NET doesn't render HTML directly
        var font = PdfFont.CreateFont(pdfDocument, "Arial");
        page.AddText(72, 750, font, 20, "Hello, Pdfium.NET SDK!");
        page.AddText(72, 700, font, 14, "This is an example of HTML to PDF.");

        // Save the document to a file
        string outputFilePath = "HtmlToPdfExample.pdf";
        pdfDocument.Save(outputFilePath, SaveFlags.Default);
        Console.WriteLine($"PDF created successfully: {outputFilePath}");
    }
}
using Pdfium.Net.SDK;
using System;
class Program
{
static void Main(string[] args)
{
// Initialize Pdfium.NET SDK functionalities
PdfCommon.Initialize();
// Create a new PDF document
PdfDocument pdfDocument = PdfDocument.CreateNew();
// Add a page to the document (A4 size in points: 8.27 x 11.69 inches)
var page = pdfDocument.Pages.InsertPageAt(pdfDocument.Pages.Count, 595, 842);
// Sample HTML content to be parsed and rendered manually
var htmlContent = "<h1>Hello, Pdfium.NET SDK!</h1><p>This is an example of HTML to PDF.</p>";
// Example: Manually render text since Pdfium.NET doesn't render HTML directly
var font = PdfFont.CreateFont(pdfDocument, "Arial");
page.AddText(72, 750, font, 20, "Hello, Pdfium.NET SDK!");
page.AddText(72, 700, font, 14, "This is an example of HTML to PDF.");
// Save the document to a file
string outputFilePath = "HtmlToPdfExample.pdf";
pdfDocument.Save(outputFilePath, SaveFlags.Default);
Console.WriteLine($"PDF created successfully: {outputFilePath}");
}
}Imports Pdfium.Net.SDK
Imports System
Friend Class Program
Shared Sub Main(ByVal args() As String)
' Initialize Pdfium.NET SDK functionalities
PdfCommon.Initialize()
' Create a new PDF document
Dim pdfDocument As PdfDocument = PdfDocument.CreateNew()
' Add a page to the document (A4 size in points: 8.27 x 11.69 inches)
Dim page = pdfDocument.Pages.InsertPageAt(pdfDocument.Pages.Count, 595, 842)
' Sample HTML content to be parsed and rendered manually
Dim htmlContent = "<h1>Hello, Pdfium.NET SDK!</h1><p>This is an example of HTML to PDF.</p>"
' Example: Manually render text since Pdfium.NET doesn't render HTML directly
Dim font = PdfFont.CreateFont(pdfDocument, "Arial")
page.AddText(72, 750, font, 20, "Hello, Pdfium.NET SDK!")
page.AddText(72, 700, font, 14, "This is an example of HTML to PDF.")
' Save the document to a file
Dim outputFilePath As String = "HtmlToPdfExample.pdf"
pdfDocument.Save(outputFilePath, SaveFlags.Default)
Console.WriteLine($"PDF created successfully: {outputFilePath}")
End Sub
End ClassImports Pdfium.Net.SDK
Imports System
Friend Class Program
Shared Sub Main(ByVal args() As String)
' Initialize Pdfium.NET SDK functionalities
PdfCommon.Initialize()
' Create a new PDF document
Dim pdfDocument As PdfDocument = PdfDocument.CreateNew()
' Add a page to the document (A4 size in points: 8.27 x 11.69 inches)
Dim page = pdfDocument.Pages.InsertPageAt(pdfDocument.Pages.Count, 595, 842)
' Sample HTML content to be parsed and rendered manually
Dim htmlContent = "<h1>Hello, Pdfium.NET SDK!</h1><p>This is an example of HTML to PDF.</p>"
' Example: Manually render text since Pdfium.NET doesn't render HTML directly
Dim font = PdfFont.CreateFont(pdfDocument, "Arial")
page.AddText(72, 750, font, 20, "Hello, Pdfium.NET SDK!")
page.AddText(72, 700, font, 14, "This is an example of HTML to PDF.")
' Save the document to a file
Dim outputFilePath As String = "HtmlToPdfExample.pdf"
pdfDocument.Save(outputFilePath, SaveFlags.Default)
Console.WriteLine($"PDF created successfully: {outputFilePath}")
End Sub
End ClassSDKの初期化: PdfCommon.Initialize()メソッドはPdfium.NETの機能を初期化します。
PDFの作成: PdfDocument.CreateNew()を使用して新しいPDFドキュメントが作成されます。
ページの追加: PDFにA4サイズなどの指定された寸法でページを挿入します。
HTMLコンテンツのレンダリング: Pdfium.NET SDKはHTMLレンダリングをネイティブでサポートしていないため、HTML要素を手動でテキスト、形状、または画像として解析およびレンダリングする必要があります。
PDFの保存: ドキュメントはSave()メソッドでファイルパスに保存されます。
IronPDFは、.NET開発者がHTMLコンテンツを高品質なPDFに簡単に変換できるように設計されたプロフェッショナルグレードのライブラリです。 その信頼性、洗練された機能、使いやすさで知られるIronPDFは、精密なレンダリングと堅牢な機能を提供しながら、開発プロセスを合理化します。 IronPDFが際立ったソリューションである理由は次のとおりです。
直接HTMLからPDFへの変換: IronPDFを使用して、CSSおよびJavaScriptを含むHTMLコンテンツを使用して直接PDF文書を作成し、完全にフォーマットされたPDFに変換します。 開発者は、数行のコードで、ウェブページ、生HTML文字列、またはローカルHTMLファイルからPDFを生成できます。
最新のレンダリング機能: 最新のウェブ標準をサポートし、IronPDFは複雑なレイアウト、スタイル、およびインタラクティブな要素の正確なレンダリングを保証し、HTMLページをPDFに変換します。
高度なPDF機能: IronPDFは、ヘッダー、フッター、ウォーターマーク、コメント、ブックマークを追加するなどの多くのカスタマイズオプションを提供します。 また、既存のPDFのマージ、分割、および編集もサポートしています。
パフォーマンスとスケーラビリティ: 小規模アプリケーションにも企業環境にも最適化されており、IronPDFはプロジェクトの規模に関わらず、高速で信頼性のあるパフォーマンスを提供します。
容易な統合: .NET Frameworkおよび.NET Core向けに設計されており、IronPDFはC#アプリケーションとスムーズに統合し、開発者にシンプルなセットアッププロセスと包括的なドキュメントを提供します。
IronPDFは、その機能、開発者サポート、およびパフォーマンスの組み合わせにより、他のソリューションの中で際立っています。 多くの場合、広範な構成や外部依存関係を必要とするオープンソースの代替手段と異なり、IronPDFは開発を簡素化しながら、機能を犠牲にしない自己完結型のソリューションです。 請求書、レポート、またはウェブコンテンツのアーカイブを生成する場合でも、IronPDFは、プロフェッショナルな結果を迅速かつ効率的に達成するために必要なツールを開発者に提供します。
IronPDFは、HTMLからPDFへのワークフローにおいて信頼性、スケーラビリティ、および使いやすさを重視する開発者にとって実用的な選択です。
using IronPdf;

class Program
{
    static void Main()
    {
        // Specify license key
        IronPdf.License.LicenseKey = "Your Key";

        // Create a new HtmlToPdf object using ChromePdfRenderer
        var Renderer = new ChromePdfRenderer();

        // Define the HTML string to be converted
        string htmlContent = "<html><body><h1>IronPDF: Better than Open source</h1></body></html>";

        // Convert the HTML string to a PDF document
        var document = Renderer.RenderHtmlAsPdf(htmlContent);

        // Save the PDF document to a file
        document.SaveAs("html2Pdf.pdf");

        Console.WriteLine("PDF generated and saved successfully!");
    }
}
using IronPdf;
class Program
{
static void Main()
{
// Specify license key
IronPdf.License.LicenseKey = "Your Key";
// Create a new HtmlToPdf object using ChromePdfRenderer
var Renderer = new ChromePdfRenderer();
// Define the HTML string to be converted
string htmlContent = "<html><body><h1>IronPDF: Better than Open source</h1></body></html>";
// Convert the HTML string to a PDF document
var document = Renderer.RenderHtmlAsPdf(htmlContent);
// Save the PDF document to a file
document.SaveAs("html2Pdf.pdf");
Console.WriteLine("PDF generated and saved successfully!");
}
}Imports IronPdf
Friend Class Program
Shared Sub Main()
' Specify license key
IronPdf.License.LicenseKey = "Your Key"
' Create a new HtmlToPdf object using ChromePdfRenderer
Dim Renderer = New ChromePdfRenderer()
' Define the HTML string to be converted
Dim htmlContent As String = "<html><body><h1>IronPDF: Better than Open source</h1></body></html>"
' Convert the HTML string to a PDF document
Dim document = Renderer.RenderHtmlAsPdf(htmlContent)
' Save the PDF document to a file
document.SaveAs("html2Pdf.pdf")
Console.WriteLine("PDF generated and saved successfully!")
End Sub
End ClassImports IronPdf
Friend Class Program
Shared Sub Main()
' Specify license key
IronPdf.License.LicenseKey = "Your Key"
' Create a new HtmlToPdf object using ChromePdfRenderer
Dim Renderer = New ChromePdfRenderer()
' Define the HTML string to be converted
Dim htmlContent As String = "<html><body><h1>IronPDF: Better than Open source</h1></body></html>"
' Convert the HTML string to a PDF document
Dim document = Renderer.RenderHtmlAsPdf(htmlContent)
' Save the PDF document to a file
document.SaveAs("html2Pdf.pdf")
Console.WriteLine("PDF generated and saved successfully!")
End Sub
End Class1.ライセンス キーの設定:プログラムは、ライブラリの全機能のロックを解除するために必要なIronPDFライセンス キーを設定することから始まります。
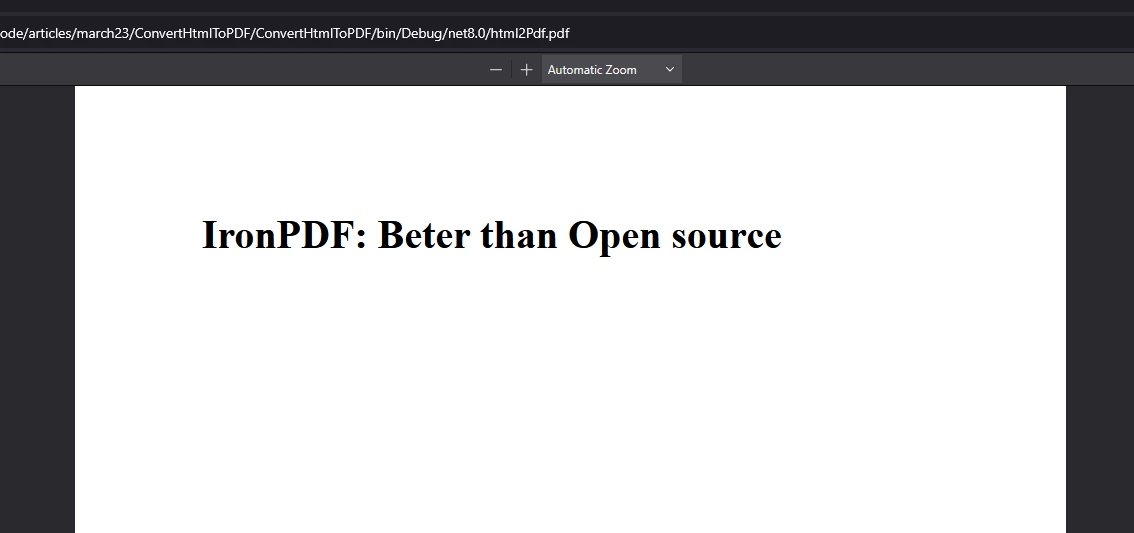
レンダラーの作成: ChromePdfRendererのインスタンスが初期化されます。 このコンポーネントは、HTMLコンテンツをPDF文書に変換する責任を持ち、未処理のHTMLと最終出力の間のブリッジとして機能します。
HTMLコンテンツの定義: HTML構造をPDFに変換するための文字列変数、htmlContentが作成されます。 この例では、シンプルな見出しを含んでいます。
HTMLをPDFに変換する: RenderHtmlAsPdf()メソッドが呼び出され、HTML文字列が入力として渡されます。 この機能はコンテンツを処理し、PDF文書に変換します。
PDFを保存する: 最後に、生成されたPDFを"html2Pdf.pdf"ファイルにSaveAs()メソッドを使用して保存し、将来のアクセスのためにディスクに保存します。
IronPDFは、有効なライセンスキーを必要とします。 公式ウェブサイトからトライアルライセンスを取得できます。IronPDFライブラリを使用する前に、以下のようにライセンスキーを設定してください。
IronPdf.License.LicenseKey = "your key";IronPdf.License.LicenseKey = "your key";IronPdf.License.LicenseKey = "your key"IronPdf.License.LicenseKey = "your key"これにより、ライブラリは制限なしで動作します。
PuppeteerSharpは、特に複雑なウェブページを扱う際に、HTMLからPDFの正確なレンダリングが必要な開発者にとって優れた選択肢です。 しかし、高度なPDF特有の機能、パフォーマンスの最適化、統合の容易さを必要とするアプリケーションには、プロフェッショナルなツールであるIronPDFがしばしばより良い選択肢です。
PDFSharpは、特にシンプルな要件を持つプロジェクトにとって、軽量でプログラムによるPDFの作成と操作に最適な選択です。 しかし、アプリケーションがHTMLからPDFへの変換や高度なPDF機能を必要とする場合、IronPDFはより効率的で機能豊富なソリューションを提供します。
Pdfium.NET SDKはPDF操作において強力なツールですが、IronPDFは現代のHTML、CSS、JavaScriptをレンダリングする直接のHTMLからPDFへの変換をネイティブにサポートしています。 IronPDFはHtmlToPdf.RenderHtmlAsPdf()のような組み込みメソッドでワークフローを簡略化し、開発者にとってより迅速で効率的です。
請求書、レポート、またはウェブコンテンツのアーカイブを生成する場合でも、IronPDFは、プロフェッショナルな結果を迅速かつ効率的に達成するために必要なツールを開発者に提供します。
IronPDFは、HTMLからPDFへのワークフローにおいて、信頼性、スケーラビリティ、および使いやすさを重視する開発者にとって実用的な選択です。

Curtis Chauは、カールトン大学でコンピュータサイエンスの学士号を取得し、Node.js、TypeScript、JavaScript、およびReactに精通したフロントエンド開発を専門としています。直感的で美しいユーザーインターフェースを作成することに情熱を持ち、Curtisは現代のフレームワークを用いた開発や、構造の良い視覚的に魅力的なマニュアルの作成を楽しんでいます。

IronPDF はIRONSUITEの一部です
オフィス文書用の10個の.NET API製品

PDFがHTMLのように見える必要があるとき、迅速に。
