



Updated April 21, 2026
How To Convert TIFF To PDF in Java
This comprehensive guide will walk you through the steps on how to convert TIFF image to PDF seamlessly in Java using IronPDF.
Read More

Reading a PDF document in Java can be an integral part of any project, ranging from business applications to data analytics. With the IronPDF library, it has become easier than ever before to integrate PDF processing capabilities into your Java projects.
fromFile methodextractAllText Method to Read Text from the Opened PDFIronPDF Java PDF Library Overview is the perfect solution for software developers who need to produce high-quality, capture-ready PDFs quickly from HTML. The library also provides powerful document manipulation tools that enable dynamic control over page layout and formatting in IronPDF, content, and formatting.
Let's see how to read a PDF file stored at a path in a Java program using the IronPDF library.
The first step is to install IronPDF using Maven; more details can be found in the IronPDF Installation Guide.
Here are the steps to install IronPDF in a Maven project:
Open your Maven project in your preferred IDE.
In the pom.xml file, add the IronPDF library dependency in the dependencies section.
<!-- Add this dependency to your pom.xml -->
<dependency>
    <groupId>com.ironsoftware</groupId>
    <artifactId>ironpdf</artifactId>
    <version>Your_IronPDF_Version_Here</version>
</dependency>Save the pom.xml file and let Maven download and install the IronPDF library.
Once the installation is complete, you should be able to import and use IronPDF's classes in your project.
Here is the code which you can use to read a file with or without tabular boundaries using the IronPDF library.
import com.ironsoftware.ironpdf.PdfDocument;
import java.io.IOException;
import java.nio.file.Paths;

/**
 * This class demonstrates how to read text from a PDF document using the IronPDF library.
 */
public class PdfReader {
    public static void main(String[] args) {
        try {
            // Load the PDF document from the specified file path
            PdfDocument pdf = PdfDocument.fromFile(Paths.get("C:\\sample.pdf"));

            // Extract all text content from the loaded PDF document
            String text = pdf.extractAllText();

            // Print the extracted text to the console
            System.out.println(text);
        } catch (IOException e) {
            // Handle exceptions that may occur during file loading or reading.
            e.printStackTrace();
        }
    }
}In this program, the PdfDocument class in IronPDF is used to read the contents of a PDF file. The main method creates a PdfDocument object by loading a PDF file from the specified file path "C:\sample.pdf" using the fromFile method. The extractAllText method is then called on this object to extract and return all text in the PDF as a String. The extracted text is printed to the console. The program includes error handling using try-catch blocks to manage potential IOException.
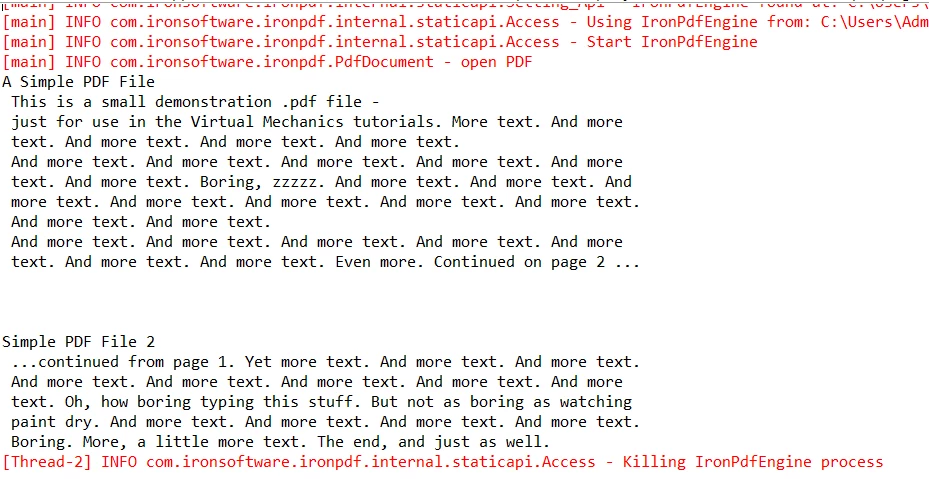 Program Output
IronPDF is a great solution for reading PDF files within the same path or multiple different paths in Java, as it offers high performance and many features that make developing PDFs easy. Its syntax is straightforward and user-friendly. Its API allows developers to quickly craft the code that they need for their projects.
Explore IronPDF Licensing Options plans start from just $999, making it accessible for those on a budget. Overall, IronPDF provides an excellent option for any Java developer looking to work with PDFs in their applications.

Curtis Chau holds a Bachelor’s degree in Computer Science (Carleton University) and specializes in front-end development with expertise in Node.js, TypeScript, JavaScript, and React. Passionate about crafting intuitive and aesthetically pleasing user interfaces, Curtis enjoys working with modern frameworks and creating well-structured, visually appealing manuals.



IronPDF is a part of IRONSUITE
10 .NET API products for your office documents


When you need your PDF to look like HTML, fast.

