Converting HTML to PDF is a common requirement in many software applications, such as generating reports, invoices, or saving web pages as PDFs. In this article, we'll explore seven popular open-source libraries for HTML to PDF conversion in C#, review their strengths and limitations, and discuss why IronPDF is a better alternative in numerous instances.
1. PuppeteerSharp
PuppeteerSharp is a .NET wrapper for Puppeteer, a headless Chromium browser. It enables developers to convert HTML documents to PDFs by leveraging the Chromium rendering engine.
PuppeteerSharp provides precise control over the rendering process. Here's an example:
using PuppeteerSharp;
using System.Threading.Tasks;

class Program
{
    static async Task Main(string[] args)
    {
        // Download Chromium to ensure compatibility with PuppeteerSharp
        await new BrowserFetcher().DownloadAsync(BrowserFetcher.DefaultChromiumRevision);

        // Launch a headless instance of Chromium browser
        using (var browser = await Puppeteer.LaunchAsync(new LaunchOptions { Headless = true }))
        {
            // Open a new browser page
            var page = await browser.NewPageAsync();

            // Set the HTML content for the page
            await page.SetContentAsync("<html><body><h1>Hello, PuppeteerSharp!</h1></body></html>");

            // Generate a PDF from the rendered HTML content
            await page.PdfAsync("output.pdf");
            Console.WriteLine("PDF Generated Successfully!");
        }
    }
}
using PuppeteerSharp;
using System.Threading.Tasks;

class Program
{
    static async Task Main(string[] args)
    {
        // Download Chromium to ensure compatibility with PuppeteerSharp
        await new BrowserFetcher().DownloadAsync(BrowserFetcher.DefaultChromiumRevision);

        // Launch a headless instance of Chromium browser
        using (var browser = await Puppeteer.LaunchAsync(new LaunchOptions { Headless = true }))
        {
            // Open a new browser page
            var page = await browser.NewPageAsync();

            // Set the HTML content for the page
            await page.SetContentAsync("<html><body><h1>Hello, PuppeteerSharp!</h1></body></html>");

            // Generate a PDF from the rendered HTML content
            await page.PdfAsync("output.pdf");
            Console.WriteLine("PDF Generated Successfully!");
        }
    }
}
Imports PuppeteerSharp
Imports System.Threading.Tasks
Friend Class Program
Shared Async Function Main(ByVal args() As String) As Task
' Download Chromium to ensure compatibility with PuppeteerSharp
Await (New BrowserFetcher()).DownloadAsync(BrowserFetcher.DefaultChromiumRevision)
' Launch a headless instance of Chromium browser
Using browser = Await Puppeteer.LaunchAsync(New LaunchOptions With {.Headless = True})
' Open a new browser page
Dim page = Await browser.NewPageAsync()
' Set the HTML content for the page
Await page.SetContentAsync("<html><body><h1>Hello, PuppeteerSharp!</h1></body></html>")
' Generate a PDF from the rendered HTML content
Await page.PdfAsync("output.pdf")
Console.WriteLine("PDF Generated Successfully!")
End Using
End Function
End Class
Imports PuppeteerSharp
Imports System.Threading.Tasks

Friend Class Program
	Shared Async Function Main(ByVal args() As String) As Task
		' Download Chromium to ensure compatibility with PuppeteerSharp
		Await (New BrowserFetcher()).DownloadAsync(BrowserFetcher.DefaultChromiumRevision)

		' Launch a headless instance of Chromium browser
		Using browser = Await Puppeteer.LaunchAsync(New LaunchOptions With {.Headless = True})
			' Open a new browser page
			Dim page = Await browser.NewPageAsync()

			' Set the HTML content for the page
			Await page.SetContentAsync("<html><body><h1>Hello, PuppeteerSharp!</h1></body></html>")

			' Generate a PDF from the rendered HTML content
			Await page.PdfAsync("output.pdf")
			Console.WriteLine("PDF Generated Successfully!")
		End Using
	End Function
End Class
Code Explanation
- Download Chromium: PuppeteerSharp automatically downloads the required Chromium version to ensure compatibility.
- Launch Browser: Start a headless instance of Chromium using
Puppeteer.LaunchAsync().
- Set HTML Content: Load the desired HTML into the browser page using
page.SetContentAsync().
- Generate PDF: Use the
page.PdfAsync() method to generate a PDF of the rendered content.
The result is a high-quality PDF (output.pdf) that accurately replicates the HTML structure and design.
Pros
- High Fidelity Rendering: Supports modern web technologies, including advanced CSS and JavaScript.
- Automation Capabilities: Besides PDFs, PuppeteerSharp can automate web browsing, testing, and data extraction.
- Active Development: PuppeteerSharp is actively maintained and regularly updated.
Cons
- Large File Size: Requires downloading and bundling the Chromium browser, increasing deployment size.
- Resource Intensive: Running a browser instance can be heavy on system resources, especially for large-scale applications.
- Limited PDF-Specific Features: PuppeteerSharp focuses on rendering rather than enhancing PDFs (e.g., adding headers or footers).
2. PDFSharp
PDFSharp is a powerful open-source library for creating and manipulating PDF files in C#. While it doesn't directly support HTML rendering, it excels at providing developers with tools to generate and edit PDF documents programmatically.
Key Features of PDFSharp
- PDF Creation: PDFSharp allows developers to generate new PDF files from scratch by defining page sizes, adding text, shapes, images, and more.
- Manipulation of Existing PDFs: You can modify existing PDF documents, such as merging, splitting, or extracting content.
- Drawing Capabilities: PDFSharp provides robust graphics capabilities for adding custom designs to PDF files using the XGraphics class.
- Lightweight: It is a lightweight library, making it ideal for projects where simplicity and speed are priorities.
using PdfSharp.Pdf;
using PdfSharp.Drawing;
using HtmlAgilityPack;

class Program
{
    static void Main(string[] args)
    {
        // Example HTML content
        string htmlContent = "<html><body><h1>Hello, PdfSharp!</h1><p>This is an example of HTML to PDF.</p></body></html>";

        // Parse HTML using HtmlAgilityPack (You need to add HtmlAgilityPack via NuGet)
        var htmlDoc = new HtmlDocument();
        htmlDoc.LoadHtml(htmlContent);

        // Create a new PDF document
        PdfDocument pdfDocument = new PdfDocument
        {
            Info = { Title = "HTML to PDF Example" }
        };

        // Add a new page to the document
        PdfPage page = pdfDocument.AddPage();

        XGraphics gfx = XGraphics.FromPdfPage(page);
        XFont titleFont = new XFont("Arial", 20, XFontStyle.Bold);
        XFont textFont = new XFont("Arial", 12, XFontStyle.Regular);

        // Draw the parsed HTML content
        int yPosition = 50; // Starting Y position
        foreach (var node in htmlDoc.DocumentNode.SelectNodes("//h1 | //p"))
        {
            if (node.Name == "h1")
            {
                gfx.DrawString(node.InnerText, titleFont, XBrushes.Black, new XRect(50, yPosition, page.Width - 100, page.Height - 100), XStringFormats.TopLeft);
                yPosition += 30; // Adjust spacing
            }
            else if (node.Name == "p")
            {
                gfx.DrawString(node.InnerText, textFont, XBrushes.Black, new XRect(50, yPosition, page.Width - 100, page.Height - 100), XStringFormats.TopLeft);
                yPosition += 20; // Adjust spacing
            }
        }

        // Save the PDF document
        string outputFilePath = "HtmlToPdf.pdf";
        pdfDocument.Save(outputFilePath);
        System.Console.WriteLine($"PDF file created: {outputFilePath}");
    }
}
using PdfSharp.Pdf;
using PdfSharp.Drawing;
using HtmlAgilityPack;

class Program
{
    static void Main(string[] args)
    {
        // Example HTML content
        string htmlContent = "<html><body><h1>Hello, PdfSharp!</h1><p>This is an example of HTML to PDF.</p></body></html>";

        // Parse HTML using HtmlAgilityPack (You need to add HtmlAgilityPack via NuGet)
        var htmlDoc = new HtmlDocument();
        htmlDoc.LoadHtml(htmlContent);

        // Create a new PDF document
        PdfDocument pdfDocument = new PdfDocument
        {
            Info = { Title = "HTML to PDF Example" }
        };

        // Add a new page to the document
        PdfPage page = pdfDocument.AddPage();

        XGraphics gfx = XGraphics.FromPdfPage(page);
        XFont titleFont = new XFont("Arial", 20, XFontStyle.Bold);
        XFont textFont = new XFont("Arial", 12, XFontStyle.Regular);

        // Draw the parsed HTML content
        int yPosition = 50; // Starting Y position
        foreach (var node in htmlDoc.DocumentNode.SelectNodes("//h1 | //p"))
        {
            if (node.Name == "h1")
            {
                gfx.DrawString(node.InnerText, titleFont, XBrushes.Black, new XRect(50, yPosition, page.Width - 100, page.Height - 100), XStringFormats.TopLeft);
                yPosition += 30; // Adjust spacing
            }
            else if (node.Name == "p")
            {
                gfx.DrawString(node.InnerText, textFont, XBrushes.Black, new XRect(50, yPosition, page.Width - 100, page.Height - 100), XStringFormats.TopLeft);
                yPosition += 20; // Adjust spacing
            }
        }

        // Save the PDF document
        string outputFilePath = "HtmlToPdf.pdf";
        pdfDocument.Save(outputFilePath);
        System.Console.WriteLine($"PDF file created: {outputFilePath}");
    }
}
Imports PdfSharp.Pdf
Imports PdfSharp.Drawing
Imports HtmlAgilityPack
Friend Class Program
Shared Sub Main(ByVal args() As String)
' Example HTML content
Dim htmlContent As String = "<html><body><h1>Hello, PdfSharp!</h1><p>This is an example of HTML to PDF.</p></body></html>"
' Parse HTML using HtmlAgilityPack (You need to add HtmlAgilityPack via NuGet)
Dim htmlDoc = New HtmlDocument()
htmlDoc.LoadHtml(htmlContent)
' Create a new PDF document
Dim pdfDocument As New PdfDocument With {
.Info = { Title = "HTML to PDF Example" }
}
' Add a new page to the document
Dim page As PdfPage = pdfDocument.AddPage()
Dim gfx As XGraphics = XGraphics.FromPdfPage(page)
Dim titleFont As New XFont("Arial", 20, XFontStyle.Bold)
Dim textFont As New XFont("Arial", 12, XFontStyle.Regular)
' Draw the parsed HTML content
Dim yPosition As Integer = 50 ' Starting Y position
For Each node In htmlDoc.DocumentNode.SelectNodes("//h1 | //p")
If node.Name = "h1" Then
gfx.DrawString(node.InnerText, titleFont, XBrushes.Black, New XRect(50, yPosition, page.Width - 100, page.Height - 100), XStringFormats.TopLeft)
yPosition += 30 ' Adjust spacing
ElseIf node.Name = "p" Then
gfx.DrawString(node.InnerText, textFont, XBrushes.Black, New XRect(50, yPosition, page.Width - 100, page.Height - 100), XStringFormats.TopLeft)
yPosition += 20 ' Adjust spacing
End If
Next node
' Save the PDF document
Dim outputFilePath As String = "HtmlToPdf.pdf"
pdfDocument.Save(outputFilePath)
System.Console.WriteLine($"PDF file created: {outputFilePath}")
End Sub
End Class
Imports PdfSharp.Pdf
Imports PdfSharp.Drawing
Imports HtmlAgilityPack

Friend Class Program
	Shared Sub Main(ByVal args() As String)
		' Example HTML content
		Dim htmlContent As String = "<html><body><h1>Hello, PdfSharp!</h1><p>This is an example of HTML to PDF.</p></body></html>"

		' Parse HTML using HtmlAgilityPack (You need to add HtmlAgilityPack via NuGet)
		Dim htmlDoc = New HtmlDocument()
		htmlDoc.LoadHtml(htmlContent)

		' Create a new PDF document
		Dim pdfDocument As New PdfDocument With {
			.Info = { Title = "HTML to PDF Example" }
		}

		' Add a new page to the document
		Dim page As PdfPage = pdfDocument.AddPage()

		Dim gfx As XGraphics = XGraphics.FromPdfPage(page)
		Dim titleFont As New XFont("Arial", 20, XFontStyle.Bold)
		Dim textFont As New XFont("Arial", 12, XFontStyle.Regular)

		' Draw the parsed HTML content
		Dim yPosition As Integer = 50 ' Starting Y position
		For Each node In htmlDoc.DocumentNode.SelectNodes("//h1 | //p")
			If node.Name = "h1" Then
				gfx.DrawString(node.InnerText, titleFont, XBrushes.Black, New XRect(50, yPosition, page.Width - 100, page.Height - 100), XStringFormats.TopLeft)
				yPosition += 30 ' Adjust spacing
			ElseIf node.Name = "p" Then
				gfx.DrawString(node.InnerText, textFont, XBrushes.Black, New XRect(50, yPosition, page.Width - 100, page.Height - 100), XStringFormats.TopLeft)
				yPosition += 20 ' Adjust spacing
			End If
		Next node

		' Save the PDF document
		Dim outputFilePath As String = "HtmlToPdf.pdf"
		pdfDocument.Save(outputFilePath)
		System.Console.WriteLine($"PDF file created: {outputFilePath}")
	End Sub
End Class
Code Explanation
- HTML Parsing: The example uses HtmlAgilityPack (an open-source library for parsing and manipulating HTML) to extract text content from
<h1> and <p> tags.
- Drawing Content: PDFSharp's XGraphics class is used to render the parsed HTML content as text on a PDF page.
- Limitations: This approach works for simple HTML structures but won't handle complex layouts, styles, or JavaScript.
Pros and Cons of PDFSharp
Pros
- Lightweight and Easy to Use: PDFSharp is intuitive and straightforward, making it ideal for developers starting with PDF generation.
- Open-Source and Free: No licensing fees, and the source code is available for customization.
- Custom Drawing: Provides excellent capabilities for creating PDFs from scratch with custom designs.
Cons
- No HTML to PDF Conversion: PDFSharp does not natively support rendering HTML to PDF, requiring additional libraries for parsing HTML.
- Limited Support for Modern Features: Does not provide advanced capabilities like interactive PDFs, digital signatures, or annotations.
- Performance Constraints: May not be as optimized as professional libraries for large-scale or enterprise applications.
3. Pdfium.NET SDK
Pdfium.NET is a comprehensive library based on the open-source PDFium project, designed for viewing, editing, and manipulating PDF files in .NET applications. It provides developers with powerful tools to create, edit, and extract content from PDFs, making it suitable for a wide range of use cases. It is basically a free HTML to PDF converter library.
Key Features of Pdfium.NET SDK
- PDF Creation and Editing:
- Generate PDFs from scratch or from scanned images.
- Edit existing PDFs by adding text, images, or annotations.
- Text and Image Extraction:
- Extract text and images from PDF file format documents for further processing.
- Search for specific text within a PDF document.
- PDF Viewer Control:
- Embed a standalone PDF viewer in WinForms or WPF applications.
- Supports zooming, scrolling, bookmarks, and text search.
- Compatibility:
- Works with .NET Framework, .NET Core, .NET Standard, and .NET 6+.
- Compatible with Windows and macOS platforms.
- Advanced Features:
- Merge and split PDF files.
- Render PDFs as images for display or printing.
using Pdfium.Net.SDK;
using System;

class Program
{
    static void Main(string[] args)
    {
        // Initialize Pdfium.NET SDK functionalities
        PdfCommon.Initialize();

        // Create a new PDF document
        PdfDocument pdfDocument = PdfDocument.CreateNew();

        // Add a page to the document (A4 size in points: 8.27 x 11.69 inches)
        var page = pdfDocument.Pages.InsertPageAt(pdfDocument.Pages.Count, 595, 842);

        // Sample HTML content to be parsed and rendered manually
        var htmlContent = "<h1>Hello, Pdfium.NET SDK!</h1><p>This is an example of HTML to PDF.</p>";

        // Example: Manually render text since Pdfium.NET doesn't render HTML directly
        var font = PdfFont.CreateFont(pdfDocument, "Arial");
        page.AddText(72, 750, font, 20, "Hello, Pdfium.NET SDK!");
        page.AddText(72, 700, font, 14, "This is an example of HTML to PDF.");

        // Save the document to a file
        string outputFilePath = "HtmlToPdfExample.pdf";
        pdfDocument.Save(outputFilePath, SaveFlags.Default);
        Console.WriteLine($"PDF created successfully: {outputFilePath}");
    }
}
using Pdfium.Net.SDK;
using System;

class Program
{
    static void Main(string[] args)
    {
        // Initialize Pdfium.NET SDK functionalities
        PdfCommon.Initialize();

        // Create a new PDF document
        PdfDocument pdfDocument = PdfDocument.CreateNew();

        // Add a page to the document (A4 size in points: 8.27 x 11.69 inches)
        var page = pdfDocument.Pages.InsertPageAt(pdfDocument.Pages.Count, 595, 842);

        // Sample HTML content to be parsed and rendered manually
        var htmlContent = "<h1>Hello, Pdfium.NET SDK!</h1><p>This is an example of HTML to PDF.</p>";

        // Example: Manually render text since Pdfium.NET doesn't render HTML directly
        var font = PdfFont.CreateFont(pdfDocument, "Arial");
        page.AddText(72, 750, font, 20, "Hello, Pdfium.NET SDK!");
        page.AddText(72, 700, font, 14, "This is an example of HTML to PDF.");

        // Save the document to a file
        string outputFilePath = "HtmlToPdfExample.pdf";
        pdfDocument.Save(outputFilePath, SaveFlags.Default);
        Console.WriteLine($"PDF created successfully: {outputFilePath}");
    }
}
Imports Pdfium.Net.SDK
Imports System
Friend Class Program
Shared Sub Main(ByVal args() As String)
' Initialize Pdfium.NET SDK functionalities
PdfCommon.Initialize()
' Create a new PDF document
Dim pdfDocument As PdfDocument = PdfDocument.CreateNew()
' Add a page to the document (A4 size in points: 8.27 x 11.69 inches)
Dim page = pdfDocument.Pages.InsertPageAt(pdfDocument.Pages.Count, 595, 842)
' Sample HTML content to be parsed and rendered manually
Dim htmlContent = "<h1>Hello, Pdfium.NET SDK!</h1><p>This is an example of HTML to PDF.</p>"
' Example: Manually render text since Pdfium.NET doesn't render HTML directly
Dim font = PdfFont.CreateFont(pdfDocument, "Arial")
page.AddText(72, 750, font, 20, "Hello, Pdfium.NET SDK!")
page.AddText(72, 700, font, 14, "This is an example of HTML to PDF.")
' Save the document to a file
Dim outputFilePath As String = "HtmlToPdfExample.pdf"
pdfDocument.Save(outputFilePath, SaveFlags.Default)
Console.WriteLine($"PDF created successfully: {outputFilePath}")
End Sub
End Class
Imports Pdfium.Net.SDK
Imports System

Friend Class Program
	Shared Sub Main(ByVal args() As String)
		' Initialize Pdfium.NET SDK functionalities
		PdfCommon.Initialize()

		' Create a new PDF document
		Dim pdfDocument As PdfDocument = PdfDocument.CreateNew()

		' Add a page to the document (A4 size in points: 8.27 x 11.69 inches)
		Dim page = pdfDocument.Pages.InsertPageAt(pdfDocument.Pages.Count, 595, 842)

		' Sample HTML content to be parsed and rendered manually
		Dim htmlContent = "<h1>Hello, Pdfium.NET SDK!</h1><p>This is an example of HTML to PDF.</p>"

		' Example: Manually render text since Pdfium.NET doesn't render HTML directly
		Dim font = PdfFont.CreateFont(pdfDocument, "Arial")
		page.AddText(72, 750, font, 20, "Hello, Pdfium.NET SDK!")
		page.AddText(72, 700, font, 14, "This is an example of HTML to PDF.")

		' Save the document to a file
		Dim outputFilePath As String = "HtmlToPdfExample.pdf"
		pdfDocument.Save(outputFilePath, SaveFlags.Default)
		Console.WriteLine($"PDF created successfully: {outputFilePath}")
	End Sub
End Class
Code Explanation
- SDK Initialization: The
PdfCommon.Initialize() method initializes Pdfium.NET functionalities.
- Creating a PDF: A new PDF document is created using
PdfDocument.CreateNew().
- Adding Pages: Pages are inserted into the PDF with specified dimensions (e.g., A4 size).
- Rendering HTML Content: Since Pdfium.NET SDK does not natively support HTML rendering, you need to manually parse and render HTML elements as text, shapes, or images.
- Saving the PDF: The document is saved to a file path with the
Save() method.
Pros
- Allows full control over PDF creation and editing.
- Flexible for drawing and adding text, images, and shapes.
- Powerful capabilities for viewing and manipulating PDFs in desktop applications.
Cons
- Does not directly convert HTML to PDF.
- Parsing and rendering HTML manually can be complex and time-consuming.
- Best suited for applications focusing on PDF editing and manipulation rather than HTML conversion.
4. QuestPDF
QuestPDF is a modern, code-first PDF generation library for .NET. Instead of parsing existing markup, it uses a fluent C# API to compose a document's layout directly in code, with a companion desktop app for live, hot-reload previews during development. It regularly comes up alongside PuppeteerSharp and IronPDF in "open source HTML to PDF C#" searches, so it's worth covering here, but it solves a different problem than the other libraries in this list.
QuestPDF does not convert HTML to PDF. There is no HTML or CSS parser anywhere in the library. If you already have HTML content, such as an email template or a CMS page, you'd need to rebuild that layout using QuestPDF's fluent API rather than converting the markup directly.
using QuestPDF.Fluent;
using QuestPDF.Infrastructure;
using QuestPDF.Helpers;

// Required before generating any document under the free Community License
QuestPDF.Settings.License = LicenseType.Community;

Document.Create(container =>
{
    container.Page(page =>
    {
        page.Size(PageSizes.A4);
        page.Margin(2, Unit.Centimetre);
        page.PageColor(Colors.White);
        page.DefaultTextStyle(x => x.FontSize(12));

        page.Header()
            .Text("Hello, QuestPDF!")
            .FontSize(20)
            .Bold()
            .AlignCenter();

        page.Content()
            .Text("This document was composed entirely in C# code, not converted from HTML.");
    });
}).GeneratePdf("output.pdf");
using QuestPDF.Fluent;
using QuestPDF.Infrastructure;
using QuestPDF.Helpers;

// Required before generating any document under the free Community License
QuestPDF.Settings.License = LicenseType.Community;

Document.Create(container =>
{
    container.Page(page =>
    {
        page.Size(PageSizes.A4);
        page.Margin(2, Unit.Centimetre);
        page.PageColor(Colors.White);
        page.DefaultTextStyle(x => x.FontSize(12));

        page.Header()
            .Text("Hello, QuestPDF!")
            .FontSize(20)
            .Bold()
            .AlignCenter();

        page.Content()
            .Text("This document was composed entirely in C# code, not converted from HTML.");
    });
}).GeneratePdf("output.pdf");
C#
Code Explanation
- License Declaration:
QuestPDF.Settings.License must be set once per process before generating a document; LicenseType.Community applies to the free tier.
- Document.Create: Defines the document as a tree of fluent method calls rather than a rendered HTML string.
- Page Configuration:
page.Size(), page.Margin(), and page.DefaultTextStyle() set up the page geometry and default typography in code.
- Header and Content:
page.Header() and page.Content() are chained fluent calls that describe layout, not HTML elements being parsed.
- GeneratePdf: Renders the composed document tree to a PDF file on disk.
Pros
- Free for Small Businesses: The Community License is free for individuals, open-source projects, and companies with under USD 1,000,000 in annual gross revenue.
- Fluent, Type-Safe API: Layout is checked at compile time, and the companion hot-reload previewer speeds up iteration.
- Lightweight Deployment: No headless browser or external binary is required, which makes it easy to run in constrained environments like Azure Functions or Docker containers.
Cons
- No HTML or CSS Parsing: Existing web pages, email templates, or CMS content must be rebuilt in code; there is no rendering engine to convert them.
- Revenue-Based Licensing: Once a company's annual gross revenue passes USD 1,000,000, a paid Professional or Enterprise license is required regardless of how much of the library is actually used.
- No Built-In Document Security: Encryption, redaction, digital signatures, and watermarking each require a separate library.
Learn more in IronPDF's dedicated QuestPDF HTML to PDF comparison.
5. wkhtmltopdf
wkhtmltopdf is a command-line tool that renders HTML pages to PDF using the Qt WebKit engine. For years it was the default answer to "free HTML to PDF" in C#, typically invoked from .NET through a wrapper package such as DinkToPdf or NReco.PdfGenerator.
The project is no longer maintained. Its GitHub repository was archived on January 2, 2023, and the wkhtmltopdf GitHub organization itself was marked archived on July 10, 2024. The last stable release, 0.12.6, shipped on June 10, 2020, and development on the underlying QtWebKit rendering engine had already stalled back in 2017. An unpatched server-side request forgery vulnerability, CVE-2022-35583 (CVSS 9.8), remains open in the last release.
using DinkToPdf;
using DinkToPdf.Contracts;

var converter = new BasicConverter(new PdfTools());

var doc = new HtmlToPdfDocument()
{
    GlobalSettings = {
        ColorMode = ColorMode.Color,
        Orientation = Orientation.Portrait,
        PaperSize = PaperKind.A4
    },
    Objects = {
        new ObjectSettings()
        {
            HtmlContent = "<html><body><h1>Hello, wkhtmltopdf!</h1></body></html>"
        }
    }
};

byte[] pdfBytes = converter.Convert(doc);
System.IO.File.WriteAllBytes("output.pdf", pdfBytes);
using DinkToPdf;
using DinkToPdf.Contracts;

var converter = new BasicConverter(new PdfTools());

var doc = new HtmlToPdfDocument()
{
    GlobalSettings = {
        ColorMode = ColorMode.Color,
        Orientation = Orientation.Portrait,
        PaperSize = PaperKind.A4
    },
    Objects = {
        new ObjectSettings()
        {
            HtmlContent = "<html><body><h1>Hello, wkhtmltopdf!</h1></body></html>"
        }
    }
};

byte[] pdfBytes = converter.Convert(doc);
System.IO.File.WriteAllBytes("output.pdf", pdfBytes);
C#
Code Explanation
- BasicConverter Setup: DinkToPdf's
BasicConverter wraps the native wkhtmltopdf binary via P/Invoke.
- GlobalSettings: Configures page-level options such as color mode, orientation, and paper size.
- ObjectSettings:
HtmlContent supplies the HTML string to be rendered; a file path or URL can be used instead.
- Convert: Calling
converter.Convert() shells out to the native library and returns the finished PDF as a byte array.
- Saving the PDF: The byte array is written to disk with
File.WriteAllBytes().
Pros
- No License Cost: wkhtmltopdf is released under LGPLv3, which permits use in proprietary applications without exposing your own source code.
- Simple for One-Off Conversions: The command-line interface converts a file with a single call, with no code required.
- Wide Language Support: In addition to C# wrappers, it has been used from PHP, Python, Ruby, and Node.js.
Cons
- Archived and Unmaintained: No commits or releases since 2020; both the repository and its GitHub organization are now archived.
- Unpatched Critical Vulnerability: CVE-2022-35583, a CVSS 9.8 SSRF flaw, has no official fix.
- Outdated Rendering Engine: The bundled QtWebKit engine predates reliable CSS Grid and Flexbox support and cannot execute modern JavaScript.
- External Process Dependency: Every conversion shells out to a native binary, which adds deployment overhead and expands the attack surface compared to a managed library.
Learn more in IronPDF's dedicated wkhtmltopdf C# guide.
6. iText7 (pdfHTML)
iText7 is a mature, enterprise-focused PDF library for .NET and Java. HTML to PDF conversion isn't part of the core package; it requires the separate pdfhtml add-on module, installed alongside it. NuGet package IDs changed in 2026: itext7 and itext7.pdfhtml are now deprecated aliases, and current installs should use itext and itext.pdfhtml instead.
using iText.Html2pdf;
using System.IO;

class Program
{
    static void Main(string[] args)
    {
        using (FileStream htmlSource = File.Open("input.html", FileMode.Open))
        using (FileStream pdfDest = File.Open("output.pdf", FileMode.Create))
        {
            ConverterProperties converterProperties = new ConverterProperties();
            HtmlConverter.ConvertToPdf(htmlSource, pdfDest, converterProperties);
        }
    }
}
using iText.Html2pdf;
using System.IO;

class Program
{
    static void Main(string[] args)
    {
        using (FileStream htmlSource = File.Open("input.html", FileMode.Open))
        using (FileStream pdfDest = File.Open("output.pdf", FileMode.Create))
        {
            ConverterProperties converterProperties = new ConverterProperties();
            HtmlConverter.ConvertToPdf(htmlSource, pdfDest, converterProperties);
        }
    }
}
C#
Code Explanation
- Package Requirements: Both
itext and itext.pdfhtml must be installed; the base library does not include HTML rendering on its own.
- File Streams:
htmlSource and pdfDest are opened as standard FileStream objects for input and output.
- ConverterProperties: Configures conversion behavior, such as a base URI for resolving relative asset paths.
- HtmlConverter.ConvertToPdf: Reads the HTML stream and writes the resulting PDF directly to the destination stream.
Pros
- Enterprise Feature Set: Beyond conversion, iText7 covers forms, digital signatures, compression, and low-level content extraction.
- Actively Maintained: Regular releases with a long, well-documented history; pdfHTML added CSS Grid support in version 5.0.5 (August 2024) alongside its existing Flexbox support.
- Strong Documentation: The iText Knowledge Base covers most common conversion and manipulation scenarios in depth.
Cons
- Dual AGPL/Commercial License: iText7 and pdfHTML are licensed under AGPL by default; most closed-source commercial applications cannot comply with AGPL's copyleft terms and need a paid commercial license instead.
- No JavaScript Execution: Client-side rendered or dynamically generated HTML content will not convert correctly, regardless of how well the CSS itself is supported.
- Two Packages to Manage:
itext and itext.pdfhtml are versioned and installed separately.
- Recent Package Rename: Projects following older tutorials may still reference the deprecated
itext7/itext7.pdfhtml package IDs; migrating means updating to itext/itext.pdfhtml.
Learn more in IronPDF's dedicated iText7 HTML to PDF comparison.
7. PdfPig
PdfPig is an open-source, Apache 2.0-licensed library and a .NET port of Java's PDFBox. It focuses on reading and extracting content from existing PDFs, including letter positions, bounding boxes, and font metadata, rather than generating new ones.
PdfPig cannot convert HTML to PDF. It has no HTML or CSS parser and no layout engine for markup. It's included here because it surfaces frequently in "open source PDF C#" searches, but if HTML to PDF conversion is the goal, PdfPig isn't a candidate. Its PdfDocumentBuilder can create very basic PDFs from scratch, limited to plain text, lines, and simple shapes placed by coordinate.
using UglyToad.PdfPig;

using (PdfDocument document = PdfDocument.Open("input.pdf"))
{
    foreach (var page in document.GetPages())
    {
        string text = page.Text;
        Console.WriteLine($"Page {page.Number}: {text}");
    }
}
using UglyToad.PdfPig;

using (PdfDocument document = PdfDocument.Open("input.pdf"))
{
    foreach (var page in document.GetPages())
    {
        string text = page.Text;
        Console.WriteLine($"Page {page.Number}: {text}");
    }
}
C#
Code Explanation
- PdfDocument.Open: Opens an existing PDF file for reading; PdfPig does not render or convert HTML.
- GetPages: Iterates through each page of the document.
- page.Text: Returns the extracted text content for that page, built from individual letter positions. PdfPig's own documentation cautions against using this property directly for anything reading-order-sensitive, since it follows the PDF's content stream order rather than visual layout; use its layout-analysis extractors instead when word order matters (for example, invoice totals appearing before line items).
Pros
- Permissive Licensing: Apache 2.0 imposes no revenue thresholds or copyleft obligations.
- Strong Text Extraction: Letter-level positioning, bounding boxes, and font metadata make it well suited to data mining and document analysis.
- Lightweight: No external binaries or browser engine, which makes it a good fit for serverless environments.
Cons
- No HTML to PDF Conversion: There is no markup parser of any kind in the library.
- No Document Security Authoring: PdfPig can open encrypted PDFs when given a password, but it has no way to add encryption, redaction, digital signatures, or watermarking to output.
- Minimal PDF Creation:
PdfDocumentBuilder supports only basic text and shapes, with no layout engine.
- Rendering Requires an Add-On: Converting pages to images needs the separate
PdfPig.Rendering.Skia package.
Learn more in IronPDF's dedicated PdfPig C# alternatives guide.
Introducing IronPDF
IronPDF is a professional-grade library designed for .NET developers to effortlessly convert HTML content into high-quality PDFs. Known for its reliability, advanced features, and ease of use, IronPDF streamlines the development process while delivering precise rendering and robust functionality. Here's why IronPDF is a standout solution:
Key Features
- Direct HTML to PDF Conversion: Create PDF documents directly using IronPDF with HTML content, including CSS and JavaScript, into fully formatted PDFs. With just a few lines of code, developers can generate PDFs from web pages, raw HTML strings, or local HTML files.
- Modern Rendering Capabilities: Supporting the latest web standards, IronPDF ensures accurate rendering of complex layouts, styles, and interactive elements to convert HTML pages to PDF.
- Advanced PDF Features: IronPDF offers extensive customization options, such as adding headers, footers, watermarks, annotations, and bookmarks. It also supports merging, splitting, and editing existing PDFs.
- Performance and Scalability: Optimized for both small-scale applications and enterprise environments, IronPDF delivers fast, reliable performance for projects of any size.
- Ease of Integration: Designed for .NET Framework and .NET Core, IronPDF integrates smoothly with C# applications, offering developers a straightforward setup process and comprehensive documentation.
Why Choose IronPDF?
IronPDF stands out among other solutions due to its combination of features, developer support, and performance. Unlike open-source alternatives that often require extensive configuration or external dependencies, IronPDF is a self-contained solution that simplifies development without sacrificing functionality. Whether it's for generating invoices, reports, or archiving web content, IronPDF empowers developers with the tools they need to achieve professional-grade results quickly and efficiently.
IronPDF is a practical choice for developers who value reliability, scalability, and ease of use in their HTML to PDF workflows.
How to convert HTML to PDF using IronPDF
using IronPdf;

class Program
{
    static void Main()
    {
        // Specify license key
        IronPdf.License.LicenseKey = "Your Key";

        // Create a new HtmlToPdf object using ChromePdfRenderer
        var Renderer = new ChromePdfRenderer();

        // Define the HTML string to be converted
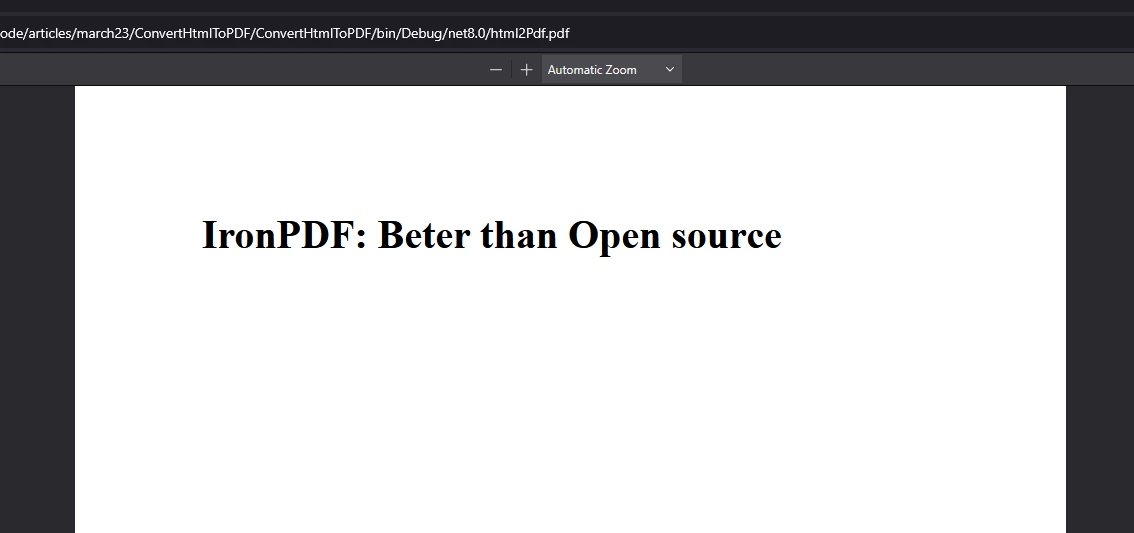
        string htmlContent = "<html><body><h1>IronPDF: Better than Open source</h1></body></html>";

        // Convert the HTML string to a PDF document
        var document = Renderer.RenderHtmlAsPdf(htmlContent);

        // Save the PDF document to a file
        document.SaveAs("html2Pdf.pdf");

        Console.WriteLine("PDF generated and saved successfully!");
    }
}
using IronPdf;

class Program
{
    static void Main()
    {
        // Specify license key
        IronPdf.License.LicenseKey = "Your Key";

        // Create a new HtmlToPdf object using ChromePdfRenderer
        var Renderer = new ChromePdfRenderer();

        // Define the HTML string to be converted
        string htmlContent = "<html><body><h1>IronPDF: Better than Open source</h1></body></html>";

        // Convert the HTML string to a PDF document
        var document = Renderer.RenderHtmlAsPdf(htmlContent);

        // Save the PDF document to a file
        document.SaveAs("html2Pdf.pdf");

        Console.WriteLine("PDF generated and saved successfully!");
    }
}
Imports IronPdf
Friend Class Program
Shared Sub Main()
' Specify license key
IronPdf.License.LicenseKey = "Your Key"
' Create a new HtmlToPdf object using ChromePdfRenderer
Dim Renderer = New ChromePdfRenderer()
' Define the HTML string to be converted
Dim htmlContent As String = "<html><body><h1>IronPDF: Better than Open source</h1></body></html>"
' Convert the HTML string to a PDF document
Dim document = Renderer.RenderHtmlAsPdf(htmlContent)
' Save the PDF document to a file
document.SaveAs("html2Pdf.pdf")
Console.WriteLine("PDF generated and saved successfully!")
End Sub
End Class
Imports IronPdf

Friend Class Program
	Shared Sub Main()
		' Specify license key
		IronPdf.License.LicenseKey = "Your Key"

		' Create a new HtmlToPdf object using ChromePdfRenderer
		Dim Renderer = New ChromePdfRenderer()

		' Define the HTML string to be converted
		Dim htmlContent As String = "<html><body><h1>IronPDF: Better than Open source</h1></body></html>"

		' Convert the HTML string to a PDF document
		Dim document = Renderer.RenderHtmlAsPdf(htmlContent)

		' Save the PDF document to a file
		document.SaveAs("html2Pdf.pdf")

		Console.WriteLine("PDF generated and saved successfully!")
	End Sub
End Class
Code Snippet Explanation
- License Key Setup: The program starts by setting the IronPDF license key, which is required to unlock the full functionality of the library.
- Creating the Renderer: An instance of
ChromePdfRenderer is initialized. This component is responsible for converting HTML content into a PDF document, acting as a bridge between the raw HTML and the final output.
- Defining HTML Content: A string variable,
htmlContent, is created to store the HTML structure that will be converted into a PDF. In this example, it contains a simple heading.
- Converting HTML to PDF: The
RenderHtmlAsPdf() method is called on the ChromePdfRenderer instance, passing the HTML string as input. This function processes the content and transforms it into a PDF document.
- Saving the PDF: Finally, the generated PDF is saved to a file named "html2Pdf.pdf" using the
SaveAs() method, storing it on the disk for future access.
Output PDF
IronPDF requires a valid license key for full functionality. You can obtain a trial license from the official website. Before using the IronPDF library, set the license key as follows:
IronPdf.License.LicenseKey = "your key";
IronPdf.License.LicenseKey = "your key";
IronPdf.License.LicenseKey = "your key"
IronPdf.License.LicenseKey = "your key"
This ensures that the library operates without limitations.
Conclusion
PuppeteerSharp is an excellent choice for developers who need precise rendering of HTML to PDF, especially when dealing with complex web pages. However, for applications that require advanced PDF-specific features, performance optimization, and ease of integration, professional tools like IronPDF are often the better option.
PDFSharp is a great choice for lightweight, programmatic PDF creation and manipulation, especially for projects with simple requirements. However, if your application requires converting HTML to PDF or advanced PDF features, IronPDF provides a more efficient and feature-rich solution.
While Pdfium.NET SDK is a robust tool for PDF manipulation, IronPDF provides native support for direct HTML-to-PDF conversion, including rendering modern HTML, CSS, and JavaScript. IronPDF simplifies the workflow with built-in methods like HtmlToPdf.RenderHtmlAsPdf(), making it faster and more efficient for developers.
QuestPDF and PdfPig are worth knowing about, but neither actually converts HTML to PDF: QuestPDF composes documents from a fluent C# API, and PdfPig is built for reading and extracting content from PDFs that already exist. IronPDF covers both directions from a single library, rendering existing HTML and JavaScript into a PDF and giving you full read and edit access to the result.
wkhtmltopdf remains a common answer to "free HTML to PDF," but its GitHub organization has been archived since 2024, its last release predates modern CSS support, and it carries an unpatched critical vulnerability. IronPDF is a managed, actively maintained .NET library that renders with a modern Chromium engine, without the deployment and security overhead of shelling out to an external binary.
iText7 with pdfHTML comes closest to IronPDF's feature set, but its AGPL/commercial dual license means most closed-source applications need a paid license, and its limited support for responsive CSS pushes developers toward table-based layouts for anything beyond simple documents. IronPDF's Chromium-based rendering handles modern CSS frameworks like Bootstrap and Tailwind with pixel-perfect accuracy, without redesigning the source HTML.
Whether it's for generating invoices, reports, or archiving web content, IronPDF empowers developers with the tools they need to achieve professional-grade results quickly and efficiently.
IronPDF is a practical choice for developers who value reliability, scalability, and ease of use in their HTML to PDF workflows.