# Java PDF to Image File
Convert PDF documents to image formats like JPEG, PNG, or TIFF in Java using IronPDF's `toBufferedImages` method. Load a PDF file, call `toBufferedImages` to get a list of `BufferedImage` objects, then write each image to disk using `ImageIO`. The entire conversion takes fewer than ten lines of working Java code.
*as-heading:2(Quickstart: Convert PDF to Images in Java)*
1. Add IronPDF dependency to your Maven project:
```xml
:title=pom.xml
<dependency>
    <groupId>com.ironsoftware</groupId>
    <artifactId>ironpdf</artifactId>
    <version>2024.9.1</version>
</dependency>
```
2. Load your PDF document:
```java
PdfDocument pdf = PdfDocument.fromFile(Paths.get("document.pdf"));
```
3. Convert to images and save:
```java
List<BufferedImage> images = pdf.toBufferedImages();
for (int i = 0; i < images.size(); i++) {
ImageIO.write(images.get(i), "PNG", new File("page_" + i + ".png"));
}
```
<div class="hsg-featured-snippet">
<h3>Minimal Workflow (5 steps)</h3>
<ol>
<li><a class="js-modal-open" data-modal-id="download-modal" href="#download-modal">Install the IronPDF Java library</a></li>
<li>Load a PDF file using <code>PdfDocument.fromFile()</code></li>
<li>Call <code>toBufferedImages()</code> to get a <code>List<BufferedImage></code></li>
<li>Set output dimensions with <code>ToImageOptions</code> if needed</li>
<li>Write each image to disk using <code>ImageIO.write()</code></li>
</ol>
</div>
## What Is PDF to Image Conversion and Why Is It Needed?
PDF to image conversion turns each page of a PDF document into a standalone image file (JPEG, PNG, or TIFF) that can be displayed, embedded, or processed without a PDF viewer. Java's standard libraries provide no built-in mechanism for this, which makes it a persistent pain point for developers who need document previews, thumbnail generators, or archival pipelines.
Common uses include generating thumbnail previews for document management systems, producing page-level screenshots for web applications, and extracting visual content for reports or presentations. IronPDF handles all rendering complexity internally, so the application code stays short and the output is pixel-accurate regardless of fonts, vector graphics, or form fields in the source PDF. For the inverse operation of placing images into a PDF, see the [image-to-PDF how-to guide](https://ironpdf.com/how-to/image-to-pdf/).
## What Is IronPDF for Java and How Does It Help?
[IronPDF for Java](/java/) is a library for creating, reading, and editing PDF files in Maven-based projects. Developers use it to generate PDFs from HTML, modify existing documents, and extract content without Adobe Acrobat or any PDF viewer installed on the server.
The library supports custom headers and footers, digital signatures, form creation, password protection, and multithreaded rendering. Its PDF-to-image feature exposes a clean API through two overloads of `toBufferedImages`: one that converts every page with default settings, and one that accepts a `ToImageOptions` object and a `PageSelection` to control resolution and page range. For a complete feature overview, visit the [IronPDF for Java documentation](/java/docs/). For the full API reference, see the [Java API reference](https://ironpdf.com/java/object-reference/api/).
Beyond basic conversion, IronPDF supports [HTML to PDF rendering](https://ironpdf.com/java/tutorials/html-to-pdf/), [custom watermarks](https://ironpdf.com/java/how-to/custom-watermark/), [backgrounds and foregrounds](https://ironpdf.com/java/how-to/background-foreground/), and [form creation](https://ironpdf.com/java/how-to/create-forms/). It also ships Maven artifacts on the [Sonatype Maven Central repository](https://central.sonatype.com/artifact/com.ironsoftware/ironpdf), so dependency management follows standard Maven or Gradle workflows.
## What Prerequisites Do I Need Before Starting?
Before starting, confirm the following are in place:
1. Java installed with the path set in Environment Variables. See the official [Java installation guide](https://www.java.com/en/download/help/download_options.html#windows).
2. A Java IDE installed; Eclipse or IntelliJ both work well. Download [Eclipse](https://www.eclipse.org/downloads/) or [IntelliJ IDEA](https://www.jetbrains.com/idea/download/#section=windows).
3. Maven integrated with the IDE. See this [Maven setup tutorial](https://www.jetbrains.com/idea/guide/tutorials/marco-codes-maven/installing-maven/) for IntelliJ.
4. [License keys configured](https://ironpdf.com/java/get-started/license-keys/) before deploying to a production environment.
## How Do I Install IronPDF for Java?
Once all prerequisites are in place, installation is a single Maven dependency declaration. For detailed setup steps, consult the [getting started documentation](https://ironpdf.com/java/docs/).
Open JetBrains IntelliJ IDEA and create a new Maven project.
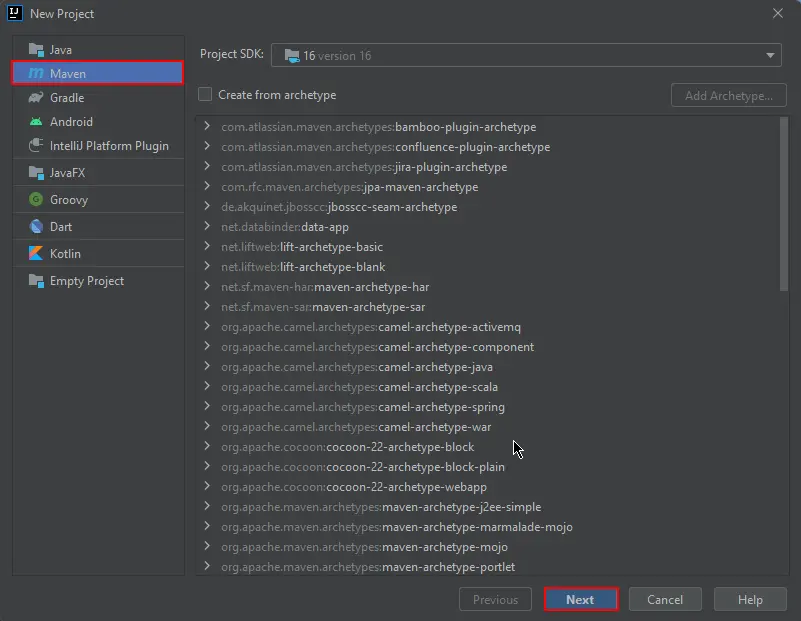
Create a new Maven Project
A new window appears. Enter the project name and click Finish.
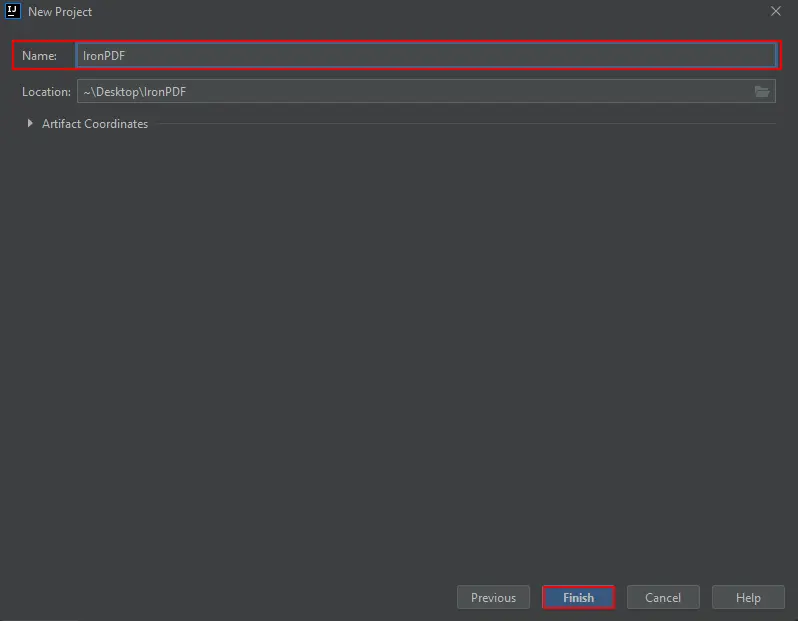
New Project Name
After clicking Finish, the new project opens with `pom.xml` displayed by default. Add the following dependencies to that file. The optional SLF4J entry suppresses logging noise during development; remove it if your project already includes a logging framework.
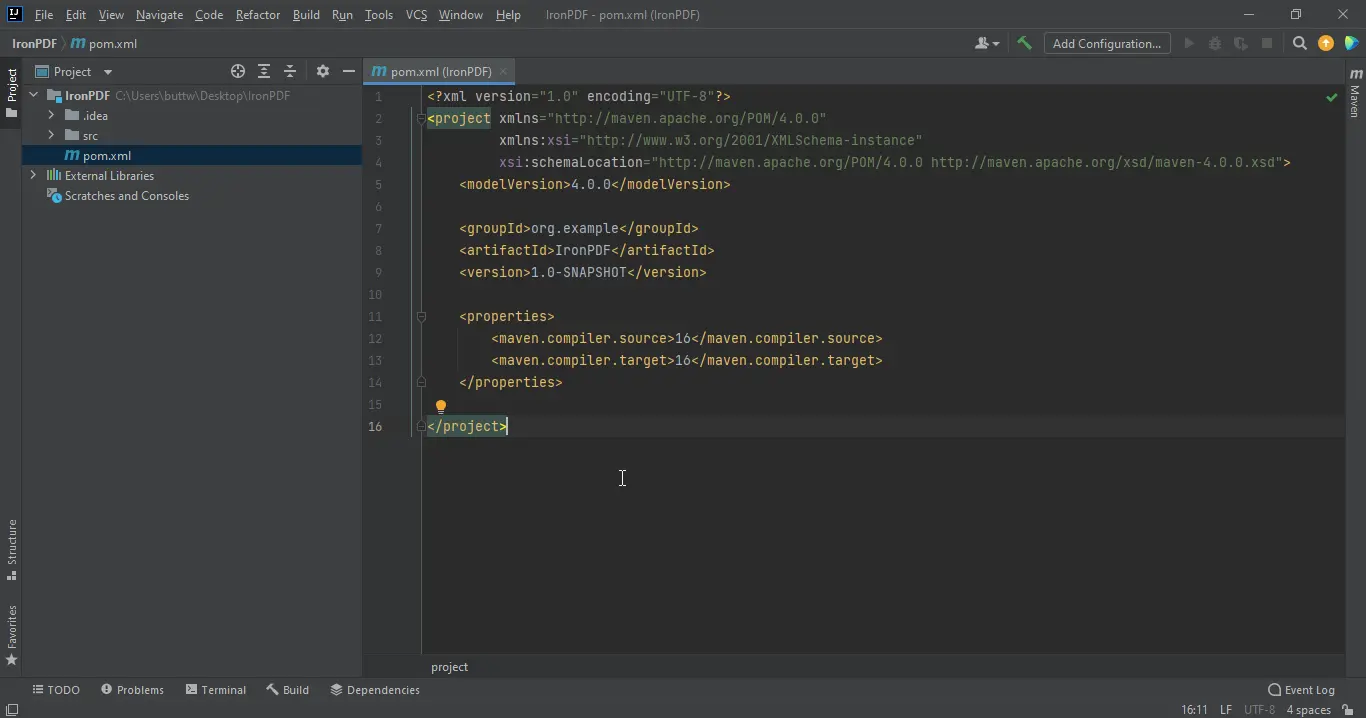
New Project: default pom.xml
```xml
<dependencies>
<dependency>
    <groupId>com.ironsoftware</groupId>
    <artifactId>ironpdf</artifactId>
    <version>2024.9.1</version>
</dependency>
<!-- Optional: SLF4J logging - remove if your project already uses a logging framework -->
<dependency>
<groupId>org.slf4j</groupId>
<artifactId>slf4j-simple</artifactId>
<version>1.7.36</version>
</dependency>
</dependencies>
```
Once the dependencies are added to `pom.xml`, a Maven sync icon appears in the top-right corner of the editor.
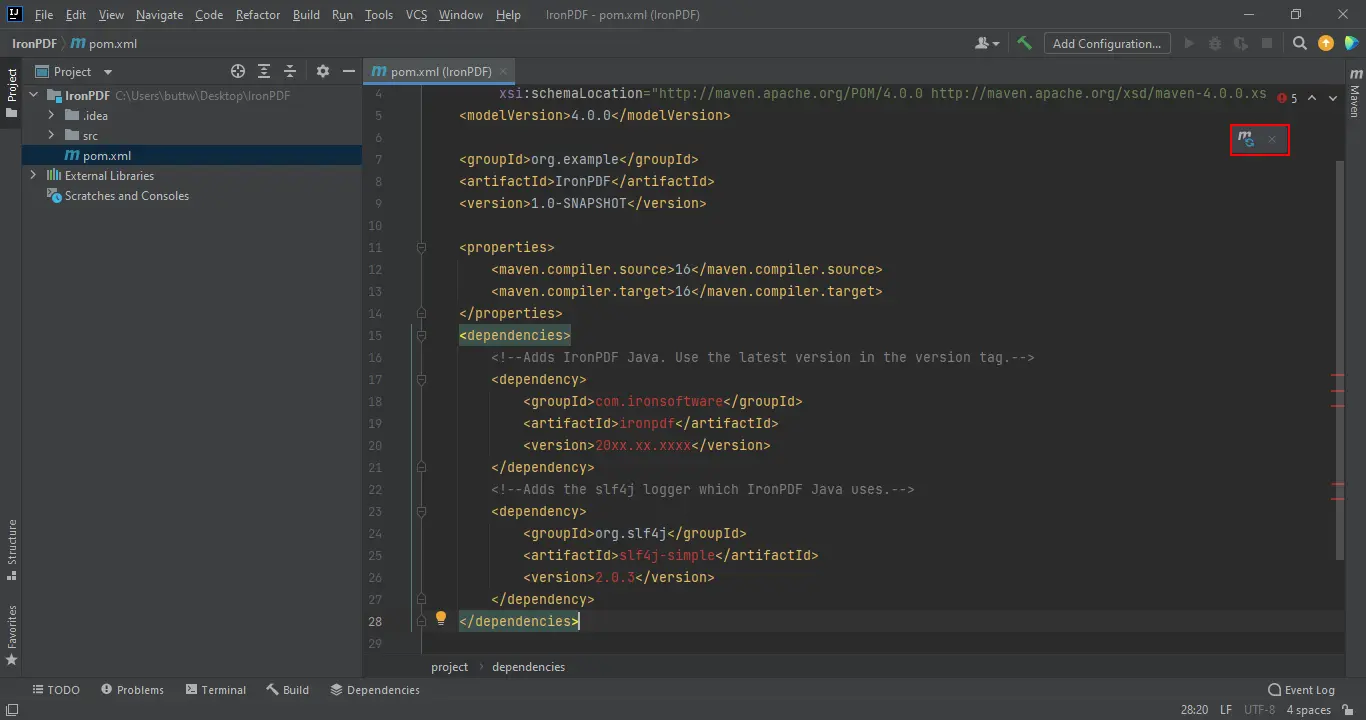
Maven Dependencies Added
Click the sync icon to download the IronPDF JAR. Download time depends on connection speed, typically under two minutes. After installation, review the [Java API reference](https://ironpdf.com/java/object-reference/api/) to see all available methods and configuration options. For cloud deployment targets, IronPDF has tested guides for [AWS](https://ironpdf.com/java/get-started/aws/), [Azure](https://ironpdf.com/java/get-started/azure/), and [Google Cloud](https://ironpdf.com/java/get-started/google-cloud/).
## How Do I Convert PDF Files to Images Using IronPDF?
Calling `toBufferedImages` on a `PdfDocument` object produces a `List<BufferedImage>` where each element corresponds to one PDF page in ascending page-number order. The result can then be written to disk, passed to an image processing pipeline, or returned directly to a web response.
IronPDF also converts URLs and HTML strings to PDF on the fly, so it is possible to capture any web page or rendered HTML document as images in a single pipeline without a separate rendering step.
### How Do I Convert an Existing PDF Document to Images?
`toBufferedImages` accepts an optional `ToImageOptions` argument for controlling output dimensions, and a `PageSelection` argument for targeting specific pages. When no arguments are passed, all pages are converted at their natural resolution.
The example below converts all pages of a PDF to PNG files, using `ToImageOptions` to cap each output image at 800x500 pixels:
```java
import com.ironsoftware.ironpdf.PdfDocument;
import com.ironsoftware.ironpdf.edit.PageSelection;
import com.ironsoftware.ironpdf.image.ToImageOptions;
import javax.imageio.ImageIO;
import java.awt.image.BufferedImage;
import java.io.File;
import java.io.IOException;
import java.nio.file.Paths;
import java.util.List;
public class Main {
public static void main(String[] args) throws IOException {
// Load the PDF document from disk
PdfDocument pdf = PdfDocument.fromFile(Paths.get("business_plan.pdf"));
// Configure output image dimensions
ToImageOptions options = new ToImageOptions();
options.setImageMaxHeight(800);
options.setImageMaxWidth(500);
// Convert all pages to BufferedImage objects with the configured dimensions
List<BufferedImage> pages = pdf.toBufferedImages(options, PageSelection.allPages());
// Write each page image to the assets/images folder (create the folder first)
int pageIndex = 1;
for (BufferedImage page : pages) {
String fileName = "assets/images/" + pageIndex++ + ".png";
ImageIO.write(page, "PNG", new File(fileName));
}
}
}
```
The output images are saved to `assets/images/` with numeric filenames starting at `1`. Create that folder before running the program, as `ImageIO.write` does not create missing directories. The `setImageMaxHeight` and `setImageMaxWidth` calls set upper bounds on each dimension; IronPDF preserves the original aspect ratio and does not stretch the image.
[[t:(To save in JPEG format instead of PNG, change the format string in `ImageIO.write` from `"PNG"` to `"JPEG"` and update the file extension accordingly.)]]
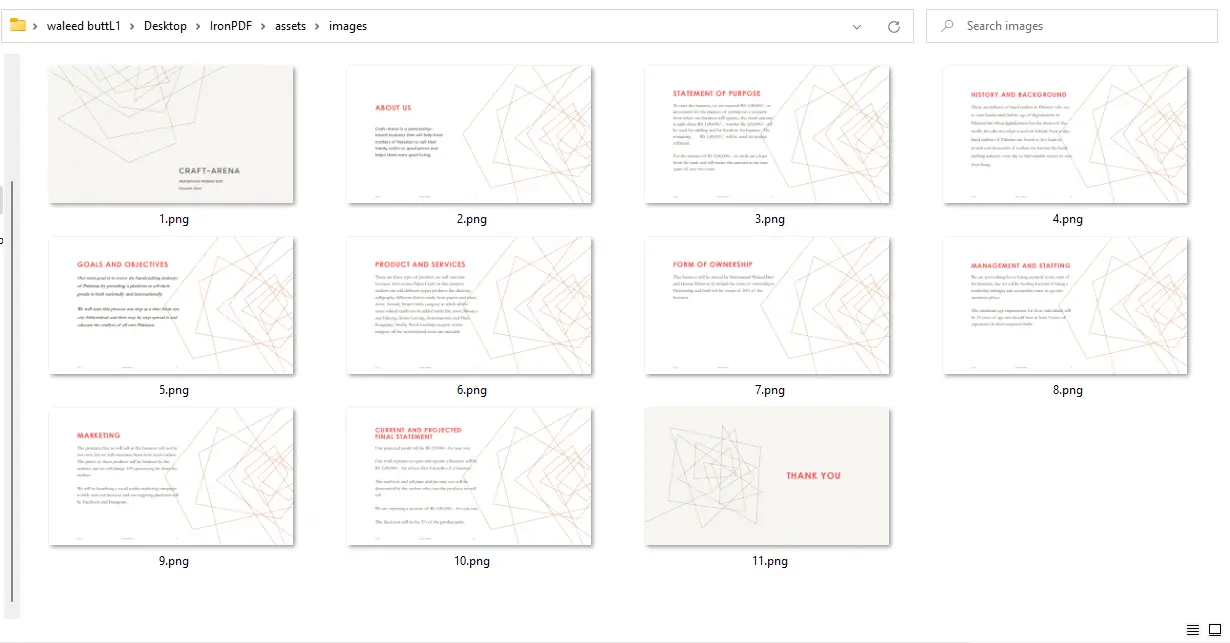
PDF to Images Output - 11 PNG files, one per page
For more conversion examples, visit the [PDF rasterization examples page](https://ironpdf.com/java/examples/rasterize-a-pdf-to-images/).
### How Do I Convert a URL to Images Using IronPDF?
`PdfDocument.renderUrlAsPdf` fetches the URL, renders it with the built-in Chromium engine, and returns a `PdfDocument` that can be immediately passed to `toBufferedImages`. This makes it straightforward to capture any publicly accessible web page as a series of images.
The example below renders an Amazon product page to a PDF and then saves each resulting page as a PNG file:
```java
import com.ironsoftware.ironpdf.PdfDocument;
import com.ironsoftware.ironpdf.edit.PageSelection;
import com.ironsoftware.ironpdf.image.ToImageOptions;
import javax.imageio.ImageIO;
import java.awt.image.BufferedImage;
import java.io.File;
import java.io.IOException;
import java.util.List;
public class Main {
public static void main(String[] args) throws IOException {
// Render a URL to a PDF document using the Chromium rendering engine
PdfDocument pdf = PdfDocument.renderUrlAsPdf("https://www.amazon.com");
// Configure output image dimensions
ToImageOptions options = new ToImageOptions();
options.setImageMaxHeight(800);
options.setImageMaxWidth(500);
// Convert all pages and write to disk
List<BufferedImage> pages = pdf.toBufferedImages(options, PageSelection.allPages());
int pageIndex = 1;
for (BufferedImage page : pages) {
String fileName = "assets/images/" + pageIndex++ + ".png";
ImageIO.write(page, "PNG", new File(fileName));
}
}
}
```
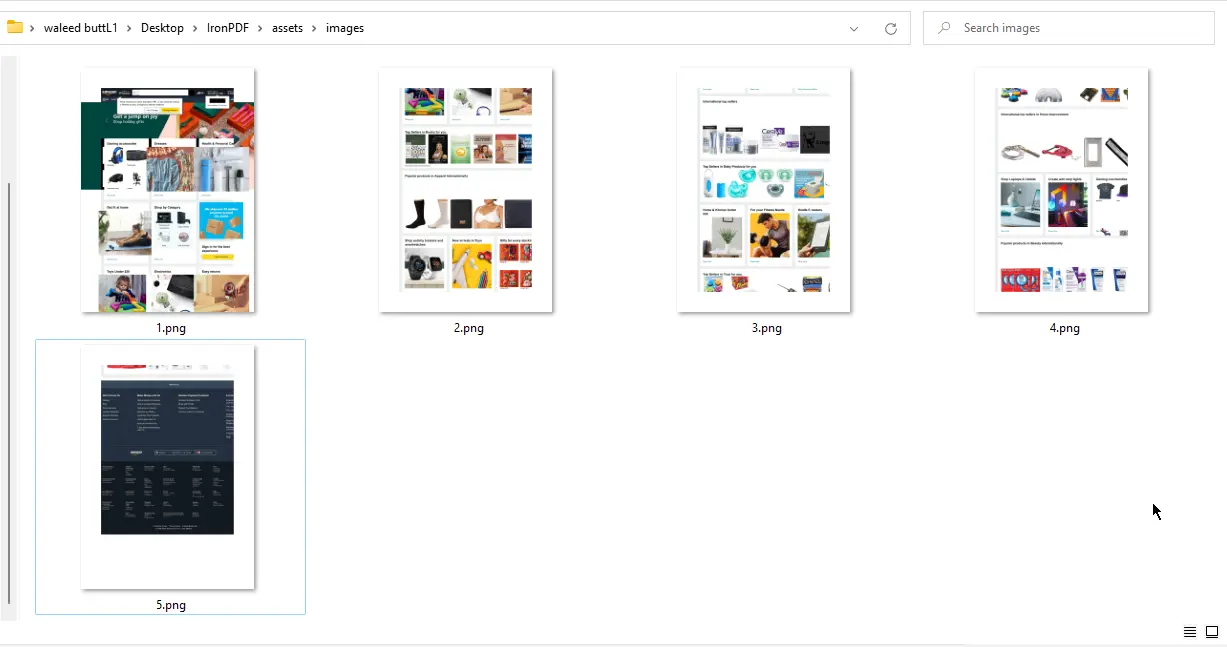
URL to Images Output - 5 PNG files
For pages that require authentication or session cookies before rendering, see the [website logins guide](https://ironpdf.com/java/examples/ironpdf-website-and-system-logins/).
[[i:(The Chromium rendering engine that powers `renderUrlAsPdf` applies the same CSS and JavaScript support as a modern desktop browser. Pages that rely on client-side JavaScript to load content will render correctly, including single-page applications.)]]
### How Do I Convert Specific Pages to Images?
`PageSelection` provides several factory methods for targeting a subset of pages rather than the entire document. This is useful when only a cover page, a summary section, or a known page range needs to be extracted.
```java
import com.ironsoftware.ironpdf.PdfDocument;
import com.ironsoftware.ironpdf.edit.PageSelection;
import com.ironsoftware.ironpdf.image.ToImageOptions;
import javax.imageio.ImageIO;
import java.awt.image.BufferedImage;
import java.io.File;
import java.io.IOException;
import java.nio.file.Paths;
import java.util.List;
public class PageSelectionExample {
public static void main(String[] args) throws IOException {
PdfDocument pdf = PdfDocument.fromFile(Paths.get("report.pdf"));
ToImageOptions options = new ToImageOptions();
options.setImageMaxHeight(800);
options.setImageMaxWidth(500);
// Convert only the first page (page index is zero-based)
List<BufferedImage> coverPage = pdf.toBufferedImages(options, PageSelection.singlePage(0));
ImageIO.write(coverPage.get(0), "PNG", new File("cover.png"));
// Convert pages 2 through 5 (zero-based indices 1 through 4)
List<BufferedImage> excerpt = pdf.toBufferedImages(options, PageSelection.pageRange(1, 4));
for (int i = 0; i < excerpt.size(); i++) {
ImageIO.write(excerpt.get(i), "PNG", new File("excerpt_" + (i + 1) + ".png"));
}
}
}
```
`PageSelection.singlePage(0)` targets only the first page, which is useful for generating a cover thumbnail. `PageSelection.pageRange(1, 4)` extracts pages two through five using zero-based indices. Both return a `List<BufferedImage>`, so the loop pattern is identical regardless of how many pages are selected.
[[n:(Page indices in `PageSelection` are zero-based: the first page is `0`, the second is `1`, and so on. Passing an out-of-range index throws an `IndexOutOfBoundsException` at runtime.)]]
## What Are the Next Steps for Java PDF to Image Conversion?
This guide covered three common patterns: converting all pages of an existing PDF, capturing a URL as a set of page images, and extracting a targeted page range. IronPDF handles resolution control and format selection through `ToImageOptions` and `ImageIO`, keeping the calling code short and predictable.
To continue building with IronPDF for Java, explore these related resources:
- [Java rasterization examples](https://ironpdf.com/java/examples/rasterize-a-pdf-to-images/) - additional PDF to image code samples
- [Extract images and text from a PDF](https://ironpdf.com/java/examples/extract-image-from-pdf/) - pull embedded images out of existing PDF files
- [Compress PDFs in Java](https://ironpdf.com/java/how-to/compress-pdf-java-tutorial/) - reduce file size before storage or transmission
- [Custom watermarks](https://ironpdf.com/java/how-to/custom-watermark/) - stamp output images or PDFs with a watermark before saving
- [IronPDF for Java documentation](/java/docs/) - complete API reference and setup guides
IronPDF for Java is free for development. A license is required for commercial deployment. [Start your free trial](#trial-license) or [view licensing options](#licensing) to see which plan fits your project.
Ready to see what else IronPDF can do? Check out the full [IronPDF for Java tutorial page](/java/tutorials/html-to-pdf/).
Convert PDF documents to image formats like JPEG, PNG, or TIFF in Java using IronPDF's toBufferedImages method. Load a PDF file, call toBufferedImages to get a list of BufferedImage objects, then write each image to disk using ImageIO. The entire conversion takes fewer than ten lines of working Java code.
Start using IronPDF in your project today with a free trial
Load your PDF document:
PdfDocument pdf = PdfDocument.fromFile(Paths.get("document.pdf"));
PdfDocument pdf = PdfDocument.fromFile(Paths.get("document.pdf"));
Java
Convert to images and save:
List<BufferedImage> images = pdf.toBufferedImages();for (int i = 0; i < images.size(); i++) {ImageIO.write(images.get(i), "PNG", newFile("page_" + i + ".png"));}
List<BufferedImage> images = pdf.toBufferedImages();
for (int i = 0; i < images.size(); i++) {
    ImageIO.write(images.get(i), "PNG", new File("page_" + i + ".png"));
}
Call toBufferedImages() to get a List<BufferedImage>
Set output dimensions with ToImageOptions if needed
Write each image to disk using ImageIO.write()
What Is PDF to Image Conversion and Why Is It Needed?
PDF to image conversion turns each page of a PDF document into a standalone image file (JPEG, PNG, or TIFF) that can be displayed, embedded, or processed without a PDF viewer. Java's standard libraries provide no built-in mechanism for this, which makes it a persistent pain point for developers who need document previews, thumbnail generators, or archival pipelines.
Common uses include generating thumbnail previews for document management systems, producing page-level screenshots for web applications, and extracting visual content for reports or presentations. IronPDF handles all rendering complexity internally, so the application code stays short and the output is pixel-accurate regardless of fonts, vector graphics, or form fields in the source PDF. For the inverse operation of placing images into a PDF, see the image-to-PDF how-to guide.
What Is IronPDF for Java and How Does It Help?
IronPDF for Java is a library for creating, reading, and editing PDF files in Maven-based projects. Developers use it to generate PDFs from HTML, modify existing documents, and extract content without Adobe Acrobat or any PDF viewer installed on the server.
The library supports custom headers and footers, digital signatures, form creation, password protection, and multithreaded rendering. Its PDF-to-image feature exposes a clean API through two overloads of toBufferedImages: one that converts every page with default settings, and one that accepts a ToImageOptions object and a PageSelection to control resolution and page range. For a complete feature overview, visit the IronPDF for Java documentation. For the full API reference, see the Java API reference.
Once all prerequisites are in place, installation is a single Maven dependency declaration. For detailed setup steps, consult the getting started documentation.
Open JetBrains IntelliJ IDEA and create a new Maven project.
Create a new Maven Project
A new window appears. Enter the project name and click Finish.
New Project Name
After clicking Finish, the new project opens with pom.xml displayed by default. Add the following dependencies to that file. The optional SLF4J entry suppresses logging noise during development; remove it if your project already includes a logging framework.
New Project: default pom.xml
<dependencies> <dependency> <groupId>com.ironsoftware</groupId> <artifactId>ironpdf</artifactId> <version>2024.9.1</version> </dependency> <!-- Optional: SLF4J logging - remove if your project already uses a logging framework --> <dependency> <groupId>org.slf4j</groupId> <artifactId>slf4j-simple</artifactId> <version>1.7.36</version> </dependency></dependencies>
<dependencies>
    <dependency>
        <groupId>com.ironsoftware</groupId>
        <artifactId>ironpdf</artifactId>
        <version>2024.9.1</version>
    </dependency>
    <!-- Optional: SLF4J logging - remove if your project already uses a logging framework -->
    <dependency>
        <groupId>org.slf4j</groupId>
        <artifactId>slf4j-simple</artifactId>
        <version>1.7.36</version>
    </dependency>
</dependencies>
XML
Once the dependencies are added to pom.xml, a Maven sync icon appears in the top-right corner of the editor.
Maven Dependencies Added
Click the sync icon to download the IronPDF JAR. Download time depends on connection speed, typically under two minutes. After installation, review the Java API reference to see all available methods and configuration options. For cloud deployment targets, IronPDF has tested guides for AWS, Azure, and Google Cloud.
How Do I Convert PDF Files to Images Using IronPDF?
Calling toBufferedImages on a PdfDocument object produces a List<BufferedImage> where each element corresponds to one PDF page in ascending page-number order. The result can then be written to disk, passed to an image processing pipeline, or returned directly to a web response.
IronPDF also converts URLs and HTML strings to PDF on the fly, so it is possible to capture any web page or rendered HTML document as images in a single pipeline without a separate rendering step.
How Do I Convert an Existing PDF Document to Images?
toBufferedImages accepts an optional ToImageOptions argument for controlling output dimensions, and a PageSelection argument for targeting specific pages. When no arguments are passed, all pages are converted at their natural resolution.
The example below converts all pages of a PDF to PNG files, using ToImageOptions to cap each output image at 800x500 pixels:
import com.ironsoftware.ironpdf.PdfDocument;import com.ironsoftware.ironpdf.edit.PageSelection;import com.ironsoftware.ironpdf.image.ToImageOptions;import javax.imageio.ImageIO;import java.awt.image.BufferedImage;import java.io.File;import java.io.IOException;import java.nio.file.Paths;import java.util.List;public class Main { public static void main(String[] args) throws IOException { // Load the PDF document from disk PdfDocument pdf = PdfDocument.fromFile(Paths.get("business_plan.pdf")); // Configure output image dimensions ToImageOptions options = newToImageOptions(); options.setImageMaxHeight(800); options.setImageMaxWidth(500); // Convert all pages to BufferedImage objects with the configured dimensions List<BufferedImage> pages = pdf.toBufferedImages(options, PageSelection.allPages()); // Write each page image to the assets/images folder (create the folder first) int pageIndex = 1; for (BufferedImage page : pages) { String fileName = "assets/images/" + pageIndex++ + ".png";ImageIO.write(page, "PNG", newFile(fileName)); } }}
import com.ironsoftware.ironpdf.PdfDocument;
import com.ironsoftware.ironpdf.edit.PageSelection;
import com.ironsoftware.ironpdf.image.ToImageOptions;
import javax.imageio.ImageIO;
import java.awt.image.BufferedImage;
import java.io.File;
import java.io.IOException;
import java.nio.file.Paths;
import java.util.List;

public class Main {
    public static void main(String[] args) throws IOException {
        // Load the PDF document from disk
        PdfDocument pdf = PdfDocument.fromFile(Paths.get("business_plan.pdf"));

        // Configure output image dimensions
        ToImageOptions options = new ToImageOptions();
        options.setImageMaxHeight(800);
        options.setImageMaxWidth(500);

        // Convert all pages to BufferedImage objects with the configured dimensions
        List<BufferedImage> pages = pdf.toBufferedImages(options, PageSelection.allPages());

        // Write each page image to the assets/images folder (create the folder first)
        int pageIndex = 1;
        for (BufferedImage page : pages) {
            String fileName = "assets/images/" + pageIndex++ + ".png";
            ImageIO.write(page, "PNG", new File(fileName));
        }
    }
}
Java
The output images are saved to assets/images/ with numeric filenames starting at 1. Create that folder before running the program, as ImageIO.write does not create missing directories. The setImageMaxHeight and setImageMaxWidth calls set upper bounds on each dimension; IronPDF preserves the original aspect ratio and does not stretch the image.
Tips: To save in JPEG format instead of PNG, change the format string in ImageIO.write from "PNG" to "JPEG" and update the file extension accordingly.
PdfDocument.renderUrlAsPdf fetches the URL, renders it with the built-in Chromium engine, and returns a PdfDocument that can be immediately passed to toBufferedImages. This makes it straightforward to capture any publicly accessible web page as a series of images.
The example below renders an Amazon product page to a PDF and then saves each resulting page as a PNG file:
import com.ironsoftware.ironpdf.PdfDocument;import com.ironsoftware.ironpdf.edit.PageSelection;import com.ironsoftware.ironpdf.image.ToImageOptions;import javax.imageio.ImageIO;import java.awt.image.BufferedImage;import java.io.File;import java.io.IOException;import java.util.List;public class Main { public static void main(String[] args) throws IOException { // Render a URL to a PDF document using the Chromium rendering engine PdfDocument pdf = PdfDocument.renderUrlAsPdf("https://www.amazon.com"); // Configure output image dimensions ToImageOptions options = newToImageOptions(); options.setImageMaxHeight(800); options.setImageMaxWidth(500); // Convert all pages and write to disk List<BufferedImage> pages = pdf.toBufferedImages(options, PageSelection.allPages()); int pageIndex = 1; for (BufferedImage page : pages) { String fileName = "assets/images/" + pageIndex++ + ".png";ImageIO.write(page, "PNG", newFile(fileName)); } }}
import com.ironsoftware.ironpdf.PdfDocument;
import com.ironsoftware.ironpdf.edit.PageSelection;
import com.ironsoftware.ironpdf.image.ToImageOptions;
import javax.imageio.ImageIO;
import java.awt.image.BufferedImage;
import java.io.File;
import java.io.IOException;
import java.util.List;

public class Main {
    public static void main(String[] args) throws IOException {
        // Render a URL to a PDF document using the Chromium rendering engine
        PdfDocument pdf = PdfDocument.renderUrlAsPdf("https://www.amazon.com");

        // Configure output image dimensions
        ToImageOptions options = new ToImageOptions();
        options.setImageMaxHeight(800);
        options.setImageMaxWidth(500);

        // Convert all pages and write to disk
        List<BufferedImage> pages = pdf.toBufferedImages(options, PageSelection.allPages());
        int pageIndex = 1;
        for (BufferedImage page : pages) {
            String fileName = "assets/images/" + pageIndex++ + ".png";
            ImageIO.write(page, "PNG", new File(fileName));
        }
    }
}
Java
URL to Images Output - 5 PNG files
For pages that require authentication or session cookies before rendering, see the website logins guide.
Please note: The Chromium rendering engine that powers renderUrlAsPdf applies the same CSS and JavaScript support as a modern desktop browser. Pages that rely on client-side JavaScript to load content will render correctly, including single-page applications.
How Do I Convert Specific Pages to Images?
PageSelection provides several factory methods for targeting a subset of pages rather than the entire document. This is useful when only a cover page, a summary section, or a known page range needs to be extracted.
import com.ironsoftware.ironpdf.PdfDocument;import com.ironsoftware.ironpdf.edit.PageSelection;import com.ironsoftware.ironpdf.image.ToImageOptions;import javax.imageio.ImageIO;import java.awt.image.BufferedImage;import java.io.File;import java.io.IOException;import java.nio.file.Paths;import java.util.List;public class PageSelectionExample { public static void main(String[] args) throws IOException { PdfDocument pdf = PdfDocument.fromFile(Paths.get("report.pdf")); ToImageOptions options = newToImageOptions(); options.setImageMaxHeight(800); options.setImageMaxWidth(500); // Convert only the first page (page index is zero-based) List<BufferedImage> coverPage = pdf.toBufferedImages(options, PageSelection.singlePage(0));ImageIO.write(coverPage.get(0), "PNG", newFile("cover.png")); // Convert pages 2 through 5 (zero-based indices 1 through 4) List<BufferedImage> excerpt = pdf.toBufferedImages(options, PageSelection.pageRange(1, 4)); for (int i = 0; i < excerpt.size(); i++) {ImageIO.write(excerpt.get(i), "PNG", newFile("excerpt_" + (i + 1) + ".png")); } }}
import com.ironsoftware.ironpdf.PdfDocument;
import com.ironsoftware.ironpdf.edit.PageSelection;
import com.ironsoftware.ironpdf.image.ToImageOptions;
import javax.imageio.ImageIO;
import java.awt.image.BufferedImage;
import java.io.File;
import java.io.IOException;
import java.nio.file.Paths;
import java.util.List;

public class PageSelectionExample {
    public static void main(String[] args) throws IOException {
        PdfDocument pdf = PdfDocument.fromFile(Paths.get("report.pdf"));
        ToImageOptions options = new ToImageOptions();
        options.setImageMaxHeight(800);
        options.setImageMaxWidth(500);

        // Convert only the first page (page index is zero-based)
        List<BufferedImage> coverPage = pdf.toBufferedImages(options, PageSelection.singlePage(0));
        ImageIO.write(coverPage.get(0), "PNG", new File("cover.png"));

        // Convert pages 2 through 5 (zero-based indices 1 through 4)
        List<BufferedImage> excerpt = pdf.toBufferedImages(options, PageSelection.pageRange(1, 4));
        for (int i = 0; i < excerpt.size(); i++) {
            ImageIO.write(excerpt.get(i), "PNG", new File("excerpt_" + (i + 1) + ".png"));
        }
    }
}
Java
PageSelection.singlePage(0) targets only the first page, which is useful for generating a cover thumbnail. PageSelection.pageRange(1, 4) extracts pages two through five using zero-based indices. Both return a List<BufferedImage>, so the loop pattern is identical regardless of how many pages are selected.
Important: Page indices in PageSelection are zero-based: the first page is 0, the second is 1, and so on. Passing an out-of-range index throws an IndexOutOfBoundsException at runtime.
What Are the Next Steps for Java PDF to Image Conversion?
This guide covered three common patterns: converting all pages of an existing PDF, capturing a URL as a set of page images, and extracting a targeted page range. IronPDF handles resolution control and format selection through ToImageOptions and ImageIO, keeping the calling code short and predictable.
To continue building with IronPDF for Java, explore these related resources:
IronPDF for Java is free for development. A license is required for commercial deployment. Start your free trial or view licensing options to see which plan fits your project.
How do I convert a PDF to image formats using IronPDF in Java?
To convert a PDF to image formats like JPEG, PNG, or TIFF using IronPDF in Java, load the PDF document with `PdfDocument.fromFile()`, then call `toBufferedImages()`, and write each image to disk with `ImageIO.write()`.
What is the purpose of the `ToImageOptions` in IronPDF?
`ToImageOptions` in IronPDF allows you to control the output image dimensions and resolution during the PDF to image conversion process.
Can IronPDF convert specific pages of a PDF into images?
Yes, IronPDF allows you to convert specific pages of a PDF using the `PageSelection` class, which lets you target a subset of pages for conversion.
How do I add IronPDF to my Maven project?
You can add IronPDF to your Maven project by including the dependency in your `pom.xml` file with the groupId `com.ironsoftware` and artifactId `ironpdf`.
Why would developers need to convert PDFs to images?
Developers convert PDFs to images for use cases like generating document previews, thumbnails, or for situations where PDF viewing capabilities are not available or needed.
Can IronPDF handle rendering complexities like vector graphics and fonts?
Yes, IronPDF manages rendering complexities internally, ensuring pixel-accurate output regardless of fonts, vector graphics, or form fields present in the source PDF.
Is it possible to convert a web page to images using IronPDF?
Yes, IronPDF can convert web pages to images by using `PdfDocument.renderUrlAsPdf()` to fetch the webpage and then using `toBufferedImages()` to convert it into images.
What are the output image formats that IronPDF supports?
IronPDF supports converting PDFs to various image formats, including JPEG, PNG, and TIFF.
How does IronPDF handle conversion of multi-page PDFs?
IronPDF converts each page of a multi-page PDF into a standalone image, maintaining the order and allowing for individual processing or storage.
What Java prerequisites are needed for using IronPDF?
Before using IronPDF, ensure that Java is installed, along with a Java IDE like Eclipse or IntelliJ, and that Maven is set up and integrated with the IDE.
Curtis Chau holds a Bachelor’s degree in Computer Science (Carleton University) and specializes in front-end development with expertise in Node.js, TypeScript, JavaScript, and React. Passionate about crafting intuitive and aesthetically pleasing user interfaces, Curtis enjoys working with modern frameworks and creating well-structured, visually appealing manuals.











