using IronPdf;

// Instantiate Renderer
var renderer = new ChromePdfRenderer();

// Create a PDF from a HTML string using C#
var pdf = renderer.RenderHtmlAsPdf("<h1>Hello World</h1>");

// Export to a file or Stream
pdf.SaveAs("output.pdf");

// Advanced Example with HTML Assets
// Load external html assets: Images, CSS and JavaScript.
// An optional BaseUrlOrPath 'C:\site\assets\' is set as the file location to load assets from
var myAdvancedPdf = renderer.RenderHtmlAsPdf("<img src='icons/iron.png'>", @"C:\site\assets\");
myAdvancedPdf.SaveAs("html-with-assets.pdf");
using IronPdf;// Instantiate Renderervar renderer = new ChromePdfRenderer();// Create a PDF from a HTML string using C#var pdf = renderer.RenderHtmlAsPdf("<h1>Hello World</h1>");// Export to a file or Streampdf.SaveAs("output.pdf");// Advanced Example with HTML Assets// Load external html assets: Images, CSS and JavaScript.// An optional BaseUrlOrPath 'C:\site\assets\' is set as the file location to load assets fromvar myAdvancedPdf = renderer.RenderHtmlAsPdf("<img src='icons/iron.png'>", @"C:\site\assets\");myAdvancedPdf.SaveAs("html-with-assets.pdf");
PDF files are a widely used format for document exchange due to their ability to preserve formatting across different platforms. In various applications, programmatically reading the contents of PDF files becomes invaluable.
This article shows how to view text from PDF files in C++ using the Xpdf command-line tool. Xpdf provides a suite of command-line utilities and C++ libraries for working with PDF files, including text extraction. This page extracts the text with pdftotext and prints it to the console; it does not draw the pages on screen. By calling Xpdf from your C++ program, you can read text content from PDF files and process it programmatically. For a second walkthrough of the same tool, see the C++ PDF reader tutorial.
Xpdf - C++ Library and Command-line Tools
Xpdf is an open-source software suite that offers a range of tools and libraries for working with PDF files. It includes various command-line utilities and C++ libraries that enable PDF-related functionalities, such as parsing, rendering, printing, and text extraction. Xpdf's viewer, xpdf, is a separate GUI program; the command-line tools such as pdftotext print or save text instead of showing pages.
One of the key components of Xpdf is pdftotext, which is primarily known for extracting text content from PDF files. However, when used in combination with other tools like pdftops and pdfimages, Xpdf allows users to view the PDF content in different ways. The pdftotext tool proves valuable for extracting textual information from PDFs for further processing or analysis, and it offers options to specify which pages to extract text from.
Prerequisites
Before you begin, ensure you have the following prerequisites in place:
A C++ compiler such as GCC or Clang installed on your system. This tutorial uses Code::Blocks IDE for this purpose.
Xpdf command-line tools installed and accessible from the command line. Download Xpdf and install the version suited to your environment. Afterward, set the bin directory of Xpdf in the system environment variables path to access it from any location on the file system.
Creating a PDF Viewer Project
Open Code::Blocks: Launch the Code::Blocks IDE on your computer.
Create a New Project: Click on "File" from the top menu and select "New" from the drop-down menu. Then, click on "Project" from the submenu.
Choose Project Type: In the "New from template" window, choose "Console application", and click "Go". Then select the language "C/C++" and click "Next."
Enter Project Details: In the "Project title" field, give your project a name (e.g., "PDFViewer"). Choose the location where you want to save the project files, and click "Next."
Select Compiler: Choose the compiler you want to use for your project. By default, Code::Blocks should have automatically detected the available compilers on your system. If not, select a suitable compiler from the list, and click "Finish."
Steps to View Text from PDF in C++
Include the Necessary Headers
First, add the required header files to your main.cpp file:
#include <cstdlib>#include <iostream>#include <fstream>#include <cstdio>using namespace std; // Use standard namespace for convenience
#include <cstdlib>
#include <iostream>
#include <fstream>
#include <cstdio>

using namespace std; // Use standard namespace for convenience
In the main function, declare two strings: pdfPath and outputFilePath. pdfPath stores the path to the input PDF file, and outputFilePath stores the path where the extracted text will be saved as a plain text file.
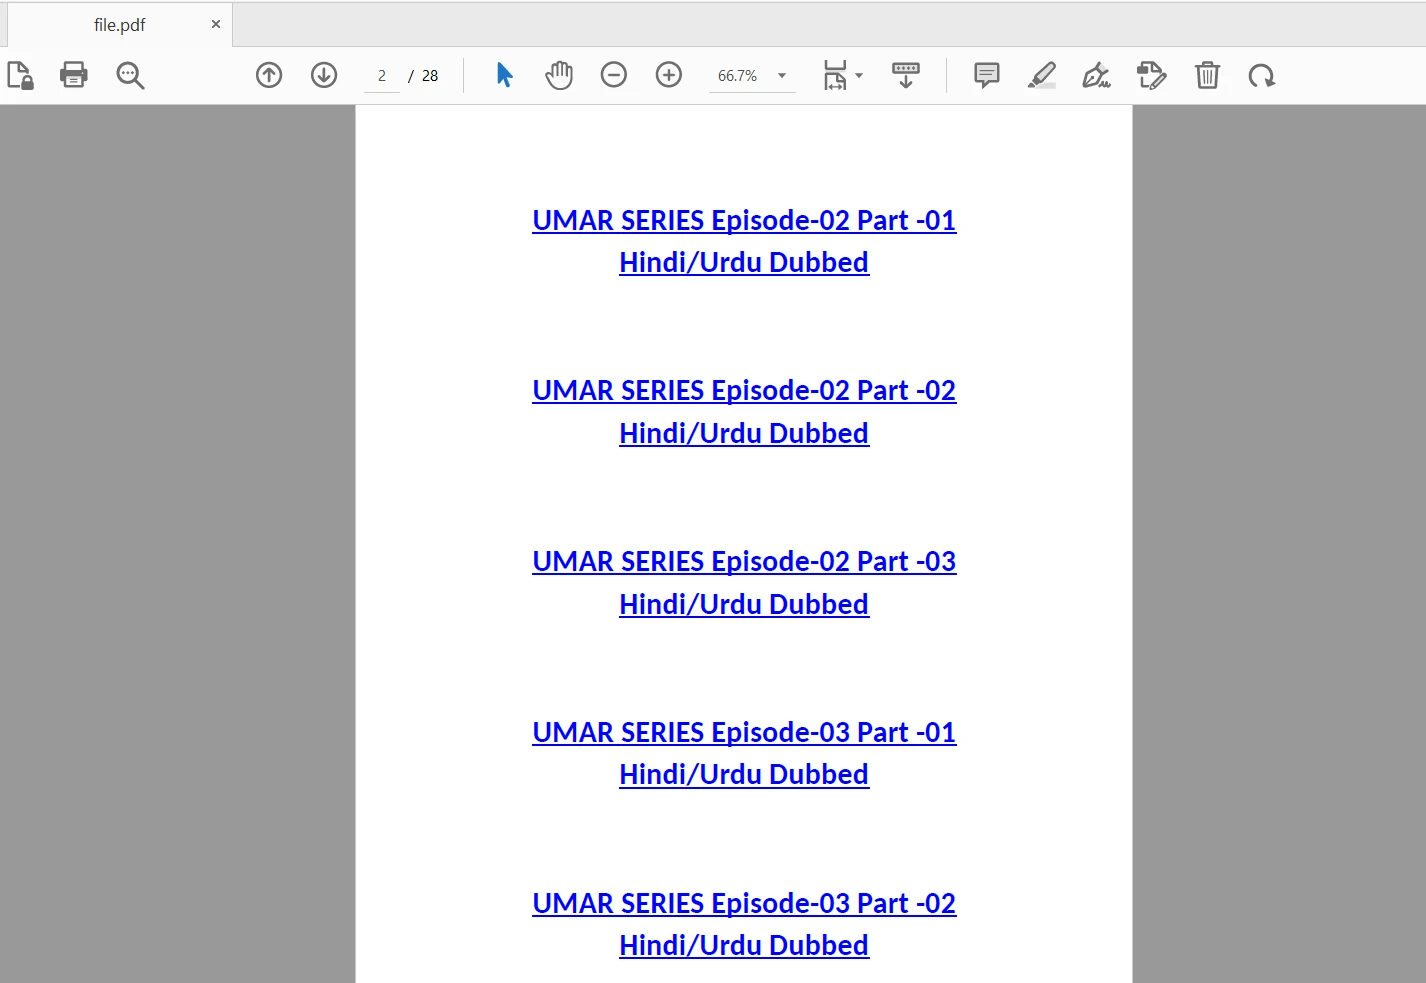
Input file is as follows:
Execute the pdftotext Command
// Construct the command to execute pdftotext with input and output pathsstring command = "pdftotext " + pdfPath + " " + outputFilePath;// Execute the command using system function and capture the statusint status = system(command.c_str());
// Construct the command to execute pdftotext with input and output paths
string command = "pdftotext " + pdfPath + " " + outputFilePath;

// Execute the command using system function and capture the status
int status = system(command.c_str());
C++
Here, the program constructs the pdftotext command using the pdfPath and outputFilePath variables so it extracts the PDF's text into the output file. The system function is then called to execute the command, and its return value is stored in the status variable.
The program checks the status variable to see if the pdftotext command executed successfully. If status is equal to 0, it means the text extraction was successful, and the program prints a success message. If the status is non-zero, it indicates an error, and the program prints an error message.
Read Extracted Text and Display
// Open the output file to read the extracted textifstream outputFile(outputFilePath);if (outputFile.is_open()) { string textContent; string line; while (getline(outputFile, line)) { textContent += line + "\n"; // Concatenate each line to the text content } outputFile.close(); cout << "Text content extracted from PDF:" << endl; cout << textContent << endl;} else{ cout << "Failed to open output file." << endl;}
// Open the output file to read the extracted text
ifstream outputFile(outputFilePath);
if (outputFile.is_open())
{
    string textContent;
    string line;
    while (getline(outputFile, line))
    {
        textContent += line + "\n"; // Concatenate each line to the text content
    }
    outputFile.close();
    cout << "Text content extracted from PDF:" << endl;
    cout << textContent << endl;
}
else
{
    cout << "Failed to open output file." << endl;
}
C++
In the above sample code, the program opens the outputFile (the text file generated by pdftotext), reads its content line by line, and stores it in the textContent string. Finally, it closes the file and prints the extracted text content on the console.
Remove Output File
If you do not need the editable output text file or want to free up disk space, at the end of the program delete it using the following command before ending the main function:
// Remove the output file to free up disk space and if output is not neededremove(outputFilePath.c_str());
// Remove the output file to free up disk space and if output is not needed
remove(outputFilePath.c_str());
C++
Compiling and Running the Program
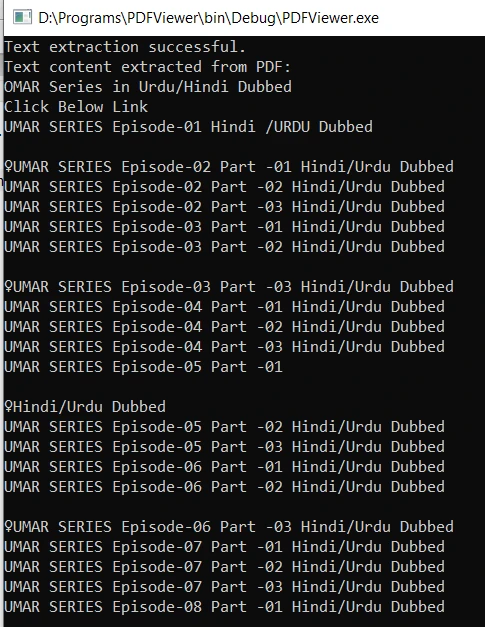
Build the code using the "Ctrl+F9" shortcut key. Upon successful compilation, running the executable will extract the text content from the specified PDF document and display it on the console. The output is as follows:
IronPDF for C++ (Coming Soon)
IronPDF for C++ is in development. The planned library will generate PDFs from HTML text or a URL, combine, split and modify existing PDFs, and extract text and images from them. Join the IronPDF for C++ beta program to get early access and help shape the API.
View PDF files in C#
IronPDF .NET C# Library is a .NET C# PDF library that reads PDF files inside C# applications. It extracts text and images from PDF documents, and it can rasterize PDF pages to images when you need to see a page rather than read its text. It is built on the Chromium web browser engine, so it can also create PDFs from HTML. Whether the source is a report, an invoice, or any other PDF, the extracted content can be processed in C# or shown in the console.
To install the IronPDF NuGet package in Visual Studio, follow these steps:
Open Visual Studio: Launch Visual Studio or any other IDE of your preference.
Create or Open Your Project: Create a new C# project or open an existing one where you want to install the IronPDF package.
Open the NuGet Package Manager: In Visual Studio, go to "Tools" > "NuGet Package Manager" > "Manage NuGet Packages for Solution". Alternatively, click on solution explorer and then select "Manage NuGet Packages for Solution".
Search for IronPDF: In the "NuGet Package Manager" window, click on the "Browse" tab, and then search for "IronPDF" in the search bar. Alternatively, visit the NuGet IronPDF Package and directly download the latest version of "IronPDF".
Select IronPDF Package: Find the "IronPDF" package and click on it to select it for your project.
Install IronPDF: Click the "Install" button to install the selected package.
However, you can also install IronPDF using NuGet Package Manager Console using the following command:
PM > Install-Package IronPdf
Install-Package IronPdf
Using IronPDF, you can perform operations such as extract text and images from PDF documents and display them in the console for viewing. The following code helps to achieve this task:
using IronPdf;using IronSoftware.Drawing;using System.Collections.Generic;// Extracting Image and Text content from Pdf Documents// Open a 128-bit encrypted PDFvar pdf = PdfDocument.FromFile("encrypted.pdf", "password");// Get all text to put in a search indexstring text = pdf.ExtractAllText();// Get all Imagesvar allImages = pdf.ExtractAllImages();// Or even find the precise text and images for each page in the documentfor (var index = 0 ; index < pdf.PageCount ; index++){ int pageNumber = index + 1; text = pdf.ExtractTextFromPage(index); List<AnyBitmap> images = pdf.ExtractBitmapsFromPage(index); // Further processing here...}
using IronPdf;
using IronSoftware.Drawing;
using System.Collections.Generic;

// Extracting Image and Text content from Pdf Documents
// Open a 128-bit encrypted PDF
var pdf = PdfDocument.FromFile("encrypted.pdf", "password");

// Get all text to put in a search index
string text = pdf.ExtractAllText();

// Get all Images
var allImages = pdf.ExtractAllImages();

// Or even find the precise text and images for each page in the document
for (var index = 0 ; index < pdf.PageCount ; index++)
{
    int pageNumber = index + 1;
    text = pdf.ExtractTextFromPage(index);
    List<AnyBitmap> images = pdf.ExtractBitmapsFromPage(index);
    // Further processing here...
}
Imports IronPdfImports IronSoftware.DrawingImports System.Collections.Generic' Extracting Image and Text content from Pdf Documents' Open a 128-bit encrypted PDFPrivate pdf = PdfDocument.FromFile("encrypted.pdf", "password")' Get all text to put in a search indexPrivate text As String = pdf.ExtractAllText()' Get all ImagesPrivate allImages = pdf.ExtractAllImages()' Or even find the precise text and images for each page in the documentFor index = 0 To pdf.PageCount - 1 Dim pageNumber As Integer = index + 1 text = pdf.ExtractTextFromPage(index) Dim images As List(Of AnyBitmap) = pdf.ExtractBitmapsFromPage(index) ' Further processing here...Next index
ImportsIronPdfImportsIronSoftware.DrawingImportsSystem.Collections.Generic' Extracting Image and Text content from Pdf Documents' Open a 128-bit encrypted PDFPrivate pdf = PdfDocument.FromFile("encrypted.pdf", "password")' Get all text to put in a search indexPrivate text AsString = pdf.ExtractAllText()' Get all ImagesPrivate allImages = pdf.ExtractAllImages()' Or even find the precise text and images for each page in the documentFor index = 0 To pdf.PageCount - 1 Dim pageNumber AsInteger = index + 1 text = pdf.ExtractTextFromPage(index) Dim images AsList(OfAnyBitmap) = pdf.ExtractBitmapsFromPage(index) ' Further processing here...Next index
Imports IronPdf
Imports IronSoftware.Drawing
Imports System.Collections.Generic

' Extracting Image and Text content from Pdf Documents
' Open a 128-bit encrypted PDF
Private pdf = PdfDocument.FromFile("encrypted.pdf", "password")

' Get all text to put in a search index
Private text As String = pdf.ExtractAllText()

' Get all Images
Private allImages = pdf.ExtractAllImages()

' Or even find the precise text and images for each page in the document
For index = 0 To pdf.PageCount - 1
	Dim pageNumber As Integer = index + 1
	text = pdf.ExtractTextFromPage(index)
	Dim images As List(Of AnyBitmap) = pdf.ExtractBitmapsFromPage(index)
	' Further processing here...
Next index
IronPDF for .NET extracts text and images from PDFs in C# and can rasterize pages to images. A Free Trial License is available to test for commercial purposes.
Conclusion
This article showed how to extract and view the contents of a PDF document in C++ using the Xpdf command-line tool. This approach lets you process and analyze the extracted text within your C++ applications. pdftotext handles text; rendering pages needs pdftopng or a library. The C++ PDF reader tutorial shows the same tool from a reading angle.
IronPDF for C++ is coming, and it is planned to extract text and images from PDFs. Join the beta for early access.
Curtis Chau holds a Bachelor’s degree in Computer Science (Carleton University) and specializes in front-end development with expertise in Node.js, TypeScript, JavaScript, and React. Passionate about crafting intuitive and aesthetically pleasing user interfaces, Curtis enjoys working with modern frameworks and creating well-structured, visually appealing manuals.