



已更新 2026年4月21日
如何在 Java 中将 TIFF 转换为 PDF
本完整指南将引导您在 Java 中使用 IronPDF 无缝地将 TIFF 图像转换为 PDF。
阅读更多

本教程将向您展示如何使用IronPDF 适用于 Java从PDF文件中提取数据。设置环境、导入库、读取输入文件和提取所需数据的步骤均通过代码示例进行解释。
IronPDF是一个软件库,为开发人员提供了在Java应用程序中生成、编辑和提取PDF文件数据的能力。 它允许您从HTML文档、图片等创建PDF,以及合并多个PDF、拆分PDF文件和操作现有PDF。 IronPDF还提供了通过密码保护功能和向PDF添加数字签名来保护PDF文件的功能,还有其他功能。
IronPDF for Java由Iron Software开发和维护。 其评价最高的功能之一是从PDF文件以及HTML和URL中提取文本和数据。
要使用IronPDF从PDF文件中提取数据,您必须满足以下先决条件:
如果符合所有要求,安装IronPDF for Java非常简单。 本指南将使用JetBrains的IntelliJ IDEA演示安装并运行示例代码。
以下是要执行的操作:
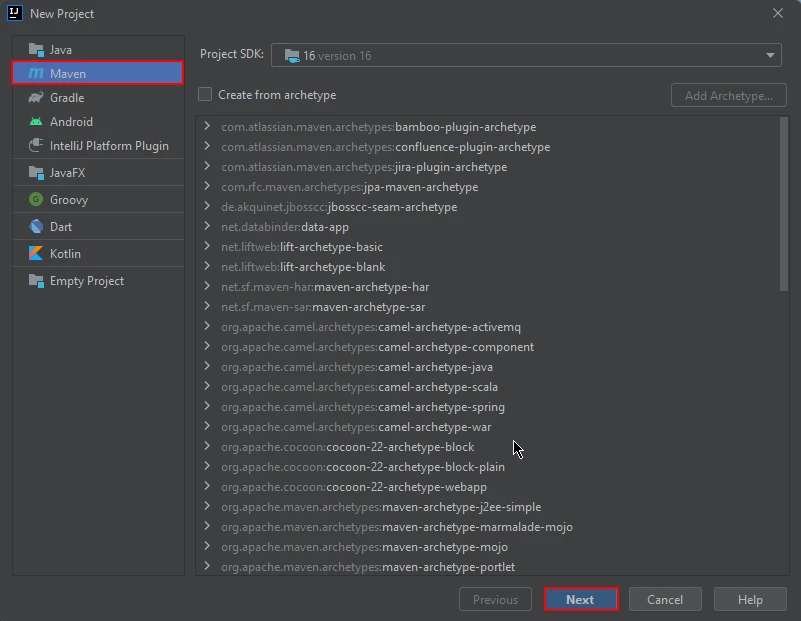 New Maven Project in IntelliJ
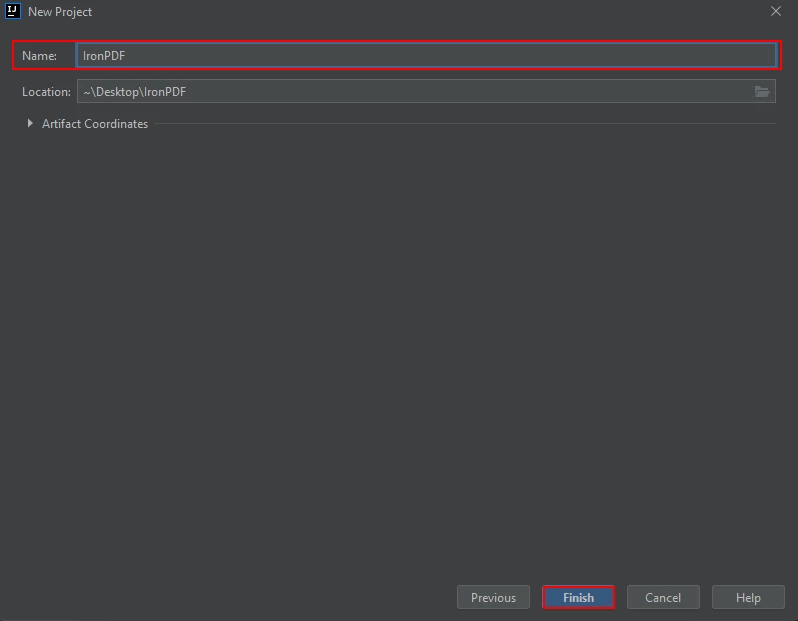 Name the Maven Project and click Finish
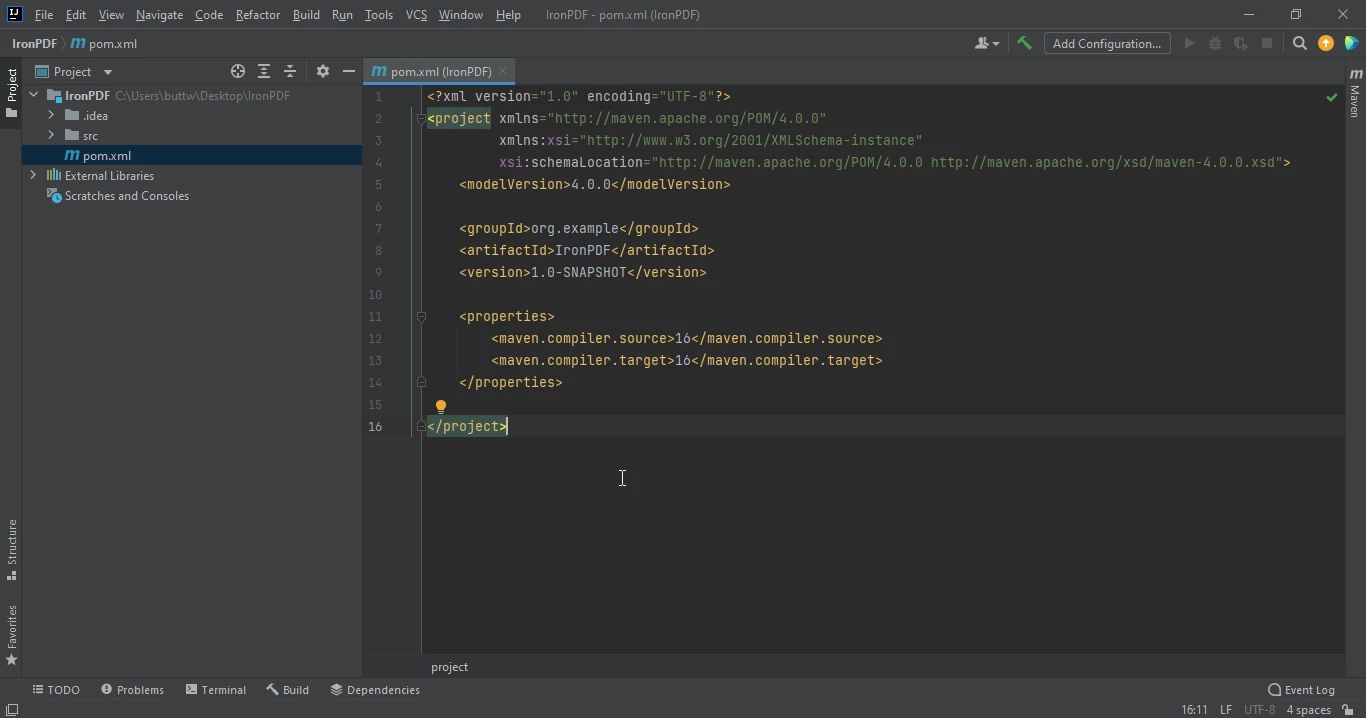 The pom.xml file
在pom.xml文件中添加以下依赖项,或者您可以从Sonatype Central上的IronPDF库页面下载JAR文件。
<dependency>
    <groupId>com.ironsoftware</groupId>
    <artifactId>ironpdf</artifactId>
    <version>1.0.0</version> <!-- replace with the latest version -->
</dependency>一旦您将依赖项放置在pom.xml文件中,文件的右上角将出现一个小图标。
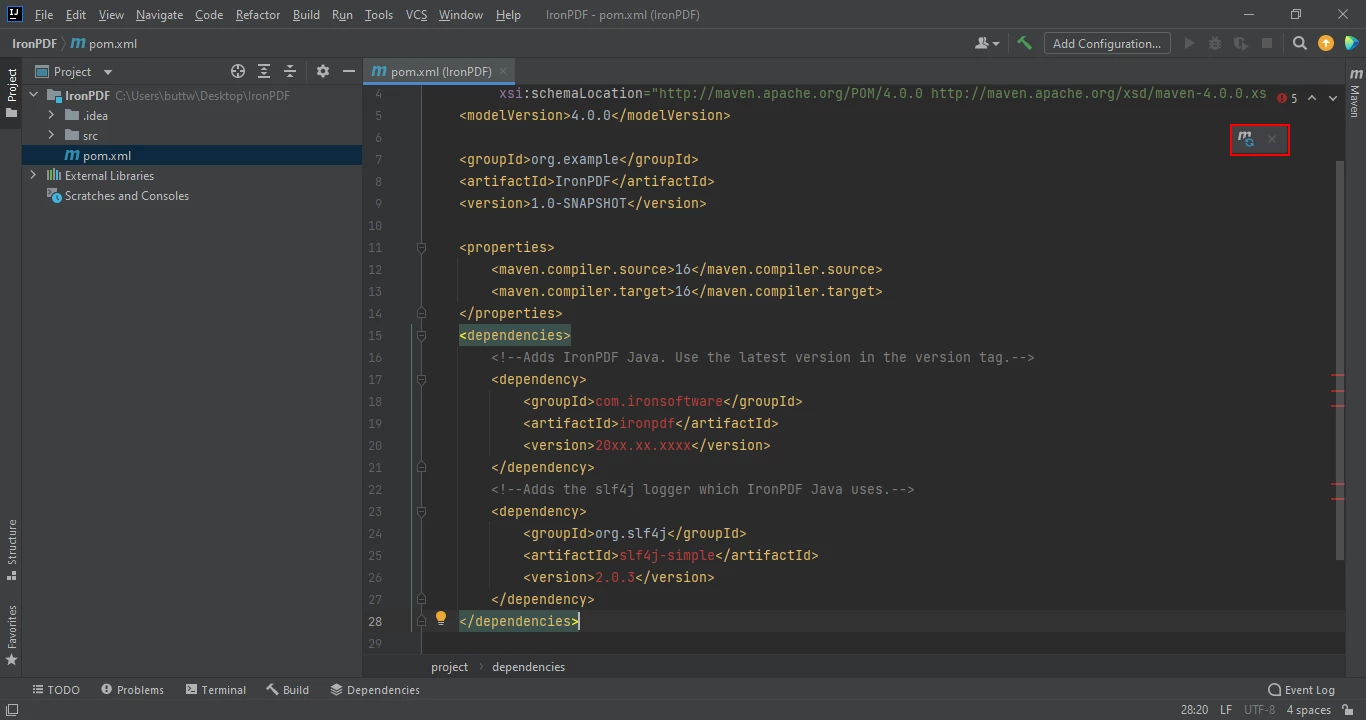 Click the floating icon to install the Maven dependencies automatically
通过点击此按钮安装IronPDF for Java的Maven依赖项。 根据您的互联网连接速度,这应该只需几分钟。
IronPDF是一个用于创建、编辑和从PDF文档中提取数据的Java库。 它提供了一个简单的API来从PDF文件、URL和表格中提取文本。
使用IronPDF 适用于 Java,您可以轻松地从PDF文档中提取文本数据。 以下是从PDF文件中提取数据的示例代码。
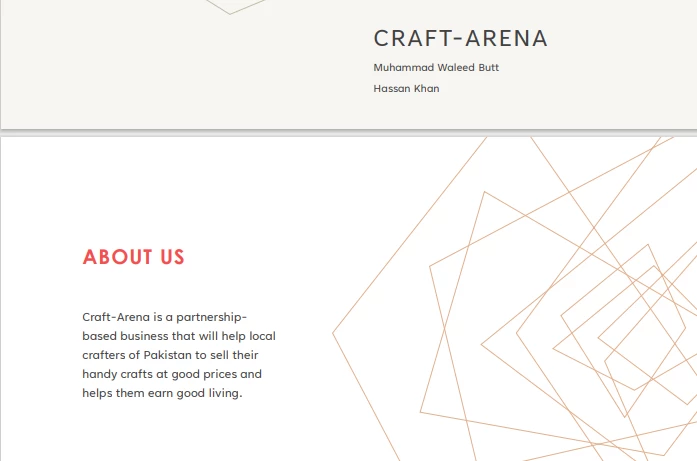 PDF Input
// Import the necessary IronPDF package for working with PDF documents
import com.ironsoftware.ironpdf.PdfDocument;

import java.io.IOException;
import java.nio.file.Paths;

public class Main {
    public static void main(String[] args) throws IOException {
        // Load the PDF document from the specified file
        PdfDocument pdf = PdfDocument.fromFile(Paths.get("business plan.pdf"));

        // Extract all text from the PDF document
        String text = pdf.extractAllText();

        // Print the extracted text to the console
        System.out.println("Text extracted from the PDF: " + text);
    }
}源代码生成以下输出:
> Text extracted from the PDF:
>
> CRAFT-ARENA
>
> Muhammad Waleed Butt
>
> Hassan Khan
>
> ABOUT US
>
> Craft-Arena is a partnership based business that will help local crafters of Pakistan to sell their handicrafts at good prices and helps them earn a good living.IronPDF for Java在运行时将URL转换为PDF并从中提取文本。 此示例将展示从URLs中提取文本的源代码。
// Import the necessary IronPDF package for working with PDF documents
import com.ironsoftware.ironpdf.PdfDocument;

import java.io.IOException;

public class Main {
    public static void main(String[] args) throws IOException {
        // Convert a URL to a PDF and load it into a PdfDocument
        PdfDocument pdf = PdfDocument.renderUrlAsPdf("https://ironpdf.com/java/");

        // Extract all text from the PDF document
        String text = pdf.extractAllText();

        // Print the extracted text to the console
        System.out.println("Text extracted from the URLs: " + text);
    }
}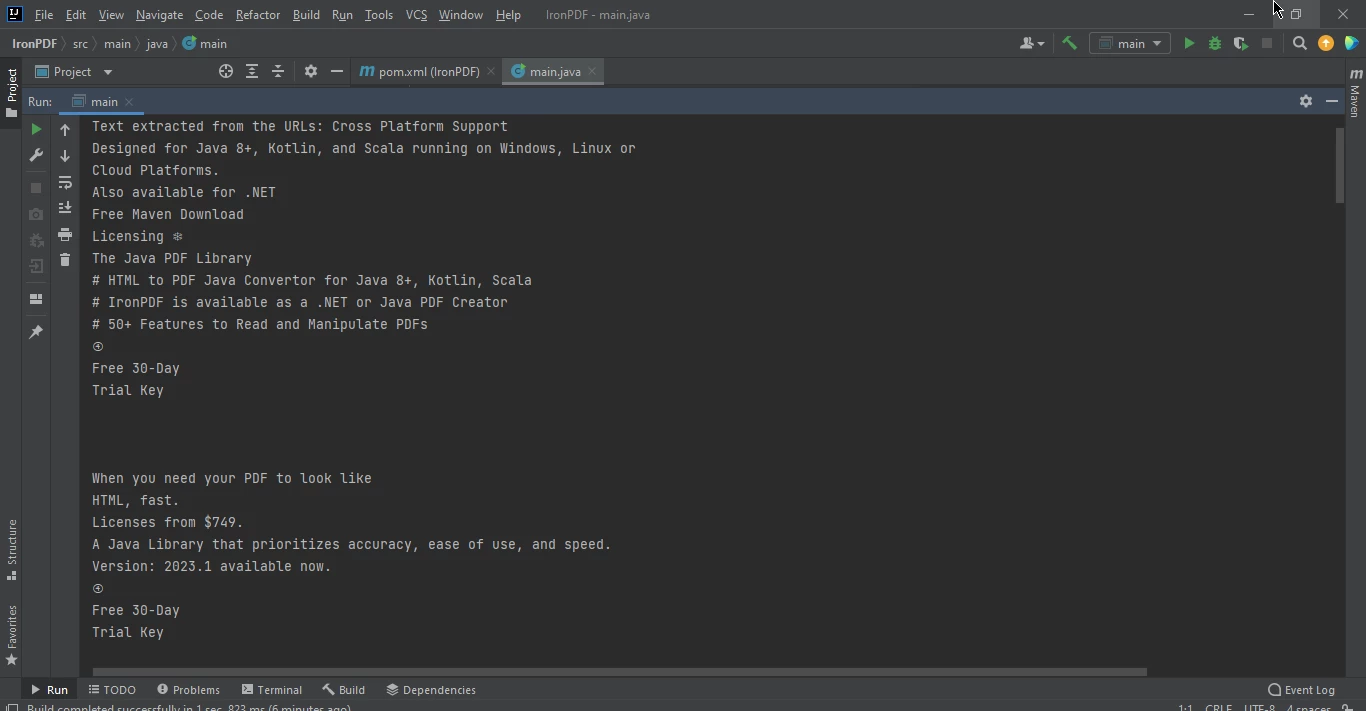 Extracted Web Page Data
要从PDF中提取表格数据,使用IronPDF for Java非常简单; 您只需拥有一个包含表格的PDF,并运行以下代码。
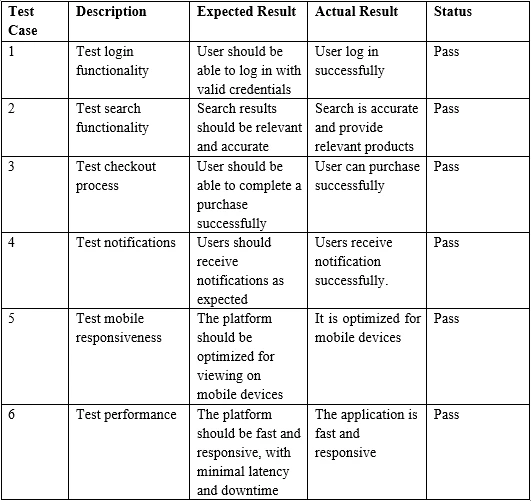 Sample PDF Table Input
// Import the necessary IronPDF package for working with PDF documents
import com.ironsoftware.ironpdf.PdfDocument;

import java.io.IOException;
import java.nio.file.Paths;

public class Main {
    public static void main(String[] args) throws IOException {
        // Load the PDF document from the specified file
        PdfDocument pdf = PdfDocument.fromFile(Paths.get("table.pdf"));

        // Extract all text from the PDF document, including table data
        String text = pdf.extractAllText();

        // Print the extracted table data to the console
        System.out.print("Text extracted from the Marked tables: " + text);
    }
}> Test Case Description Expected Result Actual Result Status
>
> 1 Test login functionality User should be able to log in with valid credentials
>
> User log in successfully Pass
>
> 2 Test search functionality Search results should be relevant and accurate
>
> Search is accurate and provide relevant products Pass
>
> 3 Test checkout process User should be able to complete a purchase successfully
>
> User can purchase successfully Pass总之,本教程演示了如何使用IronPDF for Java从PDF文件中提取数据,特别是表格数据。
有关更多信息,请参考IronPDF网站上的从PDF提取文本示例。
IronPDF是一个包含商业许可证详细信息的库,起价为$999。 不过,您可以使用IronPDF试用许可证进行免费试用在生产中评估它。

Curtis Chau 拥有卡尔顿大学的计算机科学学士学位,专注于前端开发,精通 Node.js、TypeScript、JavaScript 和 React。他热衷于打造直观且美观的用户界面,喜欢使用现代框架并创建结构良好、视觉吸引力强的手册。

当您需要PDF看起来像HTML时,速度快。





