



Updated April 21, 2026
How To Convert TIFF To PDF in Java
This comprehensive guide will walk you through the steps on how to convert TIFF image to PDF seamlessly in Java using IronPDF.
Read More

This article will explore how to create a PDF reader, to open a PDF file in your software application programmatically. To perform this task effectively, IronPDF for Java is one such system library which helps open and read PDF files using the filename in Java programs.
fromFile method to load existing PDF documentsextractAllText method to extract embedded text in PDFsextractTextFromPage methodThe IronPDF - Java Library is built on top of the already successful .NET Framework. This makes IronPDF a versatile tool for working with PDF documents compared to other class libraries such as Apache PDFBox. It provides the facility to extract and parse content, load text, and load images. It also provides options to customize the PDF pages such as page layout, margins, header and footer, page orientation, and much more.
In addition to this, IronPDF also supports conversion from other file formats, protecting PDFs with a password, digital signing, merging, and splitting PDF documents.
To use IronPDF to make a Java PDF reader, it is necessary to ensure that the following components are installed on the computer:
pom.xml file as shown in the example below:<!-- Add Maven dependencies for IronPDF -->
<dependencies>
<!-- IronPDF Dependency -->
<dependency>
<groupId>com.ironsoftware</groupId>
<artifactId>ironpdf</artifactId>
<version>your-version-here</version>
</dependency>
<!-- SLF4J Dependency necessary for logging -->
<dependency>
<groupId>org.slf4j</groupId>
<artifactId>slf4j-api</artifactId>
<version>1.7.32</version>
</dependency>
</dependencies>Firstly, add the following code on top of the Java source file to reference all the required methods from IronPDF:
import com.ironsoftware.ironpdf.*;
// Necessary imports from IronPDF libraryNext, configure IronPDF with a valid license key to use its methods. Invoke the setLicenseKey method in the main method.
License.setLicenseKey("Your license key");
// Set your IronPDF license key - required for full versionNote: You can get a free trial license key to create, read, and print PDFs.
To read PDF files, there must be PDF files, or one can be created. This article will use an already created PDF file. The code is simple and a two-step process to extract text from the document:
// Load the PDF document from file
PdfDocument pdf = PdfDocument.fromFile(Paths.get("assets/sample.pdf"));
// Extract all text from the PDF
String text = pdf.extractAllText();
// Print the extracted text
System.out.println(text);In the above code, [fromFile](/java/object-reference/api/com/ironsoftware/ironpdf/PdfDocument.html#fromFile(java.nio.file.Path) opens a PDF document. The Paths.get method gets the directory of the file and is ready to extract content from the file. Then, [extractAllText](/java/object-reference/api/com/ironsoftware/ironpdf/PdfDocument.html#extractAllText() reads all the text in the document.
The output is below:
 Reading PDF Text Output
IronPDF can also read content from a specific page in a PDF. The extractTextFromPage method uses a PageSelection object to accept a range of page(s) from which text will be read.
In the following example, the text is extracted from the second page of the PDF document. PageSelection.singlePage takes the index of the page which needs to be extracted (index starting from 0).
// Load the PDF document from file
PdfDocument pdf = PdfDocument.fromFile(Paths.get("assets/sample.pdf"));
// Extract text from the second page (page index based, starts at 0, so 1 means second page)
String text = pdf.extractTextFromPage(PageSelection.singlePage(1));
// Print the extracted text from the specified page
System.out.println(text);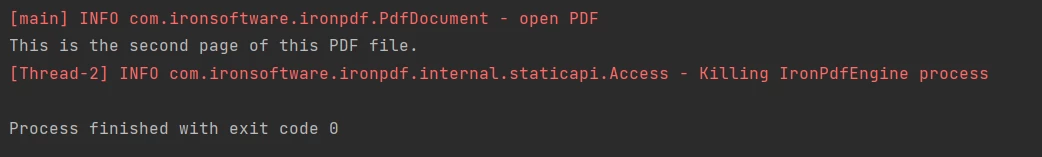 Reading PDF Text Output
Other methods available in the PageSelection class which can be used to extract text from various pages include: [firstPage](/java/object-reference/api/com/ironsoftware/ironpdf/edit/PageSelection.html#lastPage(), [lastPage](/java/object-reference/api/com/ironsoftware/ironpdf/edit/PageSelection.html#firstPage(), [pageRange](/java/object-reference/api/com/ironsoftware/ironpdf/edit/PageSelection.html#pageRange(int,int), and [allPages](/java/object-reference/api/com/ironsoftware/ironpdf/edit/PageSelection.html#allPages().
Search text can also be performed from a newly generated PDF file from either an HTML file or URL. The following sample code generates PDFs from URL and extracts all text from the website.
// Generate PDF from a URL
PdfDocument pdf = PdfDocument.renderUrlAsPdf("https://unsplash.com/");
// Extract all text from the generated PDF
String text = pdf.extractAllText();
// Print the extracted text from the URL
System.out.println("Text extracted from the website: " + text);
Read from a New File
IronPDF can also be used to extract images from PDF files.
The complete code is as follows:
import com.ironsoftware.ironpdf.License;
import com.ironsoftware.ironpdf.PdfDocument;
import com.ironsoftware.ironpdf.edit.PageSelection;

import java.io.IOException;
import java.nio.file.Paths;

public class Main {
    public static void main(String[] args) throws IOException {
        // Set the IronPDF license key for commercial use
        License.setLicenseKey("YOUR LICENSE KEY HERE");

        // Read text from a specific page in an existing PDF
        PdfDocument pdf = PdfDocument.fromFile(Paths.get("assets/sample.pdf"));
        String text = pdf.extractTextFromPage(PageSelection.singlePage(1));
        System.out.println(text);

        // Read all text from a PDF generated from a URL
        pdf = PdfDocument.renderUrlAsPdf("https://unsplash.com/");
        text = pdf.extractAllText();
        System.out.println("Text extracted from the website: " + text);
    }
}This article explained how to open and read PDFs in Java using IronPDF.
IronPDF helps easily create PDFs from HTML or URL and convert from different file formats. It also helps in getting PDF tasks done quickly and easily.
Try IronPDF for 30 days with a free trial and find out how well it works for you in production. Explore commercial licensing options for IronPDF which start only from $999.

Curtis Chau holds a Bachelor’s degree in Computer Science (Carleton University) and specializes in front-end development with expertise in Node.js, TypeScript, JavaScript, and React. Passionate about crafting intuitive and aesthetically pleasing user interfaces, Curtis enjoys working with modern frameworks and creating well-structured, visually appealing manuals.



IronPDF is a part of IRONSUITE
10 .NET API products for your office documents


When you need your PDF to look like HTML, fast.

