


已更新 2026年4月23日
简化 .NET 与 Microsoft.Extensions.AI 的 LLM 集成
AI正在改变软件开发,但将大型语言模型(LLM)集成到.NET中直到现在一直很复杂。通过IronPdf.AI,将AI集成更进一步,该产品为.NET应用程序带来了OpenAI驱动的PDF解析、数据提取和内容摘要。
阅读更多

在当今的开发世界中,处理PDF是需要处理文档、表单或报告的应用程序的常见需求。 无论您是在构建电子商务平台、文档管理系统,还是仅需处理发票,从PDF中提取和搜索文本都可能至关重要。 本文将指导您如何使用C# string.Contains()与IronPDF结合,在.NET项目中搜索和提取PDF文件中的文本。
在执行搜索时,您可能需要根据特定字符串子字符串要求执行字符串比较。 在这种情况下,C#提供了类似string.Contains()这样的选项,这是最简单的比较形式之一。
如果您需要指定是否忽略大小写,可以使用StringComparison枚举。 这使您可以选择所需的字符串比较类型,例如序数比较或不区分大小写的比较。
如果您想处理字符串中的特定位置,如第一个字符位置或最后一个字符位置,可以随时使用Substring来隔离字符串的某些部分以进行进一步处理。
如果您正在查找空字符串检查或其他边界情况,请确保在逻辑中处理这些场景。
如果您正在处理大型文档,优化文本提取的起始位置非常有用,以便仅提取相关部分而不是整个文档。 如果您想避免过度加载内存和处理时间,这将特别有用。
如果您不确定用于比较规则的最佳方法,请考虑具体的执行方法以及您对不同场景中搜索行为的要求(例如,匹配多个术语、处理空格等)。
如果您的需求超出了简单的子字符串检查并需要更高级的模式匹配,请考虑使用正则表达式,这在处理PDF时提供了显著的灵活性。
如果您还没有,请立即尝试IronPDF的免费试用,探索其功能并查看它如何简化您的PDF处理任务。 无论您是在构建文档管理系统、处理发票,还是仅需从PDF中提取数据,IronPDF都是完成工作的完美工具。
IronPDF是一个强大的库,旨在帮助在.NET生态系统中处理PDF的开发人员。 它使您能够轻松创建、读取、编辑和操作PDF文件,而无需依赖外部工具或复杂的配置。
IronPDF提供了一系列广泛的功能,用于在C#应用程序中处理PDF。 一些关键功能包括:
***文本提取:**从 PDF 中提取纯文本或结构化数据。
IronPDF设计简单易用,但也足够灵活以处理涉及PDF的复杂场景。 它与.NET Core和.NET Framework无缝协作,适合任何基于.NET的项目。
要使用IronPDF,请在Visual Studio中通过NuGet包管理器安装它:
在深入研究查找PDF之前,首先了解如何使用IronPDF从PDF中提取文本。
IronPDF提供了一个简单的API来从PDF文档中提取文本。 这使您能够轻松在PDF中搜索特定内容。
以下示例演示了如何使用IronPDF从PDF中提取文本:
using IronPdf;
using System;

public class Program
{
    public static void Main(string[] args)
    {
        // Load the PDF from a file
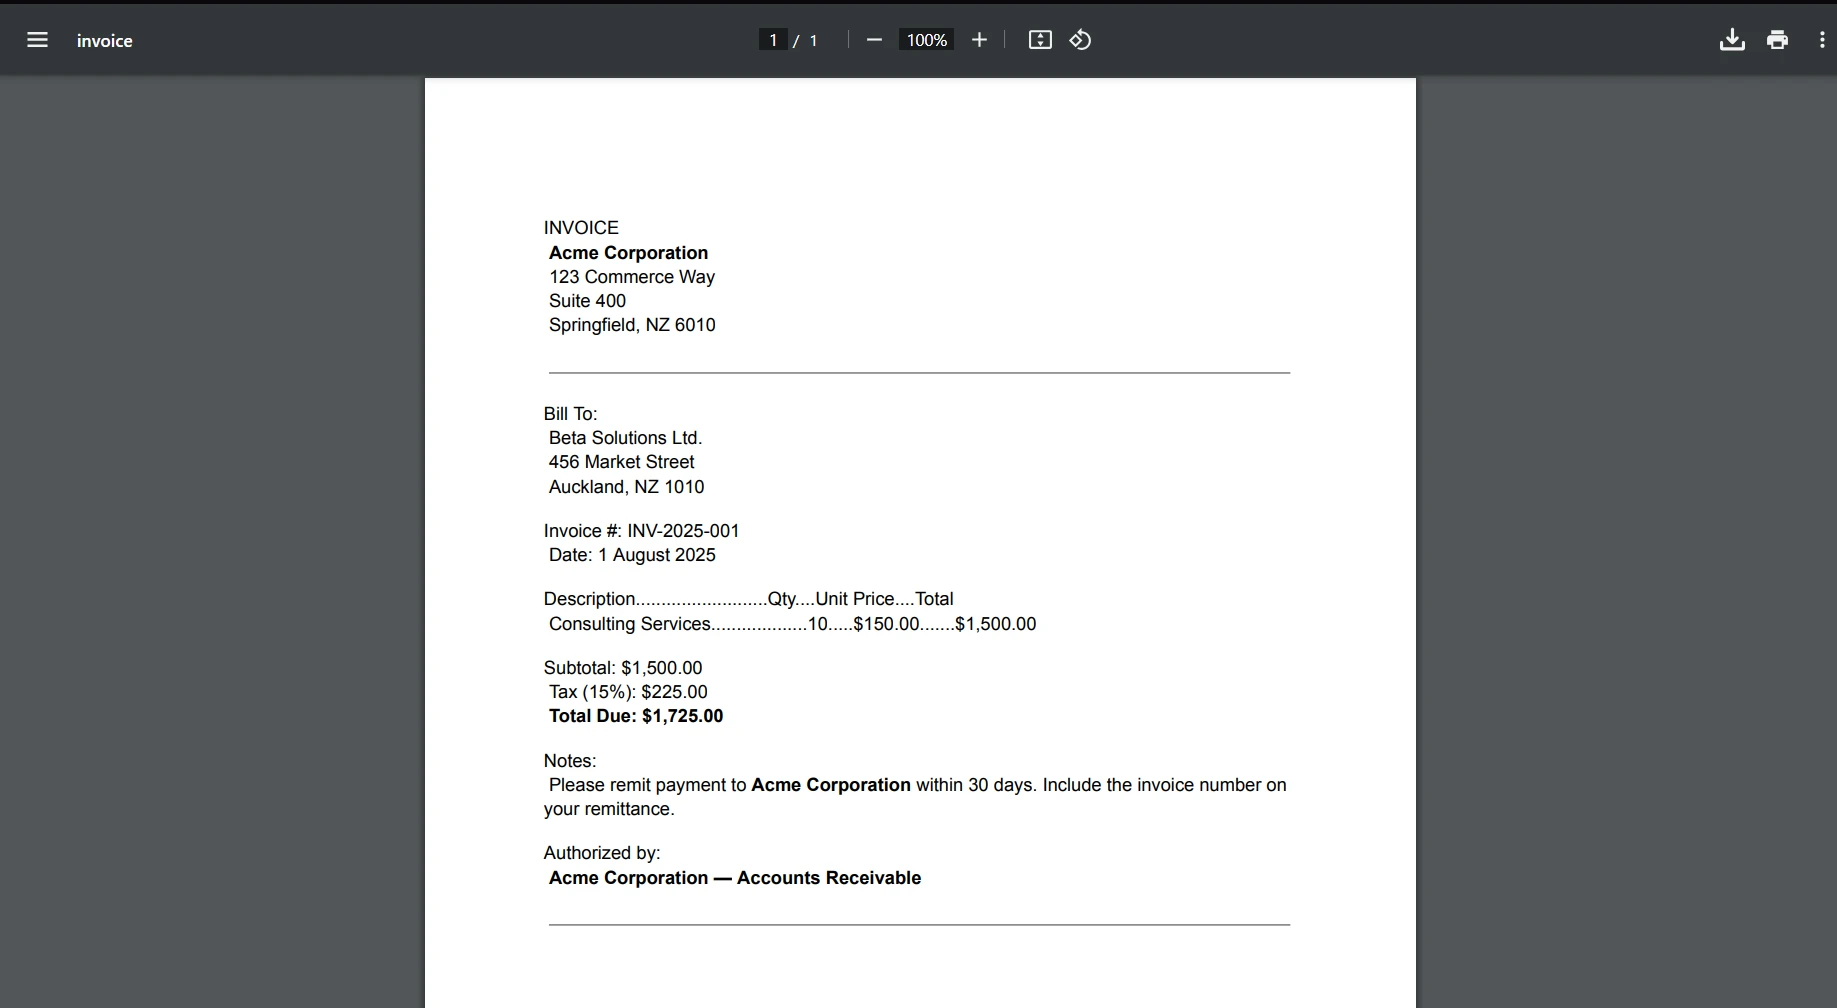
        PdfDocument pdf = PdfDocument.FromFile("invoice.pdf");
        // Extract all text from the PDF
        string text = pdf.ExtractAllText();
        // Optionally, print the extracted text to the console
        Console.WriteLine(text);
    }
}Imports IronPdf
Imports System
Public Class Program
Public Shared Sub Main(ByVal args() As String)
' Load the PDF from a file
Dim pdf As PdfDocument = PdfDocument.FromFile("invoice.pdf")
' Extract all text from the PDF
Dim text As String = pdf.ExtractAllText()
' Optionally, print the extracted text to the console
Console.WriteLine(text)
End Sub
End Class在此示例中,ExtractAllText()方法从PDF文档中提取所有文本。 然后可以处理这些文本以搜索特定的关键字或短语。
一旦您从PDF中提取了文本,就可以使用C#内置的string.Contains()方法来搜索特定的单词或短语。
string.Contains()方法返回一个布尔值,指示指定字符串是否存在于字符串中。 这对于基本的文本搜索特别有用。
以下是如何使用string.Contains()在提取的文本中搜索关键字:
bool isFound = text.Contains("search term", StringComparison.OrdinalIgnoreCase);Dim isFound As Boolean = text.Contains("search term", StringComparison.OrdinalIgnoreCase)让我们以一个实际例子进一步分解这一点。 假设您想查找特定的发票号码是否存在于PDF发票文档中。
下面是如何实现的完整示例:
using IronPdf;
using System;

public class Program
{
    public static void Main(string[] args)
    {
        string searchTerm = "INV-12345";
        // Load the PDF from a file
        PdfDocument pdf = PdfDocument.FromFile("exampleInvoice.pdf");
        // Extract all text from the PDF
        string text = pdf.ExtractAllText();
        // Search for the specific invoice number
        bool isFound = text.Contains(searchTerm, StringComparison.OrdinalIgnoreCase);
        // Provide output based on whether the search term was found
        if (isFound)
        {
            Console.WriteLine($"Invoice number: {searchTerm} found in the document");
        }
        else
        {
            Console.WriteLine($"Invoice number {searchTerm} not found in the document");
        }
    }
}Imports IronPdf
Imports System
Public Class Program
Public Shared Sub Main(ByVal args() As String)
Dim searchTerm As String = "INV-12345"
' Load the PDF from a file
Dim pdf As PdfDocument = PdfDocument.FromFile("exampleInvoice.pdf")
' Extract all text from the PDF
Dim text As String = pdf.ExtractAllText()
' Search for the specific invoice number
Dim isFound As Boolean = text.Contains(searchTerm, StringComparison.OrdinalIgnoreCase)
' Provide output based on whether the search term was found
If isFound Then
Console.WriteLine($"Invoice number: {searchTerm} found in the document")
Else
Console.WriteLine($"Invoice number {searchTerm} not found in the document")
End If
End Sub
End Class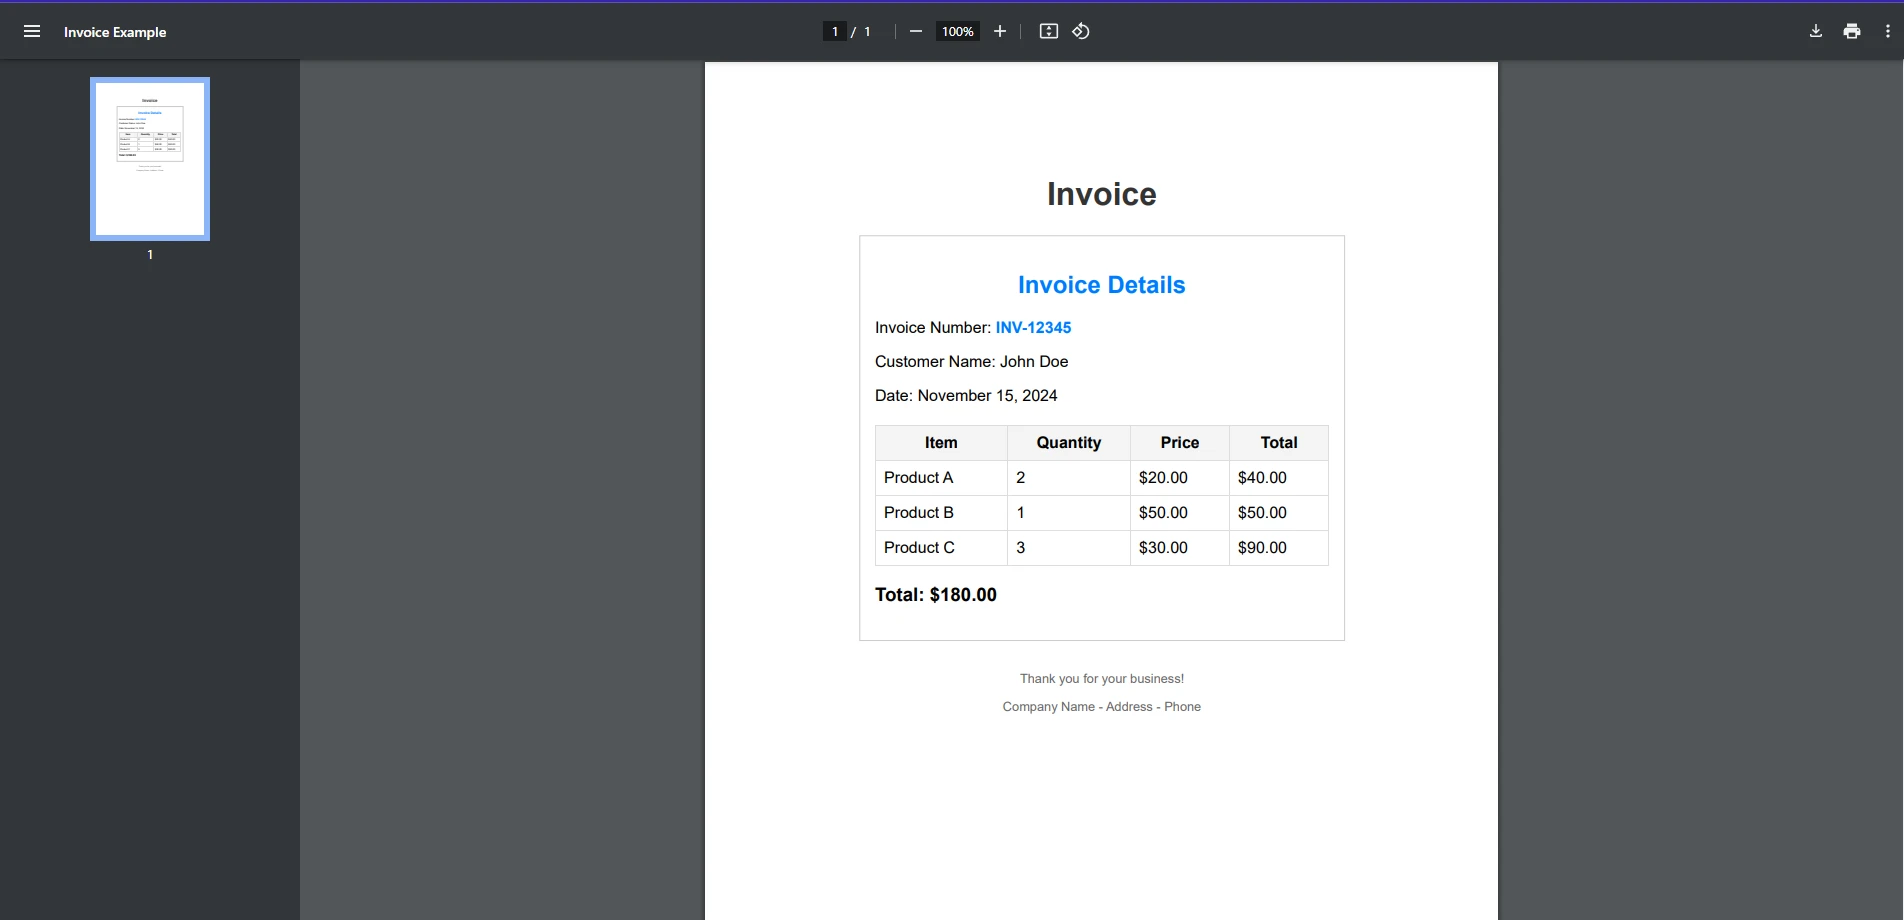
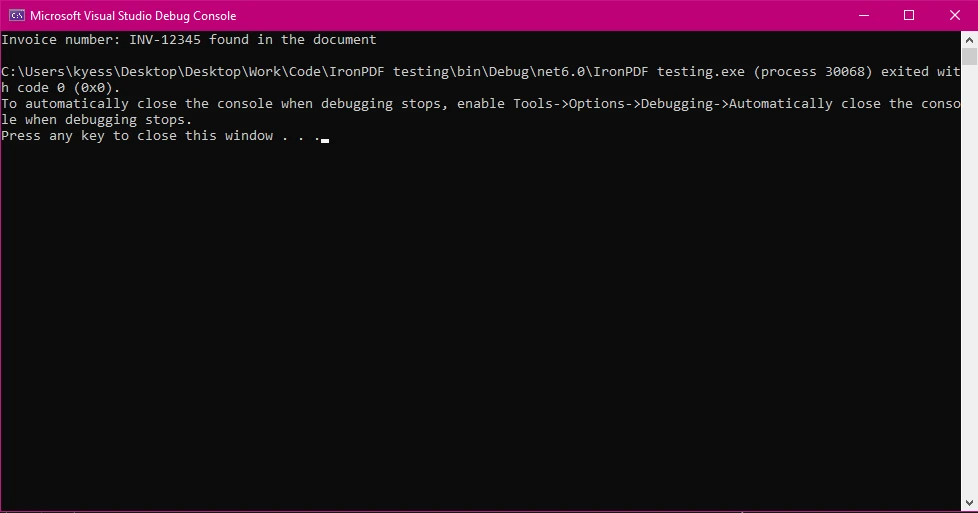
在此示例中:
INV-12345。StringComparison.OrdinalIgnoreCase。虽然string.Contains()适用于简单的子字符串搜索,您可能需要执行更复杂的搜索,例如查找模式或一系列关键词。 为此,您可以使用正则表达式。
以下是如何使用正则表达式在PDF文本中搜索任何有效发票号格式的示例:
using IronPdf;
using System;
using System.Text.RegularExpressions;

public class Program
{
    public static void Main(string[] args)
    {
        // Define a regex pattern for a typical invoice number format (e.g., INV-12345)
        string pattern = @"INV-\d{5}";
        // Load the PDF from a file
        PdfDocument pdf = PdfDocument.FromFile("exampleInvoice.pdf");
        // Extract all text from the PDF
        string text = pdf.ExtractAllText();
        // Perform the regex search
        Match match = Regex.Match(text, pattern);
        // Check if a match was found
        if (match.Success)
        {
            Console.WriteLine($"Invoice number found: {match.Value}");
        }
        else
        {
            Console.WriteLine("No matching invoice number found.");
        }
    }
}Imports IronPdf
Imports System
Imports System.Text.RegularExpressions
Public Class Program
Public Shared Sub Main(ByVal args() As String)
' Define a regex pattern for a typical invoice number format (e.g., INV-12345)
Dim pattern As String = "INV-\d{5}"
' Load the PDF from a file
Dim pdf As PdfDocument = PdfDocument.FromFile("exampleInvoice.pdf")
' Extract all text from the PDF
Dim text As String = pdf.ExtractAllText()
' Perform the regex search
Dim match As Match = Regex.Match(text, pattern)
' Check if a match was found
If match.Success Then
Console.WriteLine($"Invoice number found: {match.Value}")
Else
Console.WriteLine("No matching invoice number found.")
End If
End Sub
End Class此代码将搜索遵循模式INV-XXXXX的任何发票号码,其中XXXXX是一系列数字。
在处理PDF时,特别是大型或复杂文档时,请牢记一些最佳实践:
***处理大型 PDF:**如果您要处理大型 PDF,最好将文本分成较小的块(按页)提取,以减少内存使用量并提高性能。 ***处理特殊编码:**注意 PDF 中的编码和特殊字符。 IronPDF通常对此处理得很好,但复杂的布局或字体可能需要额外的处理。
IronPDF很容易与.NET项目集成。 通过NuGet下载并安装IronPDF库后,只需将其导入到您的C#代码库中,如上面的示例所示。
IronPDF的灵活性使您能够构建复杂的文档处理工作流程,例如:
IronPDF使处理PDF变得简单高效,尤其是当您需要从PDF中提取和搜索文本时。 通过将C#的string.Contains()方法与IronPDF的文本提取功能结合,您可以快速在.NET应用程序中搜索和处理PDF。
如果您还没有,请立即尝试IronPDF的免费试用,以探索其功能并查看它如何简化您的PDF处理任务。 无论您是在构建文档管理系统、处理发票,还是仅需从PDF中提取数据,IronPDF都是完成工作的完美工具。
要开始使用IronPDF,请下载免费试用,亲身体验其强大的PDF操作功能。 访问IronPDF的网站立即开始。
Jacob Mellor 是 Iron Software 的首席技术官,也是一位开创 C# PDF 技术的有远见的工程师。作为 Iron Software 核心代码库的原始开发者,他从公司成立之初就开始塑造公司的产品架构,与首席执行官 Cameron Rimington 一起将公司转变为一家拥有 50 多名员工的公司,为 NASA、特斯拉和全球政府机构提供服务。

当您需要PDF看起来像HTML时,速度快。



