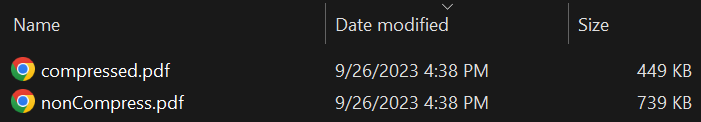
using IronPdf;ChromePdfRenderer renderer = new ChromePdfRenderer();PdfDocument pdf = renderer.RenderUrlAsPdf("https://en.wikipedia.org/wiki/Main_Page");// Quality 40 re-encodes every embedded image as a low-quality JPEG, which is// where most of the file-size saving comes from in image-heavy PDFspdf.CompressAndSaveAs("compressed.pdf", 40);
using IronPdf;

ChromePdfRenderer renderer = new ChromePdfRenderer();

PdfDocument pdf = renderer.RenderUrlAsPdf("https://en.wikipedia.org/wiki/Main_Page");

// Quality 40 re-encodes every embedded image as a low-quality JPEG, which is
// where most of the file-size saving comes from in image-heavy PDFs
pdf.CompressAndSaveAs("compressed.pdf", 40);
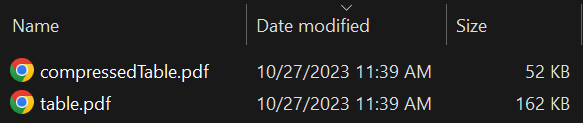
using IronPdf;PdfDocument pdf = PdfDocument.FromFile("table.pdf");// Pass null quality to skip image compression and true to drop the structure// tree, which is the bulk of the size in table-heavy Chrome-rendered PDFspdf.CompressAndSaveAs("compressedTable.pdf", null, true);
using IronPdf;

PdfDocument pdf = PdfDocument.FromFile("table.pdf");

// Pass null quality to skip image compression and true to drop the structure
// tree, which is the bulk of the size in table-heavy Chrome-rendered PDFs
pdf.CompressAndSaveAs("compressedTable.pdf", null, true);
C#
树形结构压缩可以减少多少文件大小?
减少了67.90%。 该数字随着表格PDF的增长而上升。
我最喜欢的这种库是 IronPDF。它允许快速高效地操作 PDF 文件。它还具有许多有价值的功能,比如导出为 PDF/A 格式和数字签名 PDF 文档。
using IronPdf;PdfDocument pdf = PdfDocument.FromFile("sample.pdf");// Shrink both sources of bloat in one pass: re-encode images at quality 80// and strip the structure tree (true) for the largest size reductionpdf.CompressAndSaveAs("compressed.pdf", 80, true);
using IronPdf;

PdfDocument pdf = PdfDocument.FromFile("sample.pdf");

// Shrink both sources of bloat in one pass: re-encode images at quality 80
// and strip the structure tree (true) for the largest size reduction
pdf.CompressAndSaveAs("compressed.pdf", 80, true);
using IronPdf;var pdf = PdfDocument.FromFile("input.pdf");// Web or email: strong size reductionpdf.CompressAndSaveAs("compressed.pdf", new AdvancedCompressionOptions{JpegQuality = 70,TargetImageDpi = 150,RemoveStructureTree = true});// Print quality: minimal quality losspdf.CompressAndSaveAs("print.pdf", new AdvancedCompressionOptions{JpegQuality = 90,TargetImageDpi = 300});
using IronPdf;

var pdf = PdfDocument.FromFile("input.pdf");

// Web or email: strong size reduction
pdf.CompressAndSaveAs("compressed.pdf", new AdvancedCompressionOptions
{
    JpegQuality = 70,
    TargetImageDpi = 150,
    RemoveStructureTree = true
});

// Print quality: minimal quality loss
pdf.CompressAndSaveAs("print.pdf", new AdvancedCompressionOptions
{
    JpegQuality = 90,
    TargetImageDpi = 300
});
using IronPdf;PdfDocument pdf = PdfDocument.FromFile("sample.pdf");// Return the compressed PDF as bytes so it can go straight into an HTTP// response, a database varbinary column, or a queue message with no temp filebyte[] compressedBytes = pdf.CompressPdfToBytes();File.WriteAllBytes("compressed.pdf", compressedBytes);
using IronPdf;

PdfDocument pdf = PdfDocument.FromFile("sample.pdf");

// Return the compressed PDF as bytes so it can go straight into an HTTP
// response, a database varbinary column, or a queue message with no temp file
byte[] compressedBytes = pdf.CompressPdfToBytes();

File.WriteAllBytes("compressed.pdf", compressedBytes);
using IronPdf;using System.IO;PdfDocument pdf = PdfDocument.FromFile("sample.pdf");// Stream output so the compressed bytes can be piped straight to an HTTP// response or cloud upload without first buffering the whole file as byte[]using Stream compressedStream = pdf.CompressPdfToStream();// CompressPdfToStream returns a read-only Stream, so copy it to the destinationusing FileStream fileStream = File.Create("compressed.pdf");compressedStream.CopyTo(fileStream);
using IronPdf;
using System.IO;

PdfDocument pdf = PdfDocument.FromFile("sample.pdf");

// Stream output so the compressed bytes can be piped straight to an HTTP
// response or cloud upload without first buffering the whole file as byte[]
using Stream compressedStream = pdf.CompressPdfToStream();

// CompressPdfToStream returns a read-only Stream, so copy it to the destination
using FileStream fileStream = File.Create("compressed.pdf");
compressedStream.CopyTo(fileStream);
using IronPdf;PdfDocument pdf = PdfDocument.FromFile("sample.pdf");// HighQuality resamples images using the system temp directory, so it produces// the smallest output but needs write access to that directory at runtimebyte[] compressedBytes = pdf.CompressPdfToBytes(50, false, CompressionMode.HighQuality);File.WriteAllBytes("compressed.pdf", compressedBytes);
using IronPdf;

PdfDocument pdf = PdfDocument.FromFile("sample.pdf");

// HighQuality resamples images using the system temp directory, so it produces
// the smallest output but needs write access to that directory at runtime
byte[] compressedBytes = pdf.CompressPdfToBytes(50, false, CompressionMode.HighQuality);

File.WriteAllBytes("compressed.pdf", compressedBytes);
How can I achieve fine-grained control over PDF compression in IronPDF?
For fine-grained control, IronPDF allows you to pass an `AdvancedCompressionOptions` object to the `CompressAndSaveAs` method, letting you adjust JPEG quality, image DPI downsampling, and zlib compression levels.