
How to Compress PDFs in C# using IronPDF

IronPDF compresses PDFs in C# through the CompressAndSaveAs method, which re-encodes embedded images and optionally strips the PDF structure tree to cut file size in a single call. Images are re-encoded as JPEG by default, or as 1-bit CCITT Group 4 when you opt in. The companion CompressPdfToBytes and CompressPdfToStream methods compress in memory instead.
Images usually account for most of a PDF's size, and table-heavy documents carry a structure tree that adds further weight. IronPDF targets both, so the same call works on PDFs loaded from disk or held in a memory stream.
Quickstart: Compress PDF Files with IronPDFLoad your PDF with PdfDocument.FromFile and call CompressAndSaveAs to re-encode its images and write the slimmed-down copy in one step. The second argument is the JPEG quality.
-
1Install IronPDF with NuGet Package Manager
-
2Copy and run this code snippet.
PdfDocument.FromFile("input.pdf").CompressAndSaveAs("compressed.pdf", 40);PdfDocument.FromFile("input.pdf").CompressAndSaveAs("compressed.pdf", 40)PdfDocument.FromFile("input.pdf").CompressAndSaveAs("compressed.pdf", 40) -
3Deploy to test on your live environment
Start using IronPDF in your project today with a free trial
Minimal Workflow (3 steps)
- Download the C# library for PDF compression from NuGet
- Import an existing PDF or render a new PDF
- Call
CompressAndSaveAs(outputPath, quality, removeStructureTree)to compress images, optionally strip the structure tree, and save the result
CompressImages, CompressStructTree, and Compress(CompressionOptions) are deprecated.How Do I Compress Images in PDFs?
Pass a JPEG quality value as the second argument to CompressAndSaveAs and IronPDF re-encodes every embedded image at that quality. Values run from 0 (maximum compression) to 100 (minimal loss), and the underlying engine decides how each value maps to the output. This is the method to reach for whenever a document carries embedded images.
As a rough guide:
- 90 and above: high quality
- 80 to 90: medium quality
- 70 to 80: low quality
A lower number squeezes harder but can introduce visible artifacts, and how much clarity drops depends on the source image, so test a few settings against your own content to find the balance you want.
Input
using IronPdf;

ChromePdfRenderer renderer = new ChromePdfRenderer();

PdfDocument pdf = renderer.RenderUrlAsPdf("https://en.wikipedia.org/wiki/Main_Page");

// Quality 40 re-encodes every embedded image as a low-quality JPEG, which is
// where most of the file-size saving comes from in image-heavy PDFs
pdf.CompressAndSaveAs("compressed.pdf", 40);
using IronPdf;
ChromePdfRenderer renderer = new ChromePdfRenderer();
PdfDocument pdf = renderer.RenderUrlAsPdf("https://en.wikipedia.org/wiki/Main_Page");
// Quality 40 re-encodes every embedded image as a low-quality JPEG, which is
// where most of the file-size saving comes from in image-heavy PDFs
pdf.CompressAndSaveAs("compressed.pdf", 40);Dim renderer As New ChromePdfRenderer()
Dim pdf As PdfDocument = renderer.RenderUrlAsPdf("https://en.wikipedia.org/wiki/Main_Page")
' Quality 40 re-encodes every embedded image as a low-quality JPEG, which is
' where most of the file-size saving comes from in image-heavy PDFs
pdf.CompressAndSaveAs("compressed.pdf", 40)Dim renderer As New ChromePdfRenderer()
Dim pdf As PdfDocument = renderer.RenderUrlAsPdf("https://en.wikipedia.org/wiki/Main_Page")
' Quality 40 re-encodes every embedded image as a low-quality JPEG, which is
' where most of the file-size saving comes from in image-heavy PDFs
pdf.CompressAndSaveAs("compressed.pdf", 40)Output
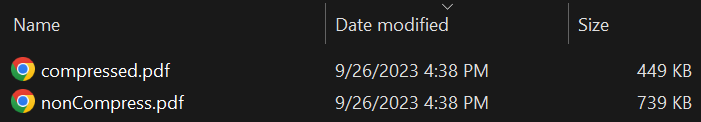
What Results Can I Expect from Image Compression?
Reduced by 39.24% on a Wikipedia render.
How Do I Compress PDF Tree Structure?
Pass removeStructureTree: true as the third argument to CompressAndSaveAs to strip the tree structure the Chrome Engine writes into a PDF. The saving is largest on Chrome Engine PDFs that hold extensive table data. Some rendering engines emit no such structure, which leaves nothing for the feature to remove.
Stripping the tree can weaken text highlighting and selection, so weigh that against the size gain if readers later need to extract text and images from the result.
Test CompressAndSaveAs with tree structure removal using this PDF with table data.
using IronPdf;

PdfDocument pdf = PdfDocument.FromFile("table.pdf");

// Pass null quality to skip image compression and true to drop the structure
// tree, which is the bulk of the size in table-heavy Chrome-rendered PDFs
pdf.CompressAndSaveAs("compressedTable.pdf", null, true);
using IronPdf;
PdfDocument pdf = PdfDocument.FromFile("table.pdf");
// Pass null quality to skip image compression and true to drop the structure
// tree, which is the bulk of the size in table-heavy Chrome-rendered PDFs
pdf.CompressAndSaveAs("compressedTable.pdf", null, true);Imports IronPdf
Dim pdf As PdfDocument = PdfDocument.FromFile("table.pdf")
' Pass nothing as quality to skip image compression and True to drop the structure
' tree, which is the bulk of the size in table-heavy Chrome-rendered PDFs
pdf.CompressAndSaveAs("compressedTable.pdf", Nothing, True)Imports IronPdf
Dim pdf As PdfDocument = PdfDocument.FromFile("table.pdf")
' Pass nothing as quality to skip image compression and True to drop the structure
' tree, which is the bulk of the size in table-heavy Chrome-rendered PDFs
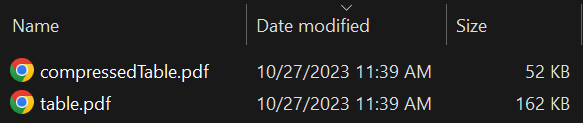
pdf.CompressAndSaveAs("compressedTable.pdf", Nothing, True)What File Size Reduction Can Tree Structure Compression Achieve?
Reduced by 67.90%. The figure climbs as the table PDF grows.
How Can I Apply Both Compression Methods Together?
Supply a quality value and set removeStructureTree to true in the same CompressAndSaveAs call to shrink both sources of bloat at once. This pairing earns its keep on documents that mix images with structured data, such as reports with charts or invoices with embedded tables.
using IronPdf;

PdfDocument pdf = PdfDocument.FromFile("sample.pdf");

// Shrink both sources of bloat in one pass: re-encode images at quality 80
// and strip the structure tree (true) for the largest size reduction
pdf.CompressAndSaveAs("compressed.pdf", 80, true);
using IronPdf;
PdfDocument pdf = PdfDocument.FromFile("sample.pdf");
// Shrink both sources of bloat in one pass: re-encode images at quality 80
// and strip the structure tree (true) for the largest size reduction
pdf.CompressAndSaveAs("compressed.pdf", 80, true);Imports IronPdf
Dim pdf As PdfDocument = PdfDocument.FromFile("sample.pdf")
' Shrink both sources of bloat in one pass: re-encode images at quality 80
' and strip the structure tree (true) for the largest size reduction
pdf.CompressAndSaveAs("compressed.pdf", 80, True)Imports IronPdf
Dim pdf As PdfDocument = PdfDocument.FromFile("sample.pdf")
' Shrink both sources of bloat in one pass: re-encode images at quality 80
' and strip the structure tree (true) for the largest size reduction
pdf.CompressAndSaveAs("compressed.pdf", 80, True)What Parameters Does CompressAndSaveAs Accept?
outputPath(string): the file path where the compressed PDF is written.quality(int?, 0 to 100): JPEG quality applied to every embedded image. Lower values produce smaller files. Passnullto skip image compression entirely.removeStructureTree(bool, defaultfalse): whentrue, strips the PDF structure tree to reduce file size further. Most effective for HTML-generated PDFs with tables.
Let the use case set the dial. Archival copies often favor quality over size, while web distribution rewards the smaller file. The same trade-off applies when you compress PDF/A compliant documents, where image fidelity may be the priority.

My favorite library of this kind is IronPDF. It allows for fast and efficient manipulation of PDF files. It also has many valuable features, like exporting to PDF/A format and digitally signing PDF documents.

IronOCR means we can save $40,000 annually from manual processing, while enhancing productivity and freeing up resources for high-impact tasks. I would highly recommend it.

How Do I Get Fine-Grained Control Over Compression?
For most documents the two-argument call is enough, but image-heavy archives and strict size budgets sometimes need more control. Pass an AdvancedCompressionOptions object to CompressAndSaveAs to tune the compression pipeline, including image DPI downsampling, JPEG re-encoding quality, bitonal encoding for black-and-white scans, and the zlib compression level. The simpler CompressAndSaveAs(outputPath, quality, removeStructureTree) overload still works unchanged and produces the same output as before.
using IronPdf;

PdfDocument pdf = PdfDocument.FromFile("input.pdf");

// Web or email: strong size reduction
pdf.CompressAndSaveAs("compressed.pdf", new AdvancedCompressionOptions
{
    JpegQuality = 70,
    TargetImageDpi = 150,
    RemoveStructureTree = true
});

// Print quality: minimal quality loss
pdf.CompressAndSaveAs("print.pdf", new AdvancedCompressionOptions
{
    JpegQuality = 90,
    TargetImageDpi = 300
});
using IronPdf;
PdfDocument pdf = PdfDocument.FromFile("input.pdf");
// Web or email: strong size reduction
pdf.CompressAndSaveAs("compressed.pdf", new AdvancedCompressionOptions
{
JpegQuality = 70,
TargetImageDpi = 150,
RemoveStructureTree = true
});
// Print quality: minimal quality loss
pdf.CompressAndSaveAs("print.pdf", new AdvancedCompressionOptions
{
JpegQuality = 90,
TargetImageDpi = 300
});Imports IronPdf
Dim pdf As PdfDocument = PdfDocument.FromFile("input.pdf")
' Web or email: strong size reduction
pdf.CompressAndSaveAs("compressed.pdf", New AdvancedCompressionOptions With {
.JpegQuality = 70,
.TargetImageDpi = 150,
.RemoveStructureTree = True
})
' Print quality: minimal quality loss
pdf.CompressAndSaveAs("print.pdf", New AdvancedCompressionOptions With {
.JpegQuality = 90,
.TargetImageDpi = 300
})Imports IronPdf
Dim pdf As PdfDocument = PdfDocument.FromFile("input.pdf")
' Web or email: strong size reduction
pdf.CompressAndSaveAs("compressed.pdf", New AdvancedCompressionOptions With {
.JpegQuality = 70,
.TargetImageDpi = 150,
.RemoveStructureTree = True
})
' Print quality: minimal quality loss
pdf.CompressAndSaveAs("print.pdf", New AdvancedCompressionOptions With {
.JpegQuality = 90,
.TargetImageDpi = 300
})The two properties that move the needle most on colour and mixed documents are JpegQuality and TargetImageDpi:
JpegQuality(int?, 1 to 100, defaultnull): re-encodes images at this JPEG quality. Leave itnullto skip image re-encoding entirely.TargetImageDpi(int?, default150): downsamples images whose effective DPI exceeds this value before re-encoding. Set it tonullor0to disable downsampling and keep the original resolution.
Recommended JpegQuality values (applies only when set):
| Value | Use case |
|---|---|
null (default) | No image re-encoding |
95 | Archival, minimal artifacts |
85 | High quality |
70 | Balanced, good for general use |
50 | Web or email, smaller files with visible artifacts |
Recommended TargetImageDpi values (lossy):
| Value | Use case |
|---|---|
300 | Print quality, lossless to the eye at normal viewing distance |
200 | Crisp on high-DPI and retina screens |
150 (default) | Best size and quality balance for screen and email |
96 | Aggressive, soft text but still readable |
null or 0 | Disabled, preserves the original resolution |
TargetImageDpi downsampling is lossy: once an image is downsampled, its original resolution cannot be restored. Decide up front whether you want resolution reduction or quality-only re-encoding, and set TargetImageDpi accordingly.How Do I Compress Black-and-White Scans?
IronPDF 2026.10.1+ introduces bitonal compression: AdvancedCompressionOptions can re-encode scanned text, faxes and line art as 1-bit CCITT Group 4 instead of JPEG.
using IronPdf;

PdfDocument pdf = PdfDocument.FromFile("scanned-document.pdf");

// Scanned text and line art: 1-bit CCITT Group 4
pdf.CompressAndSaveAs("scan-compressed.pdf", new AdvancedCompressionOptions
{
    BitonalMode = BitonalCompressionMode.Force
});

// Print-quality scan: threshold at 300 DPI instead of the 150 DPI fallback
pdf.CompressAndSaveAs("scan-300dpi.pdf", new AdvancedCompressionOptions
{
    BitonalMode = BitonalCompressionMode.Force,
    BitonalResolutionDpi = 300
});| Property | Type | Default | Purpose |
|---|---|---|---|
BitonalMode | BitonalCompressionMode | Off | Force converts every eligible image to 1-bit CCITT Group 4. Off leaves the JPEG pipeline in charge. |
BitonalResolutionDpi | int? | null | Target DPI before thresholding. null or 0 falls back to TargetImageDpi. |
BitonalThreshold | int? | null | Luminance cutoff from 1 to 255. null computes one per image with Otsu's method. |
TargetImageDpi defaults to 150, so BitonalMode = Force on its own downsamples a 300 DPI scan to 150 DPI before thresholding. Set BitonalResolutionDpi to the scan's DPI, or TargetImageDpi to null, to keep the original resolution.Leave BitonalThreshold at null unless you need a fixed cutoff: the automatic threshold suits a batch of scans that vary in exposure. 0 and values outside 1 to 255 fall back to the automatic threshold instead of throwing.
When Should I Leave Bitonal Compression Off?
Thresholding turns every pixel black or white: colour and continuous-tone detail are discarded. Leave BitonalMode at Off for colour and photographic PDFs.
Three cases are skipped rather than converted:
- The bitonal result is not smaller: that image stays on the JPEG path. The decision is made per image
- The image carries a mask: a soft mask, or a stencil or colour-key mask, keeps its JPEG encoding. The mask is neither dropped nor flattened
- The image is already 1-bit: an existing CCITT or JBIG2 scan is left untouched whether or not bitonal compression is on, and
TargetImageDpidoes not downsample it
AdvancedCompressionOptions, which only the CompressAndSaveAs overloads accept. The in-memory methods cannot produce CCITT Group 4 output.How Do I Compress PDFs Without Saving to Disk?
API responses, cloud functions, and email attachments rarely need a compressed PDF on disk. CompressPdfToBytes returns the result as a byte array, so you decide where the bytes go next.
using IronPdf;

PdfDocument pdf = PdfDocument.FromFile("sample.pdf");

// Return the compressed PDF as bytes so it can go straight into an HTTP
// response, a database varbinary column, or a queue message with no temp file
byte[] compressedBytes = pdf.CompressPdfToBytes();

File.WriteAllBytes("compressed.pdf", compressedBytes);
using IronPdf;
PdfDocument pdf = PdfDocument.FromFile("sample.pdf");
// Return the compressed PDF as bytes so it can go straight into an HTTP
// response, a database varbinary column, or a queue message with no temp file
byte[] compressedBytes = pdf.CompressPdfToBytes();
File.WriteAllBytes("compressed.pdf", compressedBytes);Imports IronPdf
Dim pdf As PdfDocument = PdfDocument.FromFile("sample.pdf")
' Return the compressed PDF as bytes so it can go straight into an HTTP
' response, a database varbinary column, or a queue message with no temp file
Dim compressedBytes As Byte() = pdf.CompressPdfToBytes()
File.WriteAllBytes("compressed.pdf", compressedBytes)Imports IronPdf
Dim pdf As PdfDocument = PdfDocument.FromFile("sample.pdf")
' Return the compressed PDF as bytes so it can go straight into an HTTP
' response, a database varbinary column, or a queue message with no temp file
Dim compressedBytes As Byte() = pdf.CompressPdfToBytes()
File.WriteAllBytes("compressed.pdf", compressedBytes)If you need a Stream rather than a byte array, call CompressPdfToStream and copy it to your destination. This suits piping output to an HTTP response body, a cloud storage upload, or any stream-based workflow.
using IronPdf;
using System.IO;

PdfDocument pdf = PdfDocument.FromFile("sample.pdf");

// Stream output so the compressed bytes can be piped straight to an HTTP
// response or cloud upload without first buffering the whole file as byte[]
using Stream compressedStream = pdf.CompressPdfToStream();

// CompressPdfToStream returns a read-only Stream, so copy it to the destination
using FileStream fileStream = File.Create("compressed.pdf");
compressedStream.CopyTo(fileStream);
using IronPdf;
using System.IO;
PdfDocument pdf = PdfDocument.FromFile("sample.pdf");
// Stream output so the compressed bytes can be piped straight to an HTTP
// response or cloud upload without first buffering the whole file as byte[]
using Stream compressedStream = pdf.CompressPdfToStream();
// CompressPdfToStream returns a read-only Stream, so copy it to the destination
using FileStream fileStream = File.Create("compressed.pdf");
compressedStream.CopyTo(fileStream);Imports IronPdf
Imports System.IO
Dim pdf As PdfDocument = PdfDocument.FromFile("sample.pdf")
' Stream output so the compressed bytes can be piped straight to an HTTP
' response or cloud upload without first buffering the whole file as byte[]
Using compressedStream As Stream = pdf.CompressPdfToStream()
' CompressPdfToStream returns a read-only Stream, so copy it to the destination
Using fileStream As FileStream = File.Create("compressed.pdf")
compressedStream.CopyTo(fileStream)
End Using
End UsingImports IronPdf
Imports System.IO
Dim pdf As PdfDocument = PdfDocument.FromFile("sample.pdf")
' Stream output so the compressed bytes can be piped straight to an HTTP
' response or cloud upload without first buffering the whole file as byte[]
Using compressedStream As Stream = pdf.CompressPdfToStream()
' CompressPdfToStream returns a read-only Stream, so copy it to the destination
Using fileStream As FileStream = File.Create("compressed.pdf")
compressedStream.CopyTo(fileStream)
End Using
End UsingWhat CompressionMode Options Are Available?
Both CompressPdfToBytes and CompressPdfToStream take an optional CompressionMode argument that decides how the work is done. Deployment targets differ in whether they allow disk access, and the mode lets you pick the right trade-off:
| Mode | Disk access | Image resampling | Output size |
|---|---|---|---|
Automatic (default) | Tries disk, falls back to memory | When disk is available | Smallest where permitted |
FastMemory | None | No | Larger |
HighQuality | Temp directory required | Yes | Smallest |
Automatic attempts HighQuality first and drops to FastMemory when the temporary directory is off limits. The example below forces HighQuality for the smallest output, which needs write access to the system temp directory at runtime.
using IronPdf;

PdfDocument pdf = PdfDocument.FromFile("sample.pdf");

// HighQuality resamples images using the system temp directory, so it produces
// the smallest output but needs write access to that directory at runtime
byte[] compressedBytes = pdf.CompressPdfToBytes(50, false, CompressionMode.HighQuality);

File.WriteAllBytes("compressed.pdf", compressedBytes);
using IronPdf;
PdfDocument pdf = PdfDocument.FromFile("sample.pdf");
// HighQuality resamples images using the system temp directory, so it produces
// the smallest output but needs write access to that directory at runtime
byte[] compressedBytes = pdf.CompressPdfToBytes(50, false, CompressionMode.HighQuality);
File.WriteAllBytes("compressed.pdf", compressedBytes);Imports IronPdf
Dim pdf As PdfDocument = PdfDocument.FromFile("sample.pdf")
' HighQuality resamples images using the system temp directory, so it produces
' the smallest output but needs write access to that directory at runtime
Dim compressedBytes As Byte() = pdf.CompressPdfToBytes(50, False, CompressionMode.HighQuality)
File.WriteAllBytes("compressed.pdf", compressedBytes)Imports IronPdf
Dim pdf As PdfDocument = PdfDocument.FromFile("sample.pdf")
' HighQuality resamples images using the system temp directory, so it produces
' the smallest output but needs write access to that directory at runtime
Dim compressedBytes As Byte() = pdf.CompressPdfToBytes(50, False, CompressionMode.HighQuality)
File.WriteAllBytes("compressed.pdf", compressedBytes)Output
CompressPdfToBytes and CompressPdfToStream are now available across all IronPDF platforms, including Java, Node.js, and Python.Conclusion
You now have one method, CompressAndSaveAs, that re-encodes images and strips the structure tree, plus CompressPdfToBytes and CompressPdfToStream for the same job in memory under a chosen CompressionMode. A natural next step is turning those slimmed-down pages into thumbnails with PDF rasterization.
Frequently Asked Questions
How can I compress PDFs using IronPDF in C#?
You can compress PDFs using IronPDF in C# through the CompressAndSaveAs method. This method re-encodes embedded images as JPEG and optionally strips the PDF structure tree to reduce the file size.
What methods does IronPDF offer for in-memory PDF compression?
IronPDF offers the CompressPdfToBytes and CompressPdfToStream methods for compressing PDFs in memory. These methods allow you to handle PDFs without needing to save them to disk.
How does IronPDF handle image compression in PDFs?
IronPDF compresses images in PDFs by re-encoding them as JPEG with a specified quality. You can pass a JPEG quality value to the CompressAndSaveAs method to adjust the level of compression.
What does the `removeStructureTree` parameter do in IronPDF?
The removeStructureTree parameter in IronPDF's CompressAndSaveAs method allows you to strip the PDF's structure tree, which can significantly reduce the file size, especially for table-heavy documents.
Can IronPDF compress PDFs without touching the disk?
Yes, IronPDF can compress PDFs without writing to disk by using the CompressPdfToBytes and CompressPdfToStream methods. These methods return the compressed PDF in a byte array or stream form, suitable for cloud or API workflows.
What is the impact of JPEG quality on PDF size in IronPDF?
In IronPDF, lower JPEG quality values result in smaller PDF sizes due to increased compression, but they may introduce visible artifacts. Testing different levels can help find the right balance between size and quality.
How can I use both image and structure tree compression together in IronPDF?
You can combine both image and structure tree compression in IronPDF by passing a JPEG quality and setting removeStructureTree to true in the CompressAndSaveAs call. This approach targets documents with both images and structured data.
How does `CompressionMode` affect PDF compression in IronPDF?
IronPDF's CompressionMode option allows you to adjust compression based on disk access and output size. It includes Automatic, FastMemory, and HighQuality modes, each offering different levels of disk usage and compression quality.
What file size reductions can I expect from using IronPDF?
File size reductions in IronPDF vary by content. For instance, compressing a Wikipedia render can reduce the size by about 39.24%, while stripping the structure tree in table-heavy PDFs can lead to a reduction of 67.90%.
How can I achieve fine-grained control over PDF compression in IronPDF?
For fine-grained control, IronPDF allows you to pass an AdvancedCompressionOptions object to the CompressAndSaveAs method, letting you adjust JPEG quality, image DPI downsampling, and zlib compression levels.
How do I compress black-and-white scans in IronPDF?
Set BitonalMode to BitonalCompressionMode.Force on an AdvancedCompressionOptions object and pass it to CompressAndSaveAs. IronPDF thresholds each eligible image to 1-bit and encodes it as CCITT Group 4, keeping the result only when it is smaller. It is off by default and is intended for scanned text, faxes and line art rather than colour or photographic content.
Why does my scan look softer after setting BitonalMode to Force?
BitonalResolutionDpi is null by default, which falls back to TargetImageDpi, and TargetImageDpi defaults to 150. Setting only BitonalMode therefore downsamples a 300 DPI scan to 150 DPI before thresholding it. Set BitonalResolutionDpi explicitly, or set TargetImageDpi to null, to threshold at the original resolution.
What does BitonalThreshold do in IronPDF?
BitonalThreshold is the luminance cutoff from 1 to 255 that decides whether a pixel becomes black or white. Leave it null, the default, and IronPDF computes a threshold per image using Otsu's method, which handles scans that vary in exposure. A value of 0, or anything outside 1 to 255, falls back to the automatic threshold.
Can I use bitonal compression with CompressPdfToBytes or CompressPdfToStream?
No. Bitonal compression is only available through the CompressAndSaveAs overloads that accept an AdvancedCompressionOptions object. CompressPdfToBytes and CompressPdfToStream take a JPEG quality value instead, so the in-memory paths cannot produce CCITT Group 4 output.

Curtis Chau holds a Bachelor’s degree in Computer Science (Carleton University) and specializes in front-end development with expertise in Node.js, TypeScript, JavaScript, and React. Passionate about crafting intuitive and aesthetically pleasing user interfaces, Curtis enjoys working with modern frameworks and creating well-structured, visually appealing manuals.



