
Extract Embedded Text and Images from PDFs in C#

Extract both text content and images from PDF documents in C# with simple method calls. Retrieve embedded content for editing, analysis, or repurposing in other applications.
Your business is spending too much on yearly subscriptions for PDF security and compliance. Consider IronSecureDoc, which provides solutions for managing SaaS services like digital signing, redaction, encryption, and protection, all for one-time payment. Explore IronSecureDoc Documentation
Text and image extraction retrieves textual content and graphical elements from PDF documents. Access and repurpose content for editing, searching, converting text to other formats, or saving images for reuse. Whether you need to parse PDFs in C# for data analysis, convert content to searchable formats, or extract visual elements for archiving, IronPDF provides comprehensive extraction tools.
Extract text and images using IronPDF. Save extracted images to disk or convert them to another format before embedding in new documents. This flexibility supports workflows requiring content transformation, such as converting PDFs to HTML or repurposing extracted images.
Quickstart: Extract Text and Images with IronPDFExtract text and images from PDFs in just a few lines of code. This quickstart demonstrates how to retrieve embedded content from PDF documents for content repurposing and analysis. Extract text for editing or save images for further use with IronPDF's efficient solution.
-
1Install IronPDF with NuGet Package Manager
-
2Copy and run this code snippet.
var pdf = new IronPdf.PdfDocument("sample.pdf"); string text = pdf.ExtractAllText(); var images = pdf.ExtractAllImages();C# -
3Deploy to test on your live environment
Start using IronPDF in your project today with a free trial
Minimal Workflow (5 steps)
- Download the
IronPdfC# Library - Prepare the PDF document for text and image extraction
- Use the
ExtractAllTextmethod to extract text - Use the
ExtractAllImagesmethod to extract images - Specify the particular pages from which to extract text and images
How Do I Extract Text from PDFs?
Extract text from both newly rendered and existing PDF documents. Use the ExtractAllText method to extract embedded text from the document. The method returns a string containing all text in the PDF. Pages are separated by four consecutive newline characters. This example uses a sample PDF rendered from the Wikipedia website.
When working with PDFs containing international languages and UTF-8 characters, IronPDF maintains proper encoding and character representation. This ensures correct display of non-Latin scripts and special characters.
Input
A sample invoice PDF.
using IronPdf;
using System.IO;

PdfDocument pdf = PdfDocument.FromFile("sample.pdf");

// Extract text
string text = pdf.ExtractAllText();

// Export the extracted text to a text file
File.WriteAllText("extractedText.txt", text);Imports IronPdf
Imports System.IO
Private pdf As PdfDocument = PdfDocument.FromFile("sample.pdf")
' Extract text
Private text As String = pdf.ExtractAllText()
' Export the extracted text to a text file
File.WriteAllText("extractedText.txt", text)Output
Running ExtractAllText returns the page text in reading order:
Invoice INV-2026-0042
Billed to: Northwind Traders
Date: 2026-02-14
Consulting $3,200.00
Support $800.00
Total: $4,000.00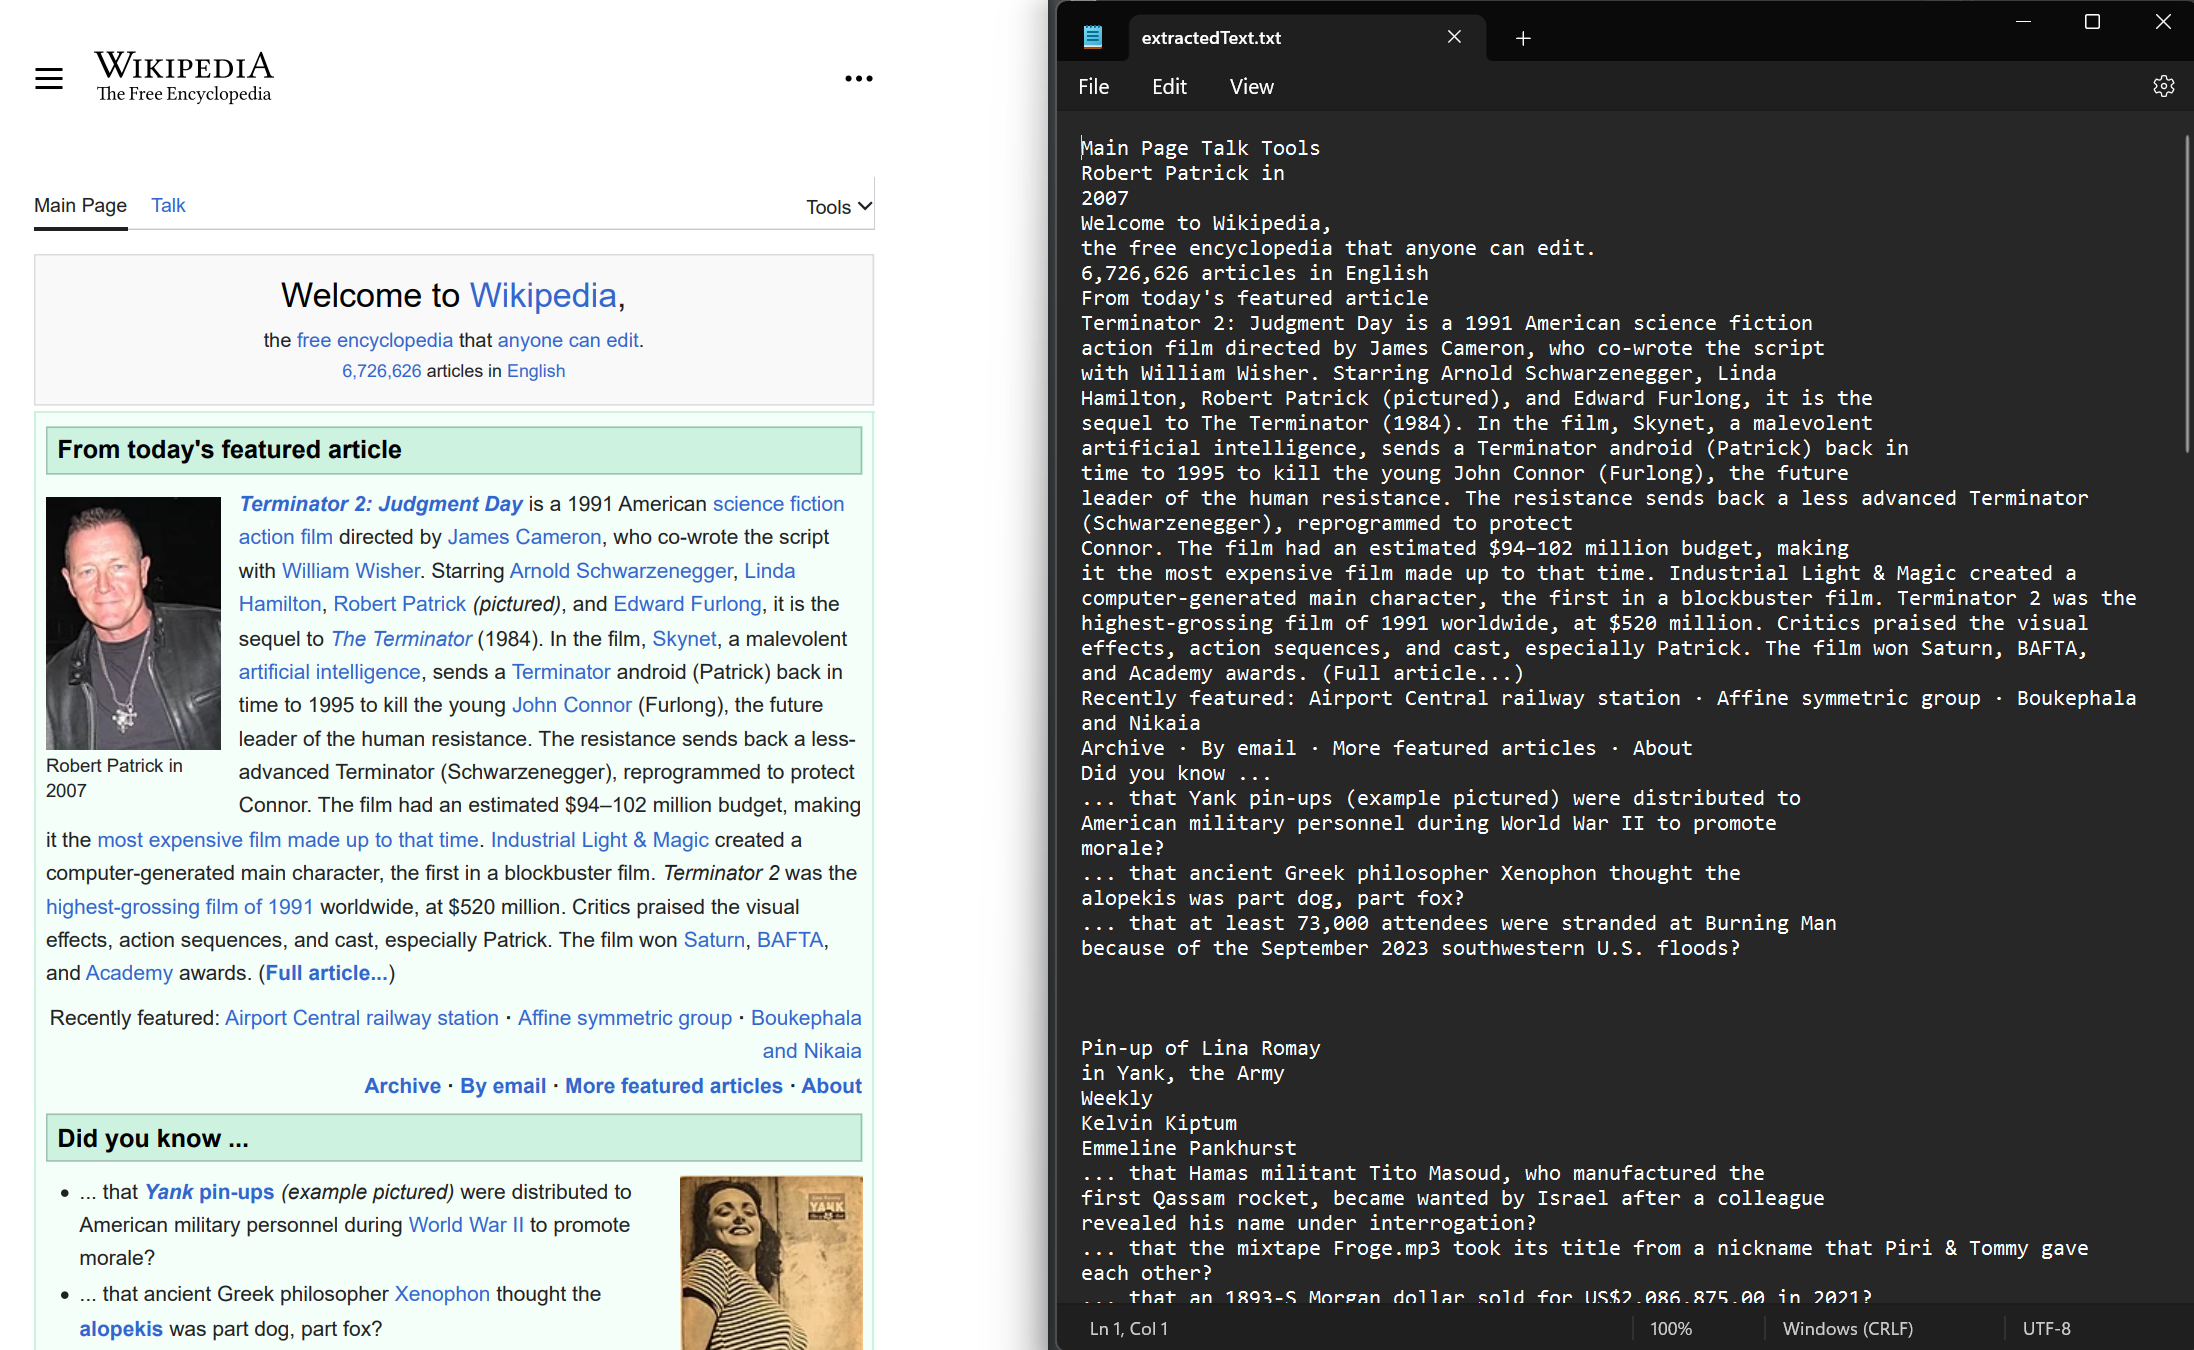
How Can I Extract Text with Precise Coordinates?
Retrieve the coordinates of text lines and characters within each PDF page. Select a page from the PDF and access the Lines and Characters properties. The coordinates include Top, Right, Bottom, and Left values representing text position. This feature preserves spatial layout and enables text position analysis.
For developers who need to read PDF files in C# with positional awareness, coordinate extraction provides data for maintaining document structure and implementing advanced text analysis.
using IronPdf;
using System.IO;
using System.Linq;

// Open PDF from file
PdfDocument pdf = PdfDocument.FromFile("sample.pdf");

// Extract text by lines
var lines = pdf.Pages[0].Lines;

// Extract text by characters
var characters = pdf.Pages[0].Characters;

File.WriteAllLines("lines.txt", lines.Select(l => $"at Y={l.BoundingBox.Bottom:F2}: {l.Contents}"));Imports IronPdf
Imports System.IO
Imports System.Linq
' Open PDF from file
Private pdf As PdfDocument = PdfDocument.FromFile("sample.pdf")
' Extract text by lines
Private lines = pdf.Pages(0).Lines
' Extract text by characters
Private characters = pdf.Pages(0).Characters
File.WriteAllLines("lines.txt", lines.Select(Function(l) $"at Y={l.BoundingBox.Bottom:F2}: {l.Contents}"))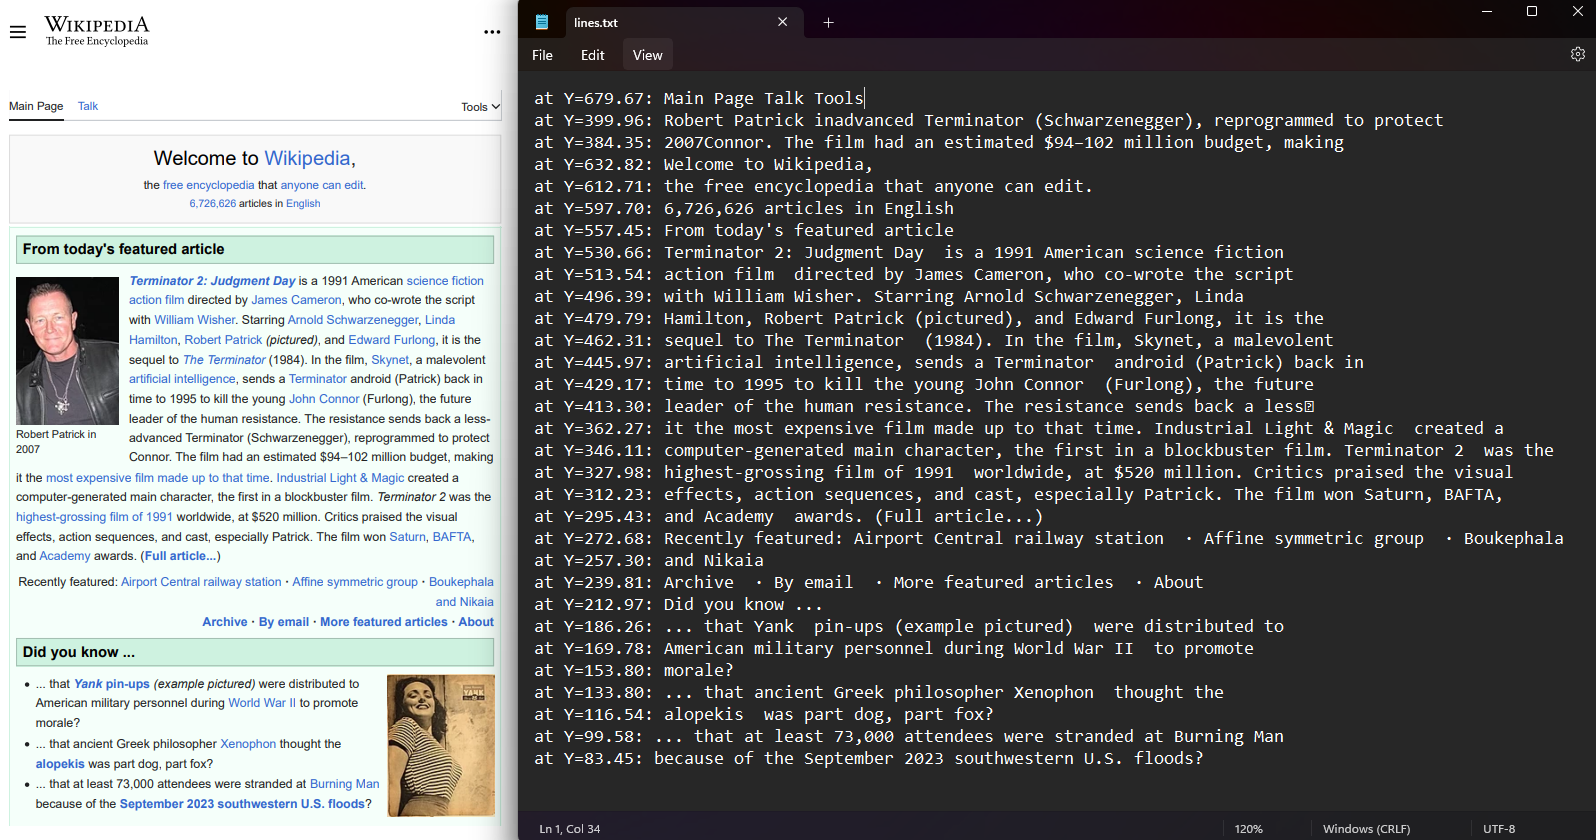
How Do I Extract Images from PDFs?
Use the ExtractAllImages method to extract all embedded images from the document. The method returns images as a list of List of AnyBitmap objects. Using the same document, we extracted images and exported them to the 'images' folder. This functionality supports image archiving, content migration, and rasterizing PDF pages to images for further processing.
Extracted images maintain original quality and can be saved in various formats including PNG, JPEG, and BMP. For cloud storage workflows, integrate this functionality with Azure Blob Storage for image management.
using IronPdf;

PdfDocument pdf = PdfDocument.FromFile("sample.pdf");

// Extract images
var images = pdf.ExtractAllImages();

for(int i = 0; i < images.Count; i++)
{
    // Export the extracted images
    images[i].SaveAs($"images/image{i}.png");
}Imports IronPdf
Private pdf As PdfDocument = PdfDocument.FromFile("sample.pdf")
' Extract images
Private images = pdf.ExtractAllImages()
For i As Integer = 0 To images.Count - 1
' Export the extracted images
images(i).SaveAs($"images/image{i}.png")
Next i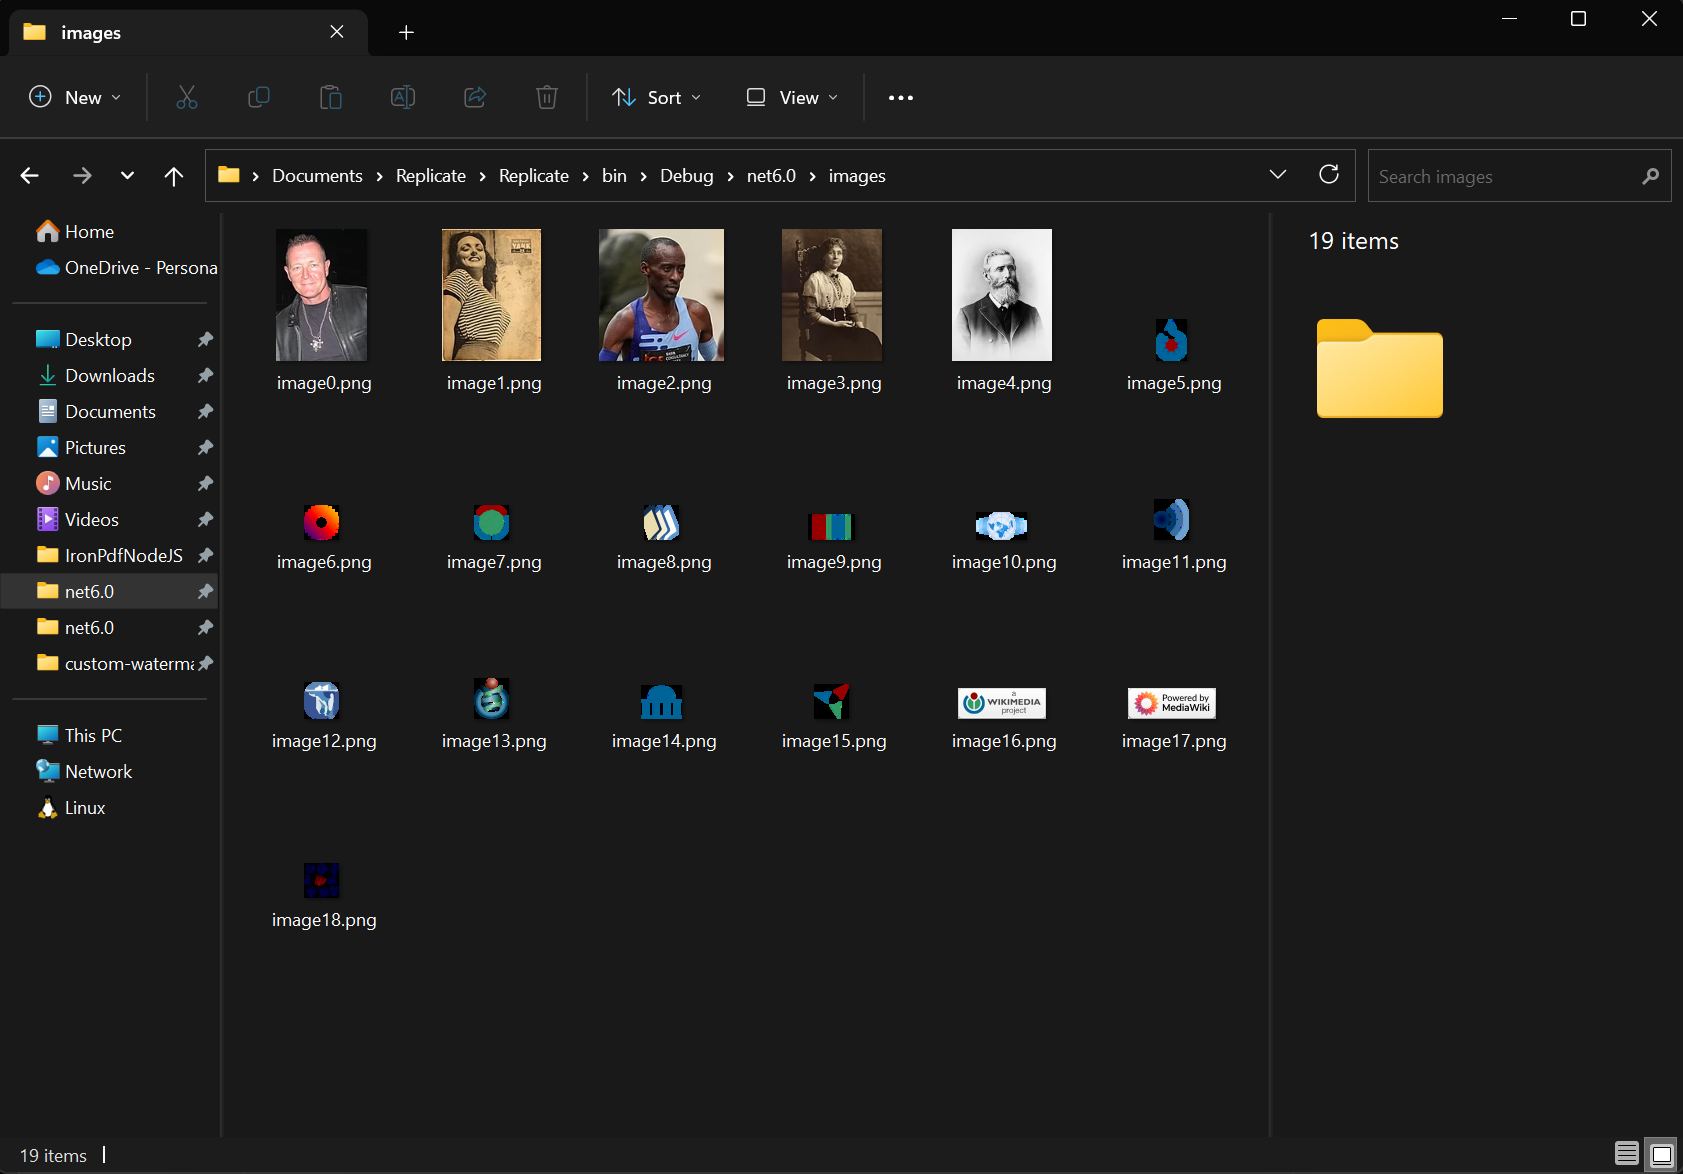
What Are the Different Methods for Image Extraction?
Beyond the ExtractAllImages method, use ExtractAllBitmaps and ExtractAllRawImages methods to extract image information. While ExtractAllBitmaps returns a List of AnyBitmap, ExtractAllRawImages extracts all images and returns them as raw byte[] (byte[]).
The ExtractAllRawImages method works well when processing image data in memory or integrating with systems requiring byte array inputs. For scenarios involving exporting PDFs to memory streams, the raw byte array format provides optimal flexibility.

My favorite library of this kind is IronPDF. It allows for fast and efficient manipulation of PDF files. It also has many valuable features, like exporting to PDF/A format and digitally signing PDF documents.

IronOCR means we can save $40,000 annually from manual processing, while enhancing productivity and freeing up resources for high-impact tasks. I would highly recommend it.

How Do I Extract Content from Specific PDF Pages?
Extract text and images from single or multiple specified pages. Use ExtractTextFromPage and ExtractTextFromPages methods for text extraction from one or multiple pages. For images, use ExtractImagesFromPage and ExtractImagesFromPages methods.
This granular control helps when working with large documents where only specific sections contain relevant content. It also supports features to split PDFs and extract individual pages for separate processing. ExtractImagesFromPage returns images in the same order that SetImageAltText addresses them, so it is also how you find the index of an image you want to describe for accessibility.
Input
A three-page sample PDF, each page holding distinct text.
using IronPdf;

PdfDocument pdf = PdfDocument.FromFile("sample.pdf");

// Extract text from page 1
string textFromPage1 = pdf.ExtractTextFromPage(0);

int[] pages = new[] { 0, 2 };

// Extract text from pages 1 & 3
string textFromPage1_3 = pdf.ExtractTextFromPages(pages);Imports IronPdf
Private pdf As PdfDocument = PdfDocument.FromFile("sample.pdf")
' Extract text from page 1
Private textFromPage1 As String = pdf.ExtractTextFromPage(0)
Private pages() As Integer = { 0, 2 }
' Extract text from pages 1 & 3
Private textFromPage1_3 As String = pdf.ExtractTextFromPages(pages)Output
ExtractTextFromPage(0) returns the text of page 1:
Page 1 - Executive Summary
Revenue rose 12 percent this quarter.ExtractTextFromPages(new[] { 0, 2 }) returns pages 1 and 3 combined:
Page 1 - Executive Summary
Revenue rose 12 percent this quarter.
Page 3 - Appendix
Regional breakdown and footnotes.When Should I Extract from Specific Pages Instead of All Pages?
Extract from specific pages when:
- Working with large PDFs containing relevant data in certain sections
- Implementing workflows that handle pages independently
- Building applications requiring incremental content display or processing
- Optimizing memory usage by processing only required pages
- Creating page-specific search or indexing functionality
What Performance Considerations Should I Know About?
Consider these performance factors when extracting PDF content:
- Memory Usage: Extract pages individually from large documents to minimize memory consumption
- Processing Time: Use parallel processing for multi-page extractions when appropriate
- File Size: Larger PDFs with high-resolution images require more processing time
- Storage: Plan adequate disk space for extracting numerous high-resolution images
- Threading: IronPDF supports multi-threaded operations for improved performance on multi-core systems
For optimal performance with in-memory PDFs, use memory stream operations to reduce disk I/O overhead.
How Do I Extract Text from a Specific Layer (OCG)?
Layered PDFs such as CAD drawings and map exports group their content into named layers, known as Optional Content Groups. When you only want the text from one of them (the disclaimer in a "Title Block" layer, or every label on a "Road - Major" layer), call ExtractTextFromLayer with the layer name or id. Pass several names to ExtractTextFromLayers to concatenate them in a single call. To reach the layer objects themselves, GetTextObjectsByLayer returns the TextObjects for a given layer.
using IronPdf;

// Load a layered PDF, for example a map export with named layers
using PdfDocument pdf = new PdfDocument("architect-plan.pdf");

// Extract the text of a single layer as one string, in reading order.
// Layer names are case-sensitive.
string titleBlock = pdf.ExtractTextFromLayer("Title Block");

// Combine the text of several layers in one call.
// Unknown names are skipped, so this never throws.
string roads = pdf.ExtractTextFromLayers(new[] { "Road - Major", "Road - Highway", "Labels" });"Title Block" and "title block" name different layers. Unknown names, bad ids, and empty inputs return an empty string instead of throwing, and a PDF with no layers simply yields no text. To browse the full layer tree first, see accessing PDF DOM objects.Frequently Asked Questions
How can I extract text from a PDF using C#?
You can extract text from a PDF in C# using the IronPDF library by calling the `ExtractAllText` method on a `PdfDocument` object. This method retrieves all embedded text from the document and returns it as a string.
What methods does IronPDF offer for extracting images from a PDF?
IronPDF provides several methods for image extraction, including `ExtractAllImages`, `ExtractAllBitmaps`, and `ExtractAllRawImages`. These methods allow you to extract images as `AnyBitmap` objects or raw byte arrays, depending on your needs.
Can I extract content from specific pages of a PDF with IronPDF?
Yes, IronPDF allows you to extract content from specific PDF pages using `ExtractTextFromPage`, `ExtractTextFromPages`, `ExtractImagesFromPage`, and `ExtractImagesFromPages` methods, giving you control over which portions of the document to process.
How does IronPDF handle text extraction with precise coordinates?
IronPDF can extract text with precise coordinates using the `Lines` and `Characters` properties of a page, which provide positional data including `Top`, `Right`, `Bottom`, and `Left` values, ideal for maintaining layout and performing text position analysis.
What are the performance considerations when extracting PDF content with IronPDF?
Performance considerations include memory usage, processing time, file size, storage requirements, and utilizing multi-threaded operations. Extracting content from specific pages and employing memory stream operations can optimize these aspects.
How can IronPDF assist with extracting text from PDFs containing international languages?
IronPDF maintains proper encoding and character representation for international languages and UTF-8 characters, ensuring correct text extraction and display for non-Latin scripts and special characters.
Is it possible to extract images from a PDF for use in Azure Blob Storage using IronPDF?
Yes, IronPDF's image extraction capabilities are compatible with Azure Blob Storage workflows, allowing you to save extracted images in various formats and manage them effectively in the cloud.
Does IronPDF support extracting text from specific layers within a PDF?
Yes, IronPDF can extract text from specific layers (OCGs) within a PDF using the `ExtractTextFromLayer` and `GetTextObjectsByLayer` methods, which target content grouped in named layers like CAD drawings or map exports.

Curtis Chau holds a Bachelor’s degree in Computer Science (Carleton University) and specializes in front-end development with expertise in Node.js, TypeScript, JavaScript, and React. Passionate about crafting intuitive and aesthetically pleasing user interfaces, Curtis enjoys working with modern frameworks and creating well-structured, visually appealing manuals.



