
C# PDF Parser

Parse PDF files in C# using IronPDF's ExtractAllText method to extract text from entire documents or specific pages. This approach provides simple, efficient PDF text extraction for .NET applications with just a few lines of code.
IronPDF makes PDF parsing straightforward in C# applications. This tutorial demonstrates how to use IronPDF, a comprehensive C# library for PDF generation and manipulation, to parse PDFs in just a few steps.
Quickstart: Efficient PDF Parsing with IronPDFStart parsing PDFs in C# using IronPDF with minimal code. This example shows how to extract all text from a PDF file while maintaining its original formatting. IronPDF's ExtractAllText method enables smooth PDF parsing integration into .NET applications. Follow these steps for straightforward setup and execution.
-
1Install IronPDF with NuGet Package Manager
-
2Copy and run this code snippet.
using IronPdf; var text = PdfDocument.FromFile("sample.pdf").ExtractAllText();C# -
3Deploy to test on your live environment
Start using IronPDF in your project today with a free trial
Minimal Workflow (5 steps)
- Download C# PDF parser library
- Install in your Visual Studio
- Use the
ExtractAllTextmethod to extract every single line of text - Extract all text from a single page with the
ExtractTextFromPagemethod - View parsed PDF content
How Do I Parse PDF Files in C#?
Parsing PDF files is simple with IronPDF. The code below uses the ExtractAllText method to extract every line of text from the entire PDF document. The comparison shows extracted PDF content alongside its output. The library also supports extracting text and images from specific sections of PDF documents.
Input
A sample invoice PDF.
using IronPdf;

// Select the desired PDF File
PdfDocument pdf = PdfDocument.FromFile("sample.pdf");

// Extract all text from an pdf
string allText = pdf.ExtractAllText();

// Extract all text from page 1
string page1Text = pdf.ExtractTextFromPage(0);Imports IronPdf
' Select the desired PDF File
Private pdf As PdfDocument = PdfDocument.FromFile("sample.pdf")
' Extract all text from an pdf
Private allText As String = pdf.ExtractAllText()
' Extract all text from page 1
Private page1Text As String = pdf.ExtractTextFromPage(0)Output
Running ExtractAllText returns the page text in reading order:
Invoice INV-2026-0042
Billed to: Northwind Traders
Date: 2026-02-14
Consulting $3,200.00
Support $800.00
Total: $4,000.00Advanced Text Extraction Examples
Here are additional ways to parse PDF content using IronPDF:
Input
A ten-page report document.
using IronPdf;

// Parse PDF from URL
var pdfFromUrl = PdfDocument.FromUrl("https://example.com/document.pdf");
string urlPdfText = pdfFromUrl.ExtractAllText();

// Parse password-protected PDFs
var protectedPdf = PdfDocument.FromFile("protected.pdf", "password123");
string protectedText = protectedPdf.ExtractAllText();

// Extract text from specific page range
var largePdf = PdfDocument.FromFile("large-document.pdf");
for (int i = 5; i < 10; i++)
{
    string pageText = largePdf.ExtractTextFromPage(i);
    Console.WriteLine($"Page {i + 1}: {pageText.Substring(0, 100)}...");
}Imports IronPdf
' Parse PDF from URL
Dim pdfFromUrl = PdfDocument.FromUrl("https://example.com/document.pdf")
Dim urlPdfText As String = pdfFromUrl.ExtractAllText()
' Parse password-protected PDFs
Dim protectedPdf = PdfDocument.FromFile("protected.pdf", "password123")
Dim protectedText As String = protectedPdf.ExtractAllText()
' Extract text from specific page range
Dim largePdf = PdfDocument.FromFile("large-document.pdf")
For i As Integer = 5 To 9
Dim pageText As String = largePdf.ExtractTextFromPage(i)
Console.WriteLine($"Page {i + 1}: {pageText.Substring(0, 100)}...")
NextOutput
The URL and password-protected lines need live inputs, but the page-range loop writes each extracted page to the console:

For complex parsing needs, explore PDF DOM object access to work with structured content.
Handling Different PDF Types
IronPDF excels at parsing various PDF types:
using IronPdf;
using System.Text.RegularExpressions;

// Parse scanned PDFs with OCR (requires IronOcr)
var scannedPdf = PdfDocument.FromFile("scanned-document.pdf");
string ocrText = scannedPdf.ExtractAllText();

// Parse PDFs with forms
var formPdf = PdfDocument.FromFile("form.pdf");
string formText = formPdf.ExtractAllText();

// Extract and filter specific content
string invoiceText = pdf.ExtractAllText();
var invoiceNumber = Regex.Match(invoiceText, @"Invoice #: (\d+)").Groups[1].Value;
var totalAmount = Regex.Match(invoiceText, @"Total: \$([0-9,]+\.\d{2})").Groups[1].Value;Imports IronPdf
Imports System.Text.RegularExpressions
' Parse scanned PDFs with OCR (requires IronOcr)
Dim scannedPdf = PdfDocument.FromFile("scanned-document.pdf")
Dim ocrText As String = scannedPdf.ExtractAllText()
' Parse PDFs with forms
Dim formPdf = PdfDocument.FromFile("form.pdf")
Dim formText As String = formPdf.ExtractAllText()
' Extract and filter specific content
Dim invoiceText As String = pdf.ExtractAllText()
Dim invoiceNumber = Regex.Match(invoiceText, "Invoice #: (\d+)").Groups(1).Value
Dim totalAmount = Regex.Match(invoiceText, "Total: \$([0-9,]+\.\d{2})").Groups(1).ValueLayered PDFs such as CAD drawings and map exports are a distinct type: their content is grouped into named Optional Content Groups (OCGs). Instead of parsing the whole document, you can scope extraction to one layer with ExtractTextFromLayer, or combine several with ExtractTextFromLayers. See extracting text from a specific layer for details.
How Do I View the Parsed PDF Content?
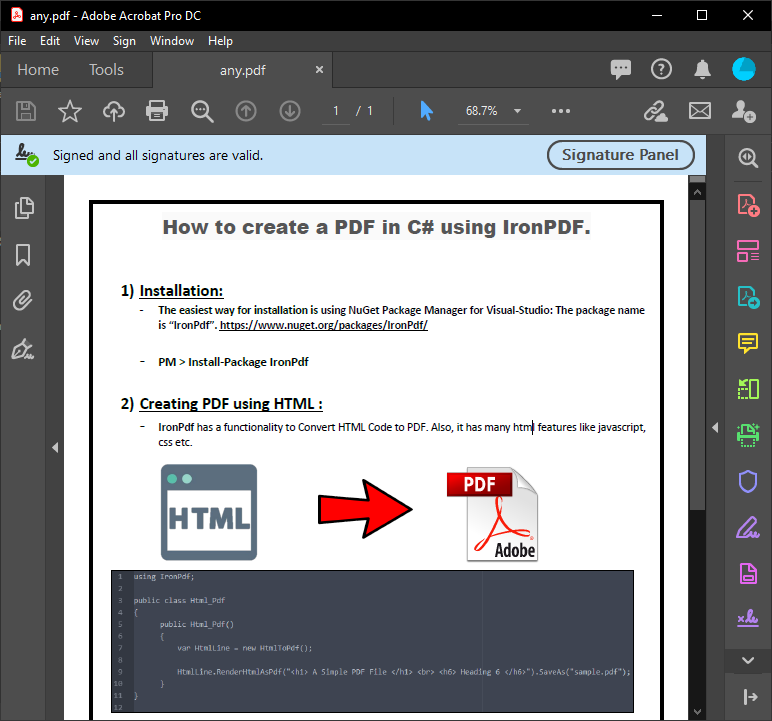
A C# Form displays the parsed PDF content from the code execution above. This output provides the exact text from a PDF for document processing needs.
~ PDF ~
~ C# Form ~
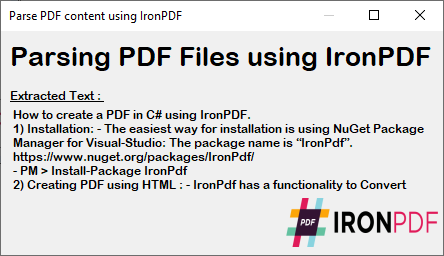
The extracted text maintains the original formatting and structure from the PDF, making it ideal for data processing, content analysis, or migration tasks. Process this text further by finding and replacing specific content or exporting it to other formats.
Integrating PDF Parsing into Your Applications
IronPDF's parsing capabilities integrate into various application types:
// ASP.NET Core example
public IActionResult ParseUploadedPdf(IFormFile pdfFile)
{
    using var stream = pdfFile.OpenReadStream();
    var pdf = PdfDocument.FromStream(stream);

    var extractedText = pdf.ExtractAllText();

    // Process or store the extracted text
    return Json(new {
        success = true,
        textLength = extractedText.Length,
        preview = extractedText.Substring(0, Math.Min(500, extractedText.Length))
    });
}

// Console application example
static void BatchParsePdfs(string folderPath)
{
    var pdfFiles = Directory.GetFiles(folderPath, "*.pdf");

    foreach (var file in pdfFiles)
    {
        var pdf = PdfDocument.FromFile(file);
        var text = pdf.ExtractAllText();

        // Save extracted text
        var textFile = Path.ChangeExtension(file, ".txt");
        File.WriteAllText(textFile, text);

        Console.WriteLine($"Parsed: {Path.GetFileName(file)} - {text.Length} characters");
    }
}' ASP.NET Core example
Public Function ParseUploadedPdf(pdfFile As IFormFile) As IActionResult
Using stream = pdfFile.OpenReadStream()
Dim pdf = PdfDocument.FromStream(stream)
Dim extractedText = pdf.ExtractAllText()
' Process or store the extracted text
Return Json(New With {
.success = True,
.textLength = extractedText.Length,
.preview = extractedText.Substring(0, Math.Min(500, extractedText.Length))
})
End Using
End Function
' Console application example
Shared Sub BatchParsePdfs(folderPath As String)
Dim pdfFiles = Directory.GetFiles(folderPath, "*.pdf")
For Each file In pdfFiles
Dim pdf = PdfDocument.FromFile(file)
Dim text = pdf.ExtractAllText()
' Save extracted text
Dim textFile = Path.ChangeExtension(file, ".txt")
File.WriteAllText(textFile, text)
Console.WriteLine($"Parsed: {Path.GetFileName(file)} - {text.Length} characters")
Next
End SubThese examples show PDF parsing incorporation into web applications and batch processing scenarios. For advanced implementations, explore async and multithreading techniques to improve performance when processing multiple PDFs.
Ready to see what else you can do? Check out our tutorial page here: Edit PDFs
Frequently Asked Questions
How can I extract text from a PDF using C#?
You can use IronPDF's `ExtractAllText` method to extract text from an entire PDF document or individual pages with ease, using only a few lines of C# code.
What method do I use for PDF parsing in IronPDF?
The `ExtractAllText` method in IronPDF allows you to extract text efficiently from PDF documents in a .NET application.
Can IronPDF handle extracting text from specific pages in a PDF?
Yes, IronPDF supports extracting text from specific pages with its `ExtractTextFromPage` method, making it versatile for targeted PDF text extractions.
Does IronPDF support extracting text from password-protected PDFs?
Yes, IronPDF allows you to extract text from password-protected PDFs by providing the correct password when opening the document.
Can IronPDF parse PDFs retrieved from URLs?
Yes. You can parse PDFs directly from URLs using IronPDF's `PdfDocument.FromUrl` method and then extract their text using `ExtractAllText`.
How does IronPDF handle text extraction from scanned documents?
If the PDF is a scanned document, IronPDF can utilize OCR capabilities (with IronOcr) to extract text from such image-based PDFs.
Is it possible to extract and filter specific content from PDFs using IronPDF?
Yes, IronPDF allows you to extract all text and utilize regular expressions or custom logic to filter and locate specific content, like invoice numbers or totals.
How can I integrate PDF parsing capabilities into a web application using IronPDF?
You can integrate IronPDF's parsing functionality into web applications, such as ASP.NET Core, by reading the PDF input stream and using `ExtractAllText` to process or display the extracted content.
What are some advanced text extraction features provided by IronPDF?
IronPDF offers advanced features like parsing text from specific page ranges, handling layered PDFs, and employing async or multithreading for performance enhancements.
Can IronPDF maintain the original PDF formatting when extracting text?
Yes, IronPDF is designed to preserve the original formatting and structure of the PDF when extracting text, making it suitable for document processing and analysis tasks.

Curtis Chau holds a Bachelor’s degree in Computer Science (Carleton University) and specializes in front-end development with expertise in Node.js, TypeScript, JavaScript, and React. Passionate about crafting intuitive and aesthetically pleasing user interfaces, Curtis enjoys working with modern frameworks and creating well-structured, visually appealing manuals.



