
C## PDF 解析器

使用IronPDF的ExtractAllText方法在C#中解析PDF文件,以从整个文档或特定页面中提取文本。 这种方法只需几行代码即可为 .NET 应用程序提供简单、高效的 PDF 文本提取功能。
IronPDF 使 PDF 解析在 C# 应用程序中变得简单明了。 本教程演示了如何使用 IronPDF - 一个用于 PDF 生成和操作的综合 C# 库 - 仅需几步即可解析 PDF。
快速入门:使用IronPDF高效解析 PDF开始使用 IronPDF 以最少的代码在 C# 中解析 PDF。 本示例展示了如何从 PDF 文件中提取所有文本,同时保持其原始格式。 IronPDF的ExtractAllText方法使无缝PDF解析集成到.NET应用程序中。 请按照以下步骤进行直接设置和执行。
-
1Install IronPDF with NuGet Package Manager
-
2复制并运行这段代码。
var text = IronPdf.FromFile("sample.pdf").ExtractAllText();C# -
3部署到您的生产环境中进行测试
通过免费试用立即在您的项目中开始使用IronPDF
最小工作流程(5 个步骤)
- 下载 C# PDF 解析器库。
- 在你的 Visual Studio 中安装
- 使用
ExtractAllText方法提取每一行文本 - 使用
ExtractTextFromPage方法从单个页面中提取所有文本 - 查看解析后的 PDF 内容
如何用 C# 解析 PDF 文件?
using IronPDF 解析 PDF 文件非常简单。 以下代码使用ExtractAllText方法从整个PDF文档中提取每一行文本。 对比显示了提取的 PDF 内容及其输出结果。 该库还支持从 PDF 文档的特定部分提取文本和图像。
using IronPdf;

// Select the desired PDF File
PdfDocument pdf = PdfDocument.FromFile("sample.pdf");

// Extract all text from an pdf
string allText = pdf.ExtractAllText();

// Extract all text from page 1
string page1Text = pdf.ExtractTextFromPage(0);Imports IronPdf
' Select the desired PDF File
Private pdf As PdfDocument = PdfDocument.FromFile("sample.pdf")
' Extract all text from an pdf
Private allText As String = pdf.ExtractAllText()
' Extract all text from page 1
Private page1Text As String = pdf.ExtractTextFromPage(0)IronPDF 简化了各种场景下的 PDF 解析。 无论是处理 HTML 到 PDF 的转换、从现有文档中提取内容,还是实现 高级 PDF 功能,该库都能提供全面的支持。
IronPDF 可与 Windows 应用程序无缝集成,并支持在 Linux 和 macOS 平台上部署。 该库还支持 Azure 部署,用于基于云的解决方案。
高级文本提取示例
以下是使用 IronPDF 解析 PDF 内容的其他方法:
using IronPdf;

// Parse PDF from URL
var pdfFromUrl = PdfDocument.FromUrl("https://example.com/document.pdf");
string urlPdfText = pdfFromUrl.ExtractAllText();

// Parse password-protected PDFs
var protectedPdf = PdfDocument.FromFile("protected.pdf", "password123");
string protectedText = protectedPdf.ExtractAllText();

// Extract text from specific page range
var largePdf = PdfDocument.FromFile("large-document.pdf");
for (int i = 5; i < 10; i++)
{
    string pageText = largePdf.ExtractTextFromPage(i);
    Console.WriteLine($"Page {i + 1}: {pageText.Substring(0, 100)}...");
}Imports IronPdf
' Parse PDF from URL
Dim pdfFromUrl = PdfDocument.FromUrl("https://example.com/document.pdf")
Dim urlPdfText As String = pdfFromUrl.ExtractAllText()
' Parse password-protected PDFs
Dim protectedPdf = PdfDocument.FromFile("protected.pdf", "password123")
Dim protectedText As String = protectedPdf.ExtractAllText()
' Extract text from specific page range
Dim largePdf = PdfDocument.FromFile("large-document.pdf")
For i As Integer = 5 To 9
Dim pageText As String = largePdf.ExtractTextFromPage(i)
Console.WriteLine($"Page {i + 1}: {pageText.Substring(0, 100)}...")
Next这些示例展示了 IronPDF 在处理不同 PDF 源和场景时的灵活性。 对于复杂的解析需求,请探索 IronPDF DOM 对象访问,以处理结构化内容。
处理不同的 PDF 类型
IronPDF 擅长解析各种 PDF 类型:
using IronPdf;
using System.Text.RegularExpressions;

// Parse scanned PDFs with OCR (requires IronOcr)
var scannedPdf = PdfDocument.FromFile("scanned-document.pdf");
string ocrText = scannedPdf.ExtractAllText();

// Parse PDFs with forms
var formPdf = PdfDocument.FromFile("form.pdf");
string formText = formPdf.ExtractAllText();

// Extract and filter specific content
string invoiceText = pdf.ExtractAllText();
var invoiceNumber = Regex.Match(invoiceText, @"Invoice #: (\d+)").Groups[1].Value;
var totalAmount = Regex.Match(invoiceText, @"Total: \$([0-9,]+\.\d{2})").Groups[1].Value;Imports IronPdf
Imports System.Text.RegularExpressions
' Parse scanned PDFs with OCR (requires IronOcr)
Dim scannedPdf = PdfDocument.FromFile("scanned-document.pdf")
Dim ocrText As String = scannedPdf.ExtractAllText()
' Parse PDFs with forms
Dim formPdf = PdfDocument.FromFile("form.pdf")
Dim formText As String = formPdf.ExtractAllText()
' Extract and filter specific content
Dim invoiceText As String = pdf.ExtractAllText()
Dim invoiceNumber = Regex.Match(invoiceText, "Invoice #: (\d+)").Groups(1).Value
Dim totalAmount = Regex.Match(invoiceText, "Total: \$([0-9,]+\.\d{2})").Groups(1).Value如何查看解析后的 PDF 内容?
C# 表单显示上述代码执行中解析的 PDF 内容。 该输出可提供 PDF 中的准确文本,以满足文档处理的需要。
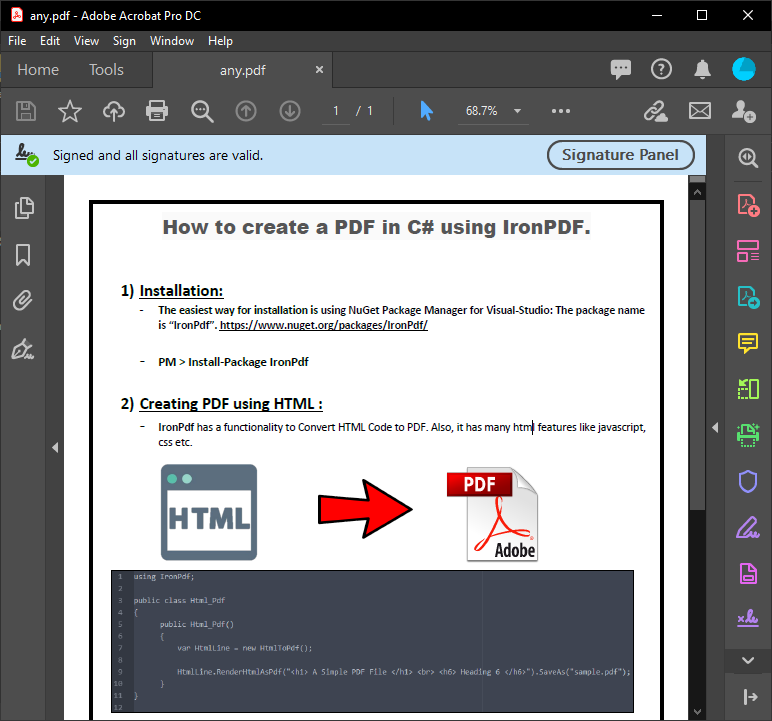
~ C# 表单
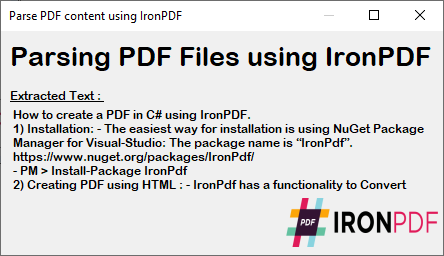
提取的文本保持了 PDF 的原始格式和结构,因此非常适合数据处理、内容分析或迁移任务。 通过查找和替换特定内容或导出为其他格式,对文本进行进一步处理。
将 PDF 解析集成到您的应用程序中
IronPDF 的解析功能可集成到各种应用类型中:
// ASP.NET Core example
public IActionResult ParseUploadedPdf(IFormFile pdfFile)
{
    using var stream = pdfFile.OpenReadStream();
    var pdf = PdfDocument.FromStream(stream);

    var extractedText = pdf.ExtractAllText();

    // Process or store the extracted text
    return Json(new {
        success = true,
        textLength = extractedText.Length,
        preview = extractedText.Substring(0, Math.Min(500, extractedText.Length))
    });
}

// Console application example
static void BatchParsePdfs(string folderPath)
{
    var pdfFiles = Directory.GetFiles(folderPath, "*.pdf");

    foreach (var file in pdfFiles)
    {
        var pdf = PdfDocument.FromFile(file);
        var text = pdf.ExtractAllText();

        // Save extracted text
        var textFile = Path.ChangeExtension(file, ".txt");
        File.WriteAllText(textFile, text);

        Console.WriteLine($"Parsed: {Path.GetFileName(file)} - {text.Length} characters");
    }
}' ASP.NET Core example
Public Function ParseUploadedPdf(pdfFile As IFormFile) As IActionResult
Using stream = pdfFile.OpenReadStream()
Dim pdf = PdfDocument.FromStream(stream)
Dim extractedText = pdf.ExtractAllText()
' Process or store the extracted text
Return Json(New With {
.success = True,
.textLength = extractedText.Length,
.preview = extractedText.Substring(0, Math.Min(500, extractedText.Length))
})
End Using
End Function
' Console application example
Shared Sub BatchParsePdfs(folderPath As String)
Dim pdfFiles = Directory.GetFiles(folderPath, "*.pdf")
For Each file In pdfFiles
Dim pdf = PdfDocument.FromFile(file)
Dim text = pdf.ExtractAllText()
' Save extracted text
Dim textFile = Path.ChangeExtension(file, ".txt")
File.WriteAllText(textFile, text)
Console.WriteLine($"Parsed: {Path.GetFileName(file)} - {text.Length} characters")
Next
End Sub这些示例展示了将 PDF 解析纳入网络应用程序和批处理场景的情况。 对于高级实现,请探索 async 和多线程技术,以提高处理多个 PDF 时的性能。
准备好看看您还能做些什么吗? 请查看我们的教程页面:编辑 PDF
常见问题解答
如何用 C# 从 PDF 文件中提取所有文本?
您可以使用 IronPDF 的 ExtractAllText 方法提取 PDF 文件中的所有文本。只需使用 IronPdf.FromFile("sample.pdf") 加载 PDF 文件,然后调用 ExtractAllText() 即可获取所有文本内容,同时保持原始格式。
在 .NET 中解析 PDF 的最简单方法是什么?
最简单的方法是使用 IronPDF,只需一行代码:var text = IronPdf.FromFile("sample.pdf").ExtractAllText().该方法可从整个 PDF 文档中提取每一行文本,所需的设置极少。
我能否从 PDF 的特定页面中提取文本?
是的,IronPDF 提供了 ExtractTextFromPage 方法,用于从单个页面中提取文本。这使您可以针对 PDF 文档的特定部分进行提取,而不是一次性提取所有内容。
如何用 C# 解析受密码保护的 PDF?
IronPDF 支持解析受密码保护的 PDF。使用 PdfDocument.FromFile("protected.pdf", "password123") 加载受保护的文档,然后调用 ExtractAllText() 提取文本内容。
我能否从 URL 而不是本地文件解析 PDF?
是的,IronPDF 可以使用 PdfDocument.FromUrl("https://example.com/document.pdf") 直接从 URL 解析 PDF。从 URL 加载 PDF 后,使用 ExtractAllText() 提取文本内容。
PDF 解析器支持哪些平台?
IronPDF 支持跨多个平台的 PDF 解析,包括 Windows 应用程序、Linux、macOS 和 Azure 云部署,为您的 .NET 应用程序提供全面的跨平台兼容性。
PDF 解析器在提取过程中是否保持文本格式?
是的,IronPDF 的 ExtractAllText 方法可在提取过程中保持 PDF 内容的原始格式,确保解析后的文本保留源文件中的结构和布局。
我可以从 PDF 中提取文本和图像吗?
IronPDF 支持从 PDF 文档中提取文本和图像。除了用于文本提取的 ExtractAllText 方法外,该库还提供了从 PDF 文档的特定部分提取图像的附加功能。
What are some advanced text extraction features provided by IronPDF?
IronPDF offers advanced features like parsing text from specific page ranges, handling layered PDFs, and employing async or multithreading for performance enhancements.
Can IronPDF maintain the original PDF formatting when extracting text?
Yes, IronPDF is designed to preserve the original formatting and structure of the PDF when extracting text, making it suitable for document processing and analysis tasks.

Curtis Chau 拥有卡尔顿大学的计算机科学学士学位,专注于前端开发,精通 Node.js、TypeScript、JavaScript 和 React。他热衷于打造直观且美观的用户界面,喜欢使用现代框架并创建结构良好、视觉吸引力强的手册。



