
C# PDF解析器

在C#中使用IronPDF的ExtractAllText方法解析PDF文件,以提取整個文件或特定頁面的文字。 這種方法為.NET應用程式提供簡單且高效的PDF文字提取,只需少量程式碼。
IronPDF使得在C#應用程式中解析PDF變得簡單直接。 本教程演示如何使用IronPDF,一個完整的C#程式庫,用於PDF生成和操作來解析PDF,只需幾個步驟。
快速入門:使用IronPDF高效解析PDF使用IronPDF在C#中開始解析PDF,只需最少的程式碼。 此範例顯示如何從PDF文件中提取所有文字,同時保持其原始格式。 IronPDF的ExtractAllText方法使得在.NET應用程式中無縫整合PDF解析。 按照這些步驟進行簡單的設置和操作。
-
1Install IronPDF with NuGet Package Manager
-
2複製並運行這段程式碼片段。
var text = IronPdf.FromFile("sample.pdf").ExtractAllText();C# -
3部署以在您的實時環境中測試
今天就開始在您的專案中使用IronPDF,透過免費試用
最小工作流程 (5步)
- Download C# PDF parser library
- 安裝在您的Visual Studio中
- 使用
ExtractAllText方法提取每一行文字 - 使用
ExtractTextFromPage方法從單一頁面提取所有文字 - 查看解析後的PDF內容
如何在C#中解析PDF文件?
使用IronPDF解析PDF文件非常簡單。 以下程式碼使用ExtractAllText方法從整個PDF文件中提取每一行文字。 比較結果顯示提取的PDF內容和其輸出。 該程式庫還支援從PDF文件的特定部分提取文字和圖像。
using IronPdf;

// Select the desired PDF File
PdfDocument pdf = PdfDocument.FromFile("sample.pdf");

// Extract all text from an pdf
string allText = pdf.ExtractAllText();

// Extract all text from page 1
string page1Text = pdf.ExtractTextFromPage(0);Imports IronPdf
' Select the desired PDF File
Private pdf As PdfDocument = PdfDocument.FromFile("sample.pdf")
' Extract all text from an pdf
Private allText As String = pdf.ExtractAllText()
' Extract all text from page 1
Private page1Text As String = pdf.ExtractTextFromPage(0)IronPDF簡化了在不同場景中的PDF解析。 無論是處理HTML到PDF的轉換,從現有文件中提取內容,還是實施高級PDF功能,該程式庫提供全面的支援。
IronPDF提供與Windows應用程式的無縫整合,並支援在Linux和macOS平台上部署。 該程式庫還支援用於雲端解決方案的Azure部署。
進階文字提取範例
這裡有使用IronPDF解析PDF內容的其他方式:
using IronPdf;

// Parse PDF from URL
var pdfFromUrl = PdfDocument.FromUrl("https://example.com/document.pdf");
string urlPdfText = pdfFromUrl.ExtractAllText();

// Parse password-protected PDFs
var protectedPdf = PdfDocument.FromFile("protected.pdf", "password123");
string protectedText = protectedPdf.ExtractAllText();

// Extract text from specific page range
var largePdf = PdfDocument.FromFile("large-document.pdf");
for (int i = 5; i < 10; i++)
{
    string pageText = largePdf.ExtractTextFromPage(i);
    Console.WriteLine($"Page {i + 1}: {pageText.Substring(0, 100)}...");
}Imports IronPdf
' Parse PDF from URL
Dim pdfFromUrl = PdfDocument.FromUrl("https://example.com/document.pdf")
Dim urlPdfText As String = pdfFromUrl.ExtractAllText()
' Parse password-protected PDFs
Dim protectedPdf = PdfDocument.FromFile("protected.pdf", "password123")
Dim protectedText As String = protectedPdf.ExtractAllText()
' Extract text from specific page range
Dim largePdf = PdfDocument.FromFile("large-document.pdf")
For i As Integer = 5 To 9
Dim pageText As String = largePdf.ExtractTextFromPage(i)
Console.WriteLine($"Page {i + 1}: {pageText.Substring(0, 100)}...")
Next這些範例展示了IronPDF在處理不同PDF來源和場景時的靈活性。 對於複雜的解析需求,請探索PDF DOM物件存取以處理結構化內容。
處理不同的PDF型別
IronPDF在解析各種PDF型別時表現出色:
using IronPdf;
using System.Text.RegularExpressions;

// Parse scanned PDFs with OCR (requires IronOcr)
var scannedPdf = PdfDocument.FromFile("scanned-document.pdf");
string ocrText = scannedPdf.ExtractAllText();

// Parse PDFs with forms
var formPdf = PdfDocument.FromFile("form.pdf");
string formText = formPdf.ExtractAllText();

// Extract and filter specific content
string invoiceText = pdf.ExtractAllText();
var invoiceNumber = Regex.Match(invoiceText, @"Invoice #: (\d+)").Groups[1].Value;
var totalAmount = Regex.Match(invoiceText, @"Total: \$([0-9,]+\.\d{2})").Groups[1].Value;Imports IronPdf
Imports System.Text.RegularExpressions
' Parse scanned PDFs with OCR (requires IronOcr)
Dim scannedPdf = PdfDocument.FromFile("scanned-document.pdf")
Dim ocrText As String = scannedPdf.ExtractAllText()
' Parse PDFs with forms
Dim formPdf = PdfDocument.FromFile("form.pdf")
Dim formText As String = formPdf.ExtractAllText()
' Extract and filter specific content
Dim invoiceText As String = pdf.ExtractAllText()
Dim invoiceNumber = Regex.Match(invoiceText, "Invoice #: (\d+)").Groups(1).Value
Dim totalAmount = Regex.Match(invoiceText, "Total: \$([0-9,]+\.\d{2})").Groups(1).Value如何查看解析的PDF內容?
一個C#表單顯示了來自上述程式碼執行的解析後的PDF內容。 此輸出提供了PDF文件中確切的文字以滿足文件處理需求。
~ PDF ~
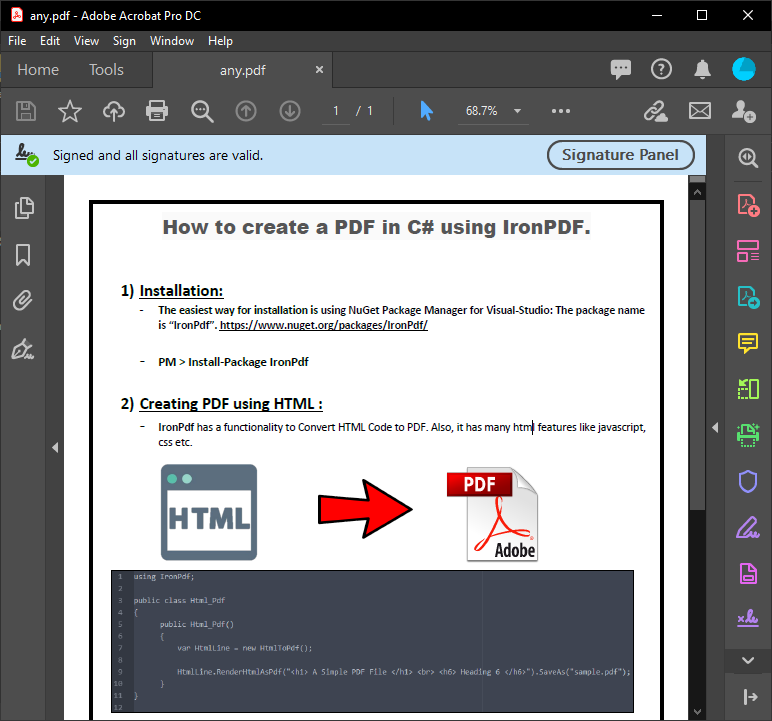
~ C# 表單 ~
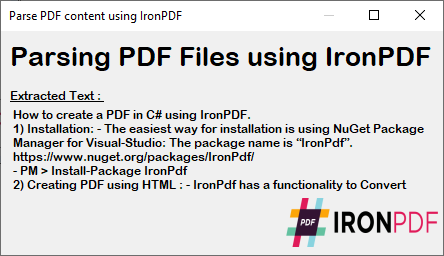
提取的文字保持了來自PDF的原始格式和結構,這使得它非常適合於資料處理、內容分析或遷移任務。 通過查找和替換特定內容或者導出到其他格式來進一步處理此文字。
將PDF解析整合到您的應用程式中
IronPDF的解析能力可整合到各種應用程式型別中:
// ASP.NET Core example
public IActionResult ParseUploadedPdf(IFormFile pdfFile)
{
    using var stream = pdfFile.OpenReadStream();
    var pdf = PdfDocument.FromStream(stream);

    var extractedText = pdf.ExtractAllText();

    // Process or store the extracted text
    return Json(new {
        success = true,
        textLength = extractedText.Length,
        preview = extractedText.Substring(0, Math.Min(500, extractedText.Length))
    });
}

// Console application example
static void BatchParsePdfs(string folderPath)
{
    var pdfFiles = Directory.GetFiles(folderPath, "*.pdf");

    foreach (var file in pdfFiles)
    {
        var pdf = PdfDocument.FromFile(file);
        var text = pdf.ExtractAllText();

        // Save extracted text
        var textFile = Path.ChangeExtension(file, ".txt");
        File.WriteAllText(textFile, text);

        Console.WriteLine($"Parsed: {Path.GetFileName(file)} - {text.Length} characters");
    }
}' ASP.NET Core example
Public Function ParseUploadedPdf(pdfFile As IFormFile) As IActionResult
Using stream = pdfFile.OpenReadStream()
Dim pdf = PdfDocument.FromStream(stream)
Dim extractedText = pdf.ExtractAllText()
' Process or store the extracted text
Return Json(New With {
.success = True,
.textLength = extractedText.Length,
.preview = extractedText.Substring(0, Math.Min(500, extractedText.Length))
})
End Using
End Function
' Console application example
Shared Sub BatchParsePdfs(folderPath As String)
Dim pdfFiles = Directory.GetFiles(folderPath, "*.pdf")
For Each file In pdfFiles
Dim pdf = PdfDocument.FromFile(file)
Dim text = pdf.ExtractAllText()
' Save extracted text
Dim textFile = Path.ChangeExtension(file, ".txt")
File.WriteAllText(textFile, text)
Console.WriteLine($"Parsed: {Path.GetFileName(file)} - {text.Length} characters")
Next
End Sub這些範例顯示了PDF解析在Web應用程式和批量處理場景中的應用。 對於高級實施,請探索異步和多執行緒技術,以提高處理多個PDF時的性能。
準備好看看您還能做什麼嗎? 查看我們的教程頁面:編輯PDF
常見問題
如何在 C# 中從 PDF 文件提取所有文字?
您可以使用 IronPDF 的 ExtractAllText 方法從 PDF 文件中提取所有文字。只需使用 IronPdf.FromFile("sample.pdf") 載入您的 PDF,然後調用 ExtractAllText() 即可檢索所有文字內容,同時維持原始格式。
在 .NET 中解析 PDF 的最簡單方法是什麼?
最簡單的方法是使用 IronPDF,只需一行程式碼:var text = IronPdf.FromFile("sample.pdf").ExtractAllText(). 此方法在整個 PDF 文件中提取每一行的文字,所需設定最小。
我可以從 PDF 的特定頁面中提取文字嗎?
可以,IronPDF 提供了 ExtractTextFromPage 方法以從單頁提取文字。這讓您可以針對 PDF 文件中的特定部分進行提取,而非一次提取所有內容。
如何在 C# 中解析受密碼保護的 PDF?
IronPDF 支持解析受密碼保護的 PDF。使用 PdfDocument.FromFile("protected.pdf", "password123") 載入受保護的文件,然後調用 ExtractAllText() 提取文字內容。
我可以從 URL 而不是本地文件中解析 PDF 嗎?
可以,IronPDF 能夠直接從 URL 中解析 PDF,使用 PdfDocument.FromUrl("https://example.com/document.pdf")。從 URL 載入 PDF 後,使用 ExtractAllText() 提取文字內容。
PDF 解析器支持哪些平台?
IronPDF 支援跨多平台的 PDF 解析,包括 Windows 應用程式、Linux、macOS 和 Azure 雲端部署,為 .NET應用提供全面的跨平台相容性。
PDF 解析器在提取過程中是否維持文字格式?
是的,IronPDF 的 ExtractAllText 方法在提取過程中維持了 PDF 內容的原始格式,確保解析的文字保持來源檔案的結構與佈局。
我可以從 PDF 中提取文字和圖像嗎?
IronPDF 支援從 PDF 文件中提取文字和圖像。除了用於文字提取的 ExtractAllText 方法外,程式庫還提供了從 PDF 文件特定部分提取圖像的附加功能。
What are some advanced text extraction features provided by IronPDF?
IronPDF offers advanced features like parsing text from specific page ranges, handling layered PDFs, and employing async or multithreading for performance enhancements.
Can IronPDF maintain the original PDF formatting when extracting text?
Yes, IronPDF is designed to preserve the original formatting and structure of the PDF when extracting text, making it suitable for document processing and analysis tasks.

Curtis Chau擁有Carleton大學的電腦科學學士學位,專精於前端開發,擁有Node.js、TypeScript、JavaScript和React的專業知識。Curtis熱衷於建立直觀且美觀的使用者介面,喜愛使用現代框架並建立結構良好、視覺吸引力的手冊。



